Evolve your data platform with a Deployment Capability
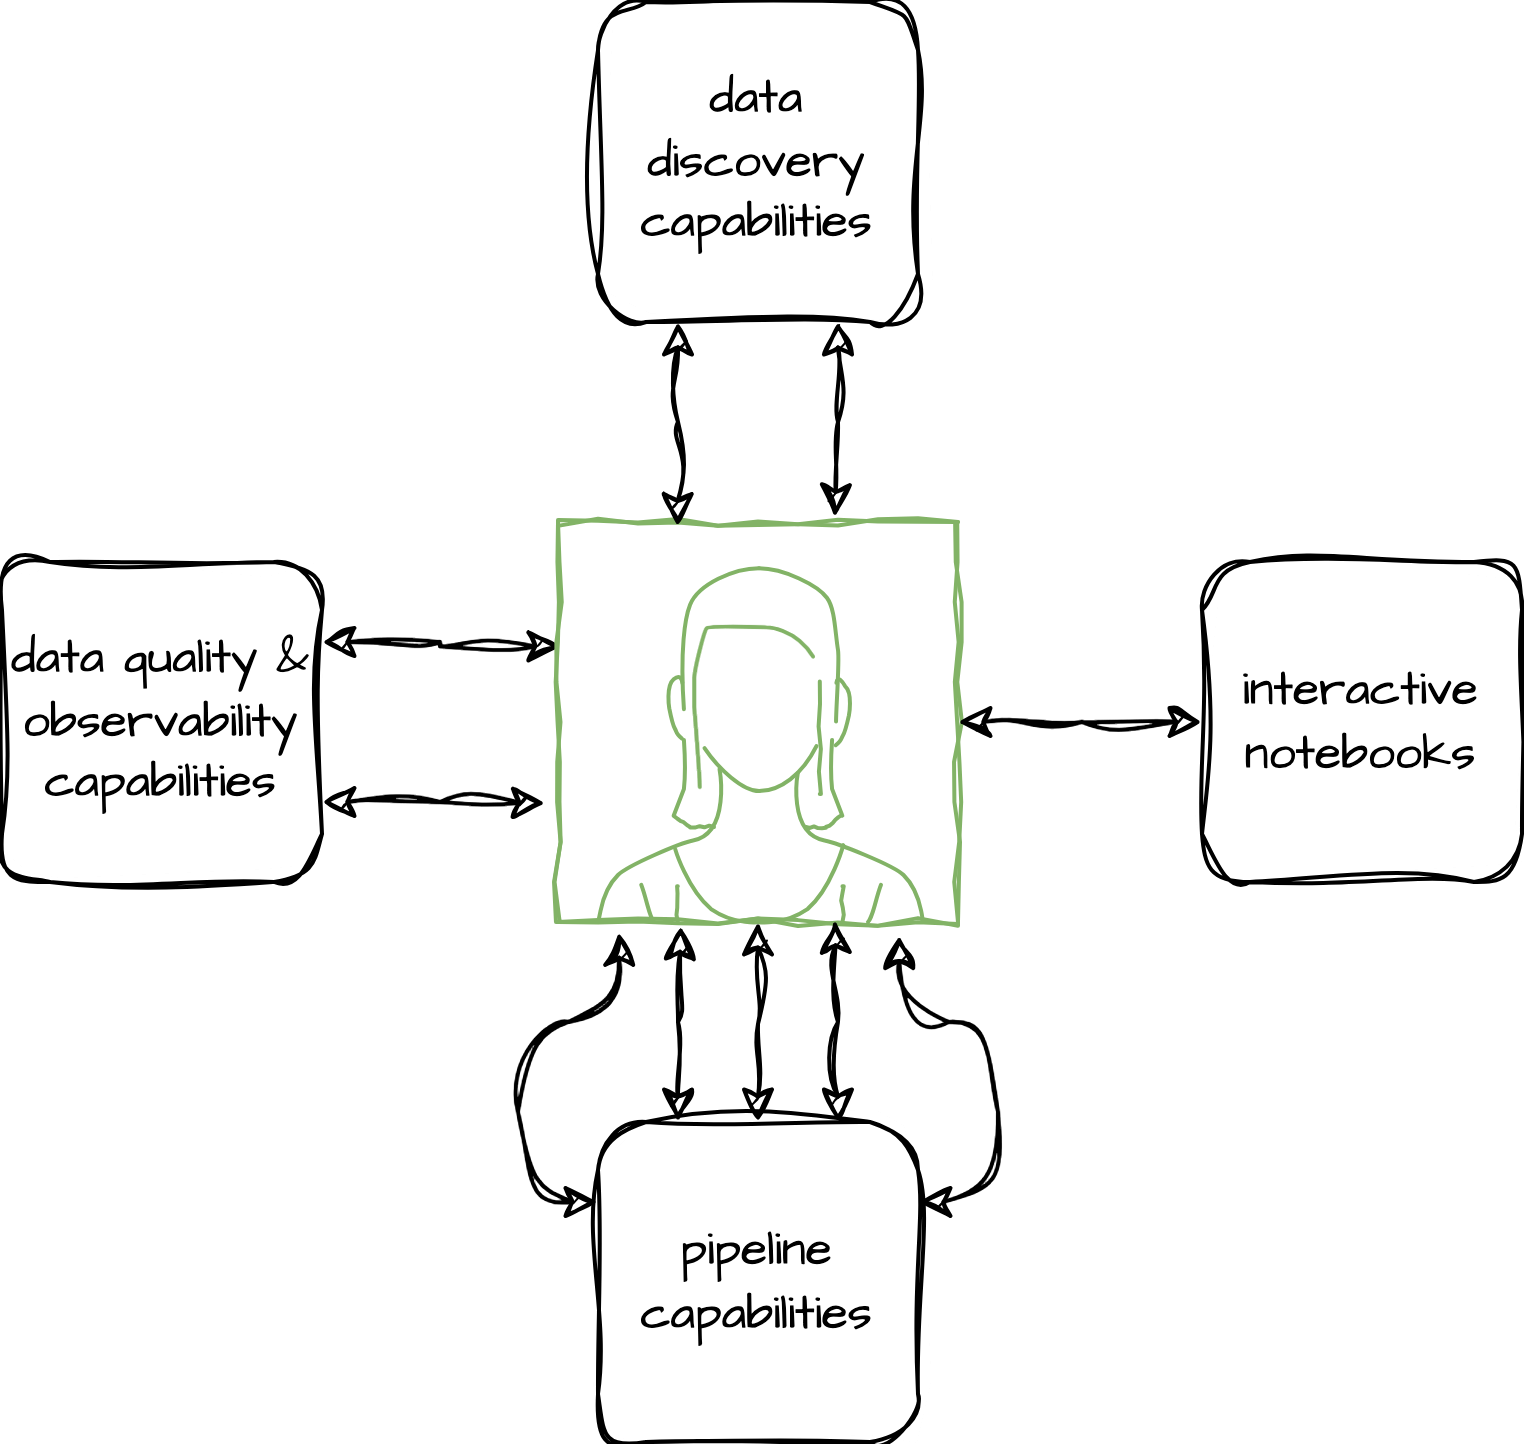
This post introduces a novel deployment capability for Atlassian's data platform, inspired by Kubernetes and Micros but tailored for the data domain. This capability offers a declarative, metadata-driven, self-serve system for provisioning data pipelines, an extensible abstraction over execution capabilities, and a single governed deployment experience. It addresses the challenges of data discovery, trust, and user experience by modeling user workflows and collecting rich metadata. The system uses configuration metadata to decouple users from pipeline execution capabilities, allowing for easier platform upgrades. It also emphasizes upfront metadata capture for data discovery and governance, moving away from post-deployment inspection. The model includes entities like pipelines, steps, outputs (tables), databases, columns, and data products, with a schema for each. The implementation interfaces with execution capabilities like dbt via keywords in configuration files, providing an extensible mechanism for adding new capabilities.