Introducing Baseten Hybrid: control and flexibility in your cloud and ours
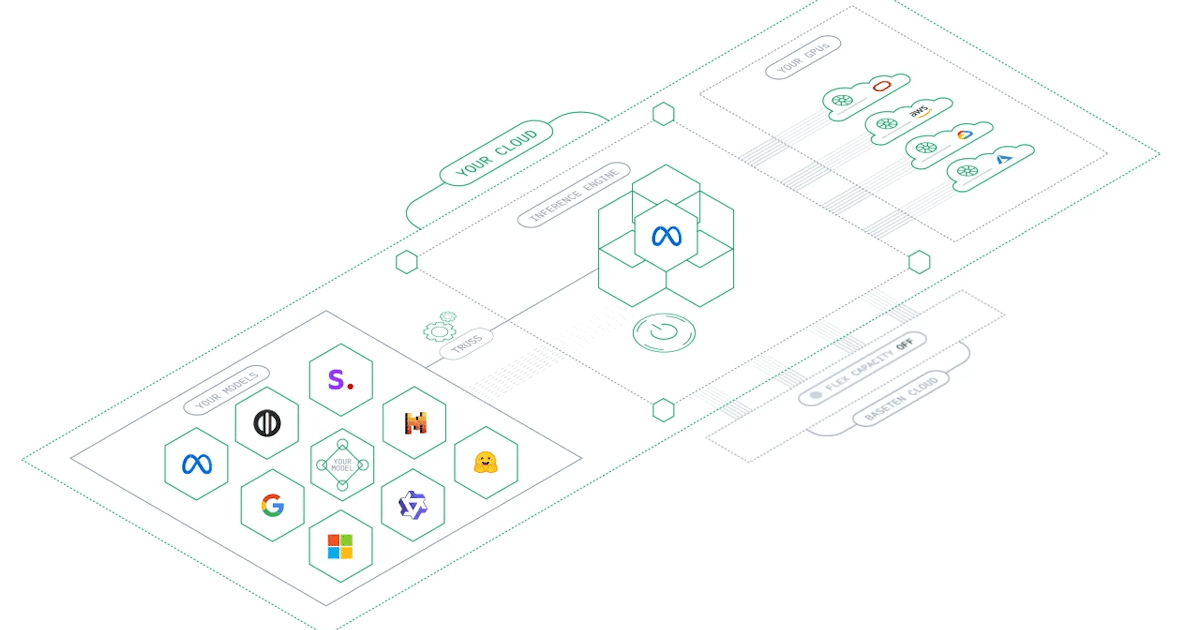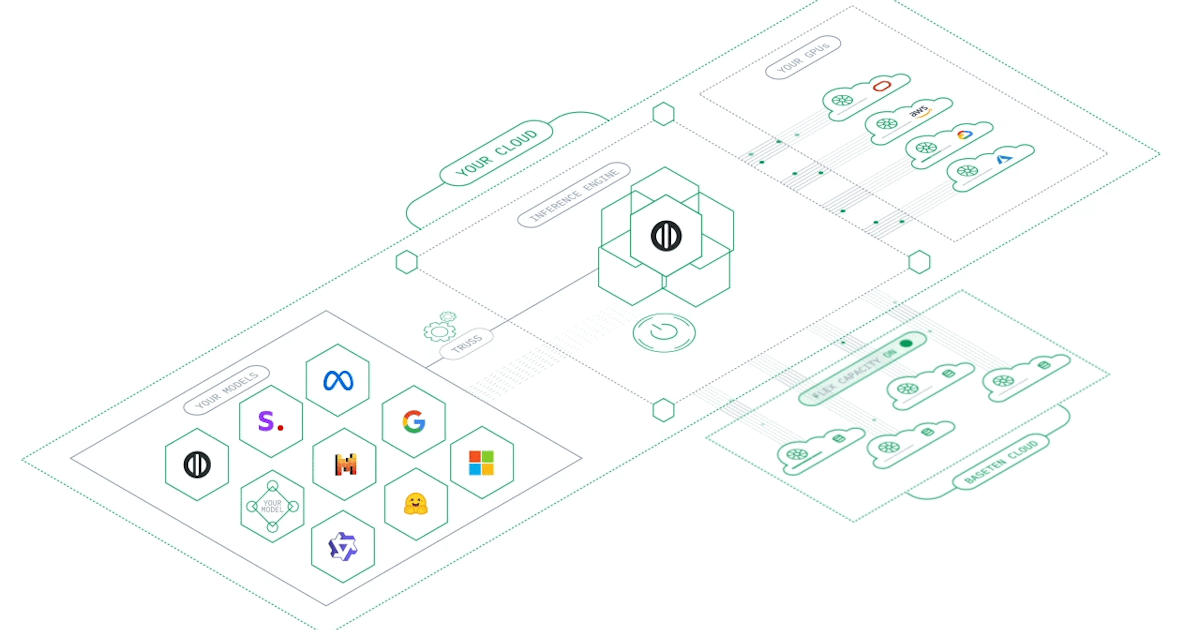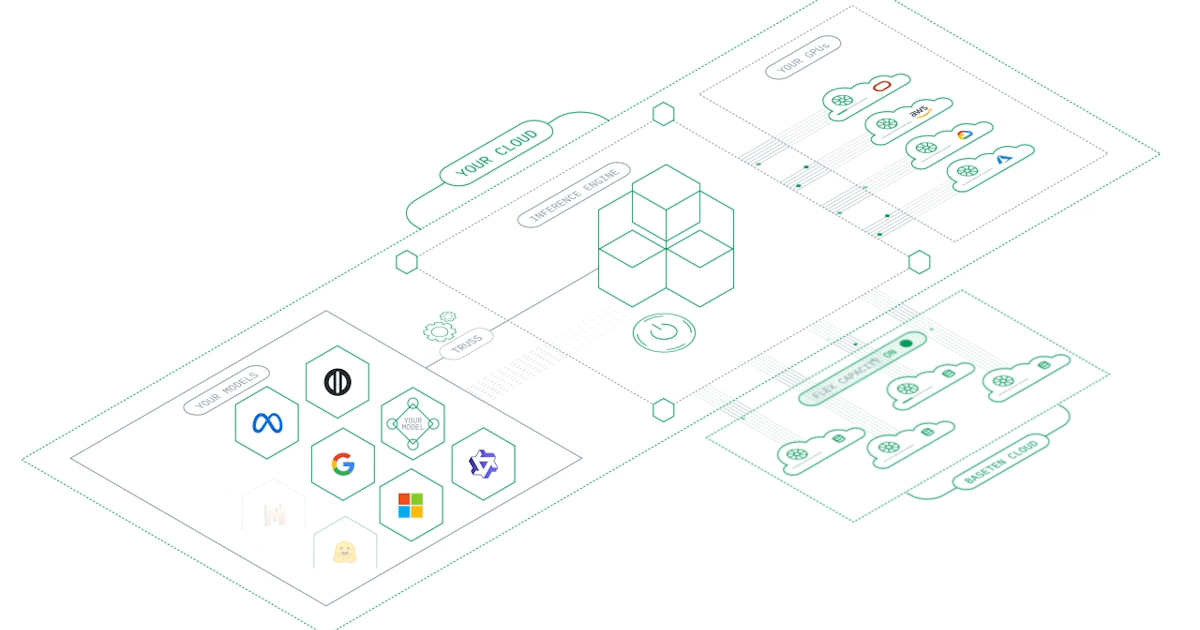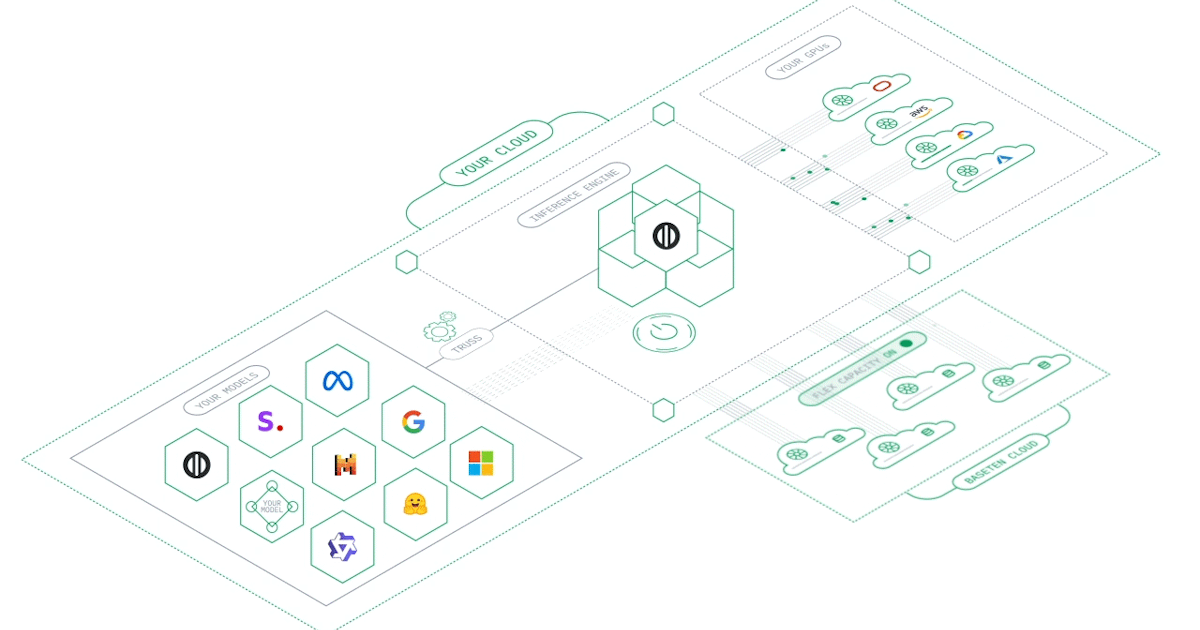
This post introduces Baseten Hybrid, a new capability that combines Baseten Self-hosted and Baseten Cloud into a unified multi-cloud solution. It allows users to run inference workloads within their own VPC for security and compliance, with the ability to seamlessly spill over to Baseten Cloud for additional compute capacity during traffic spikes. This provides multi-cloud elasticity and agnosticism, enabling users to leverage existing cloud credits and GPU commits from providers like AWS and GCP without engineering effort. The system aims to provide ultra-low-latency inference with elastic scale, utilizing optimization techniques like TensorRT/TensorRT-LLM and vLLM, and includes improvements for cold starts and end-to-end latency. It also supports compound AI systems built with Baseten Chains.
More from the Multi-cloud Capacity Management (MCM) trail
- How Baseten MCM, our cloud ecosystem partners, and NVIDIA drive fast, reliable inference at scale
- How we built Multi-cloud Capacity Management (MCM)
- How Baseten multi-cloud capacity management (MCM) unifies deployments
- Introducing Baseten Self-hosted
- Control plane vs workload plane in model serving infrastructure