Optimizing delta weight syncs for managed rollouts
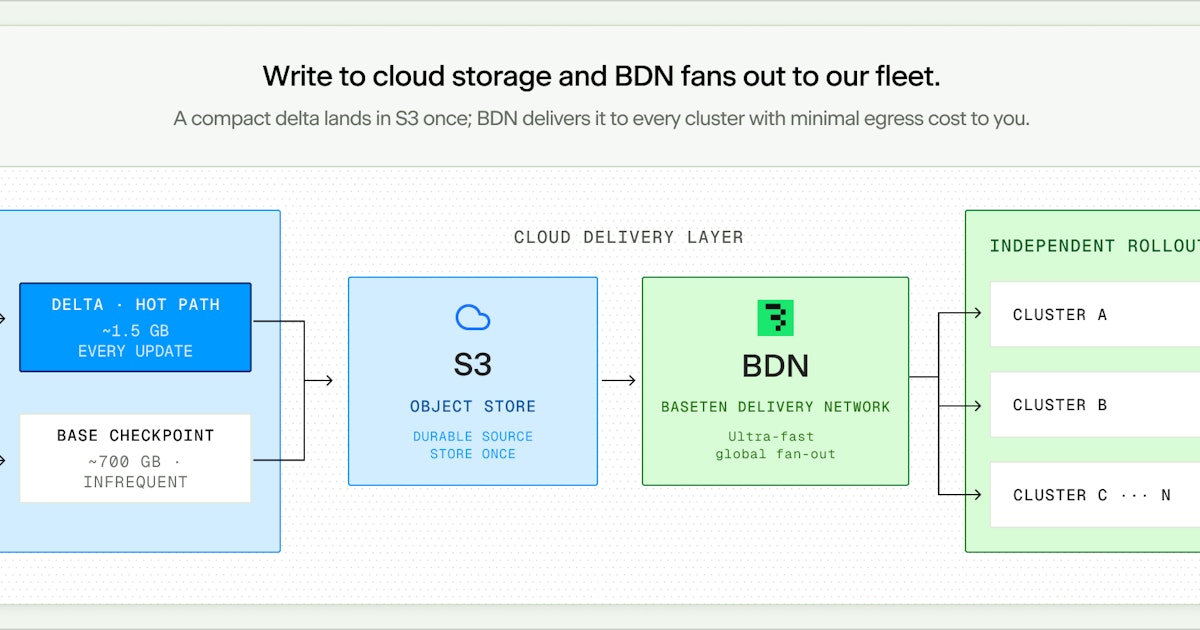
This post details Baseten's implementation of delta weight synchronization for managed rollouts of large AI models. It describes a system that allows trainers to publish checkpoints or deltas to object storage, which are then distributed to independent rollout clusters via the Baseten Delivery Network. A key technical innovation is the custom zstd decoder that efficiently processes XOR-encoded weight differences, avoiding the materialization and scanning of the full model. This sparse decoding approach, combined with optimized GPU update strategies that group changes by destination and serialize updates for retry safety, significantly reduces the request pause time during model updates from ~12 seconds to ~6 seconds, achieving full fleet updates in under 40 seconds.
More from the Baseten AI Model Deployment and Serving Platform trail
- LangChain trains custom models for LangSmith Engine with Baseten Loops
- DeepSeek-V4.1-Flash: more efficient prefill for coding agents
- Blaxel is joining Baseten to build the future of agentic infrastructure
- How Baseten makes pyannote’s diarization models 9.6x faster
- Baseten leads Coval’s voice AI benchmark