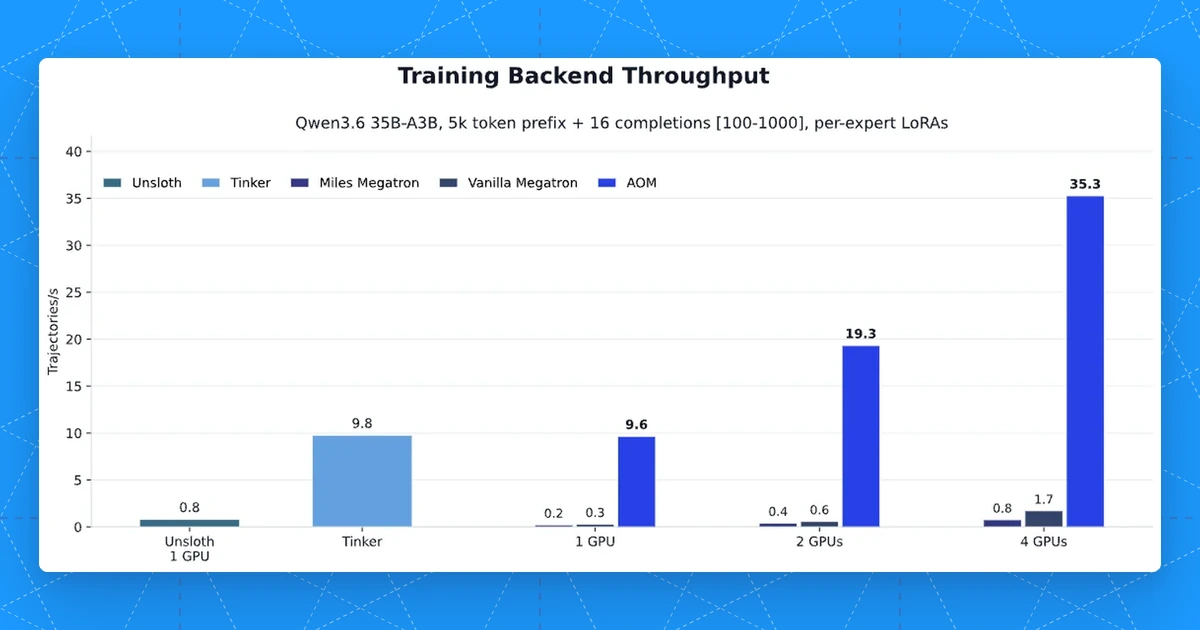
ART-Optimized Megatron (AOM): 12x higher training throughput
Oct 2, 2026
Summary
Introduced ART-Optimized Megatron (AOM) as a new backend for the ART training library, achieving 12x higher training step throughput. Implemented shared prefix training using PyTorch's FlexAttention and custom Gated DeltaNet (GDN) layer modifications to handle non-linear tree layouts, significantly increasing trajectory density. Optimized packed sequence length for maximum GPU throughput and tuned parallelism configurations for improved trajectories per second. This builds upon existing distributed training resiliency efforts by directly enhancing the training throughput component.
More from the Distributed Training Resiliency trail
- CoreWeave: Only Provider with 3x Platinum ClusterMAX | Blog
- Video Captioning at Scale: 600 TB in 95 Minutes | CoreWeave Blog
- NVIDIA, CoreWeave, and AI Factory Operations at Scale
- GPU Stragglers and Training Failures Explained
- CoreWeave SUNK adds new capabilities for modern AI research clusters | CoreWeave Blog