Granular Usage Attribution for dbt Pipelines with Query Tags - Cloned
Apr 21, 2024
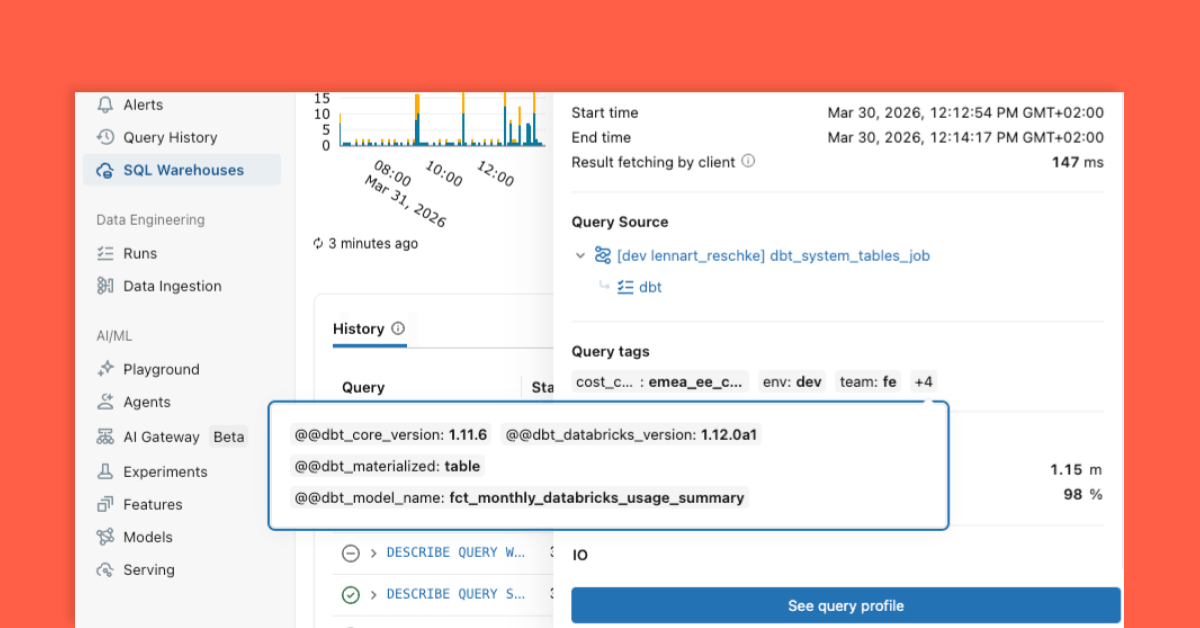
Summary
This post introduces the use of query tags in Databricks to achieve granular usage attribution for dbt pipelines. It explains how these tags are applied to queries executed by dbt, allowing for the association of compute and storage costs with specific dbt models or jobs. The technical details likely involve how Databricks' query engine processes and reports on these tags, and how this data is integrated into the Lakebase system for billing and analysis.
More from the Lakebase trail
- Load terabytes of data in minutes into Lakebase Postgres
- How to build governed enterprise apps on Databricks with Replit and Lakebase
- Lakebase Postgres branch-based restores for fast recovery at scale
- A practical guide to cost optimization with Lakebase Postgres
- Lakebase Search: State-of-the-art full text and vector search for Postgres