Our AI Research: How We Evaluate Semantic Search Technology
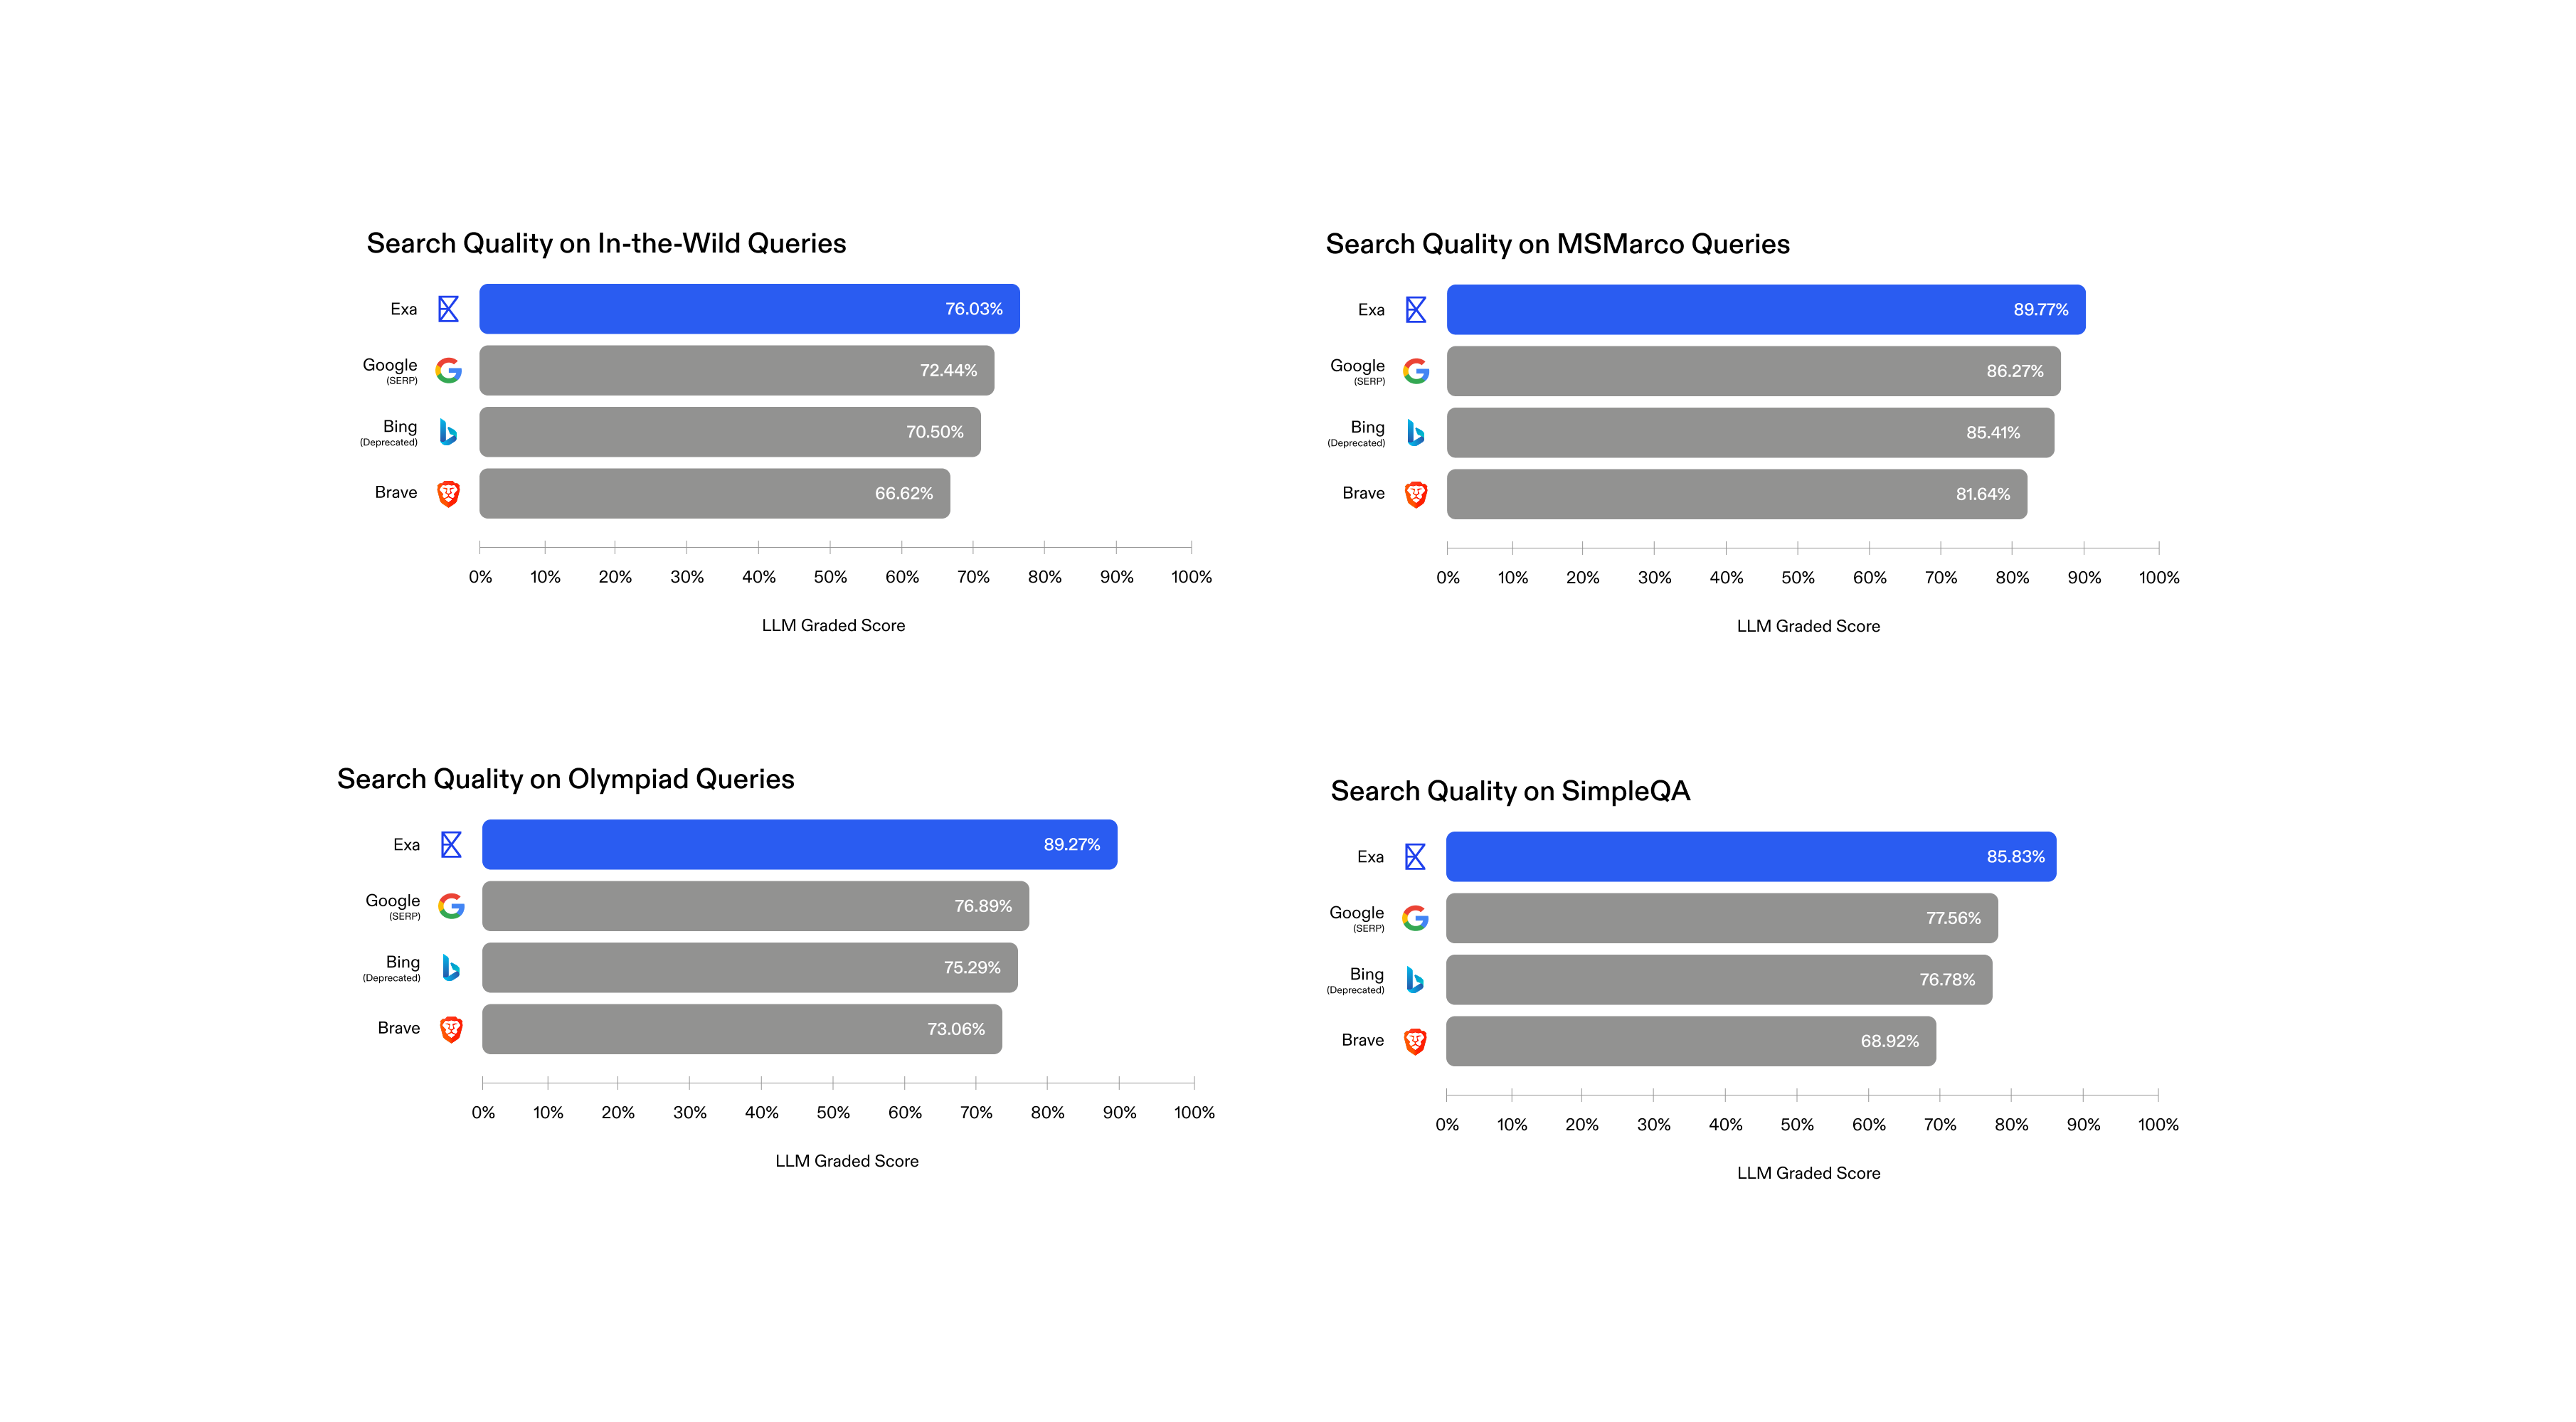
This post details Exa's methodology for evaluating semantic search technology, specifically for academic publications. It introduces two primary evaluation approaches: pure result grading using LLM graders on various query sets (in-the-wild, MS Marco, Exa Olympiad) and RAG grading using LLM agents with search results for question answering. The post also outlines Exa's evaluation philosophy, advocating for downstream task integration and granular feedback, and critiques traditional closed evaluation methods like MS Marco for their limitations regarding false negatives, scale, and distribution mismatch. The core contribution is the technical depth on how Exa measures and iterates on its search engine's quality, particularly for academic content.