A Lean and Scalable Data Pipeline to Capture Large Scale Events and Support Experimentation Platform
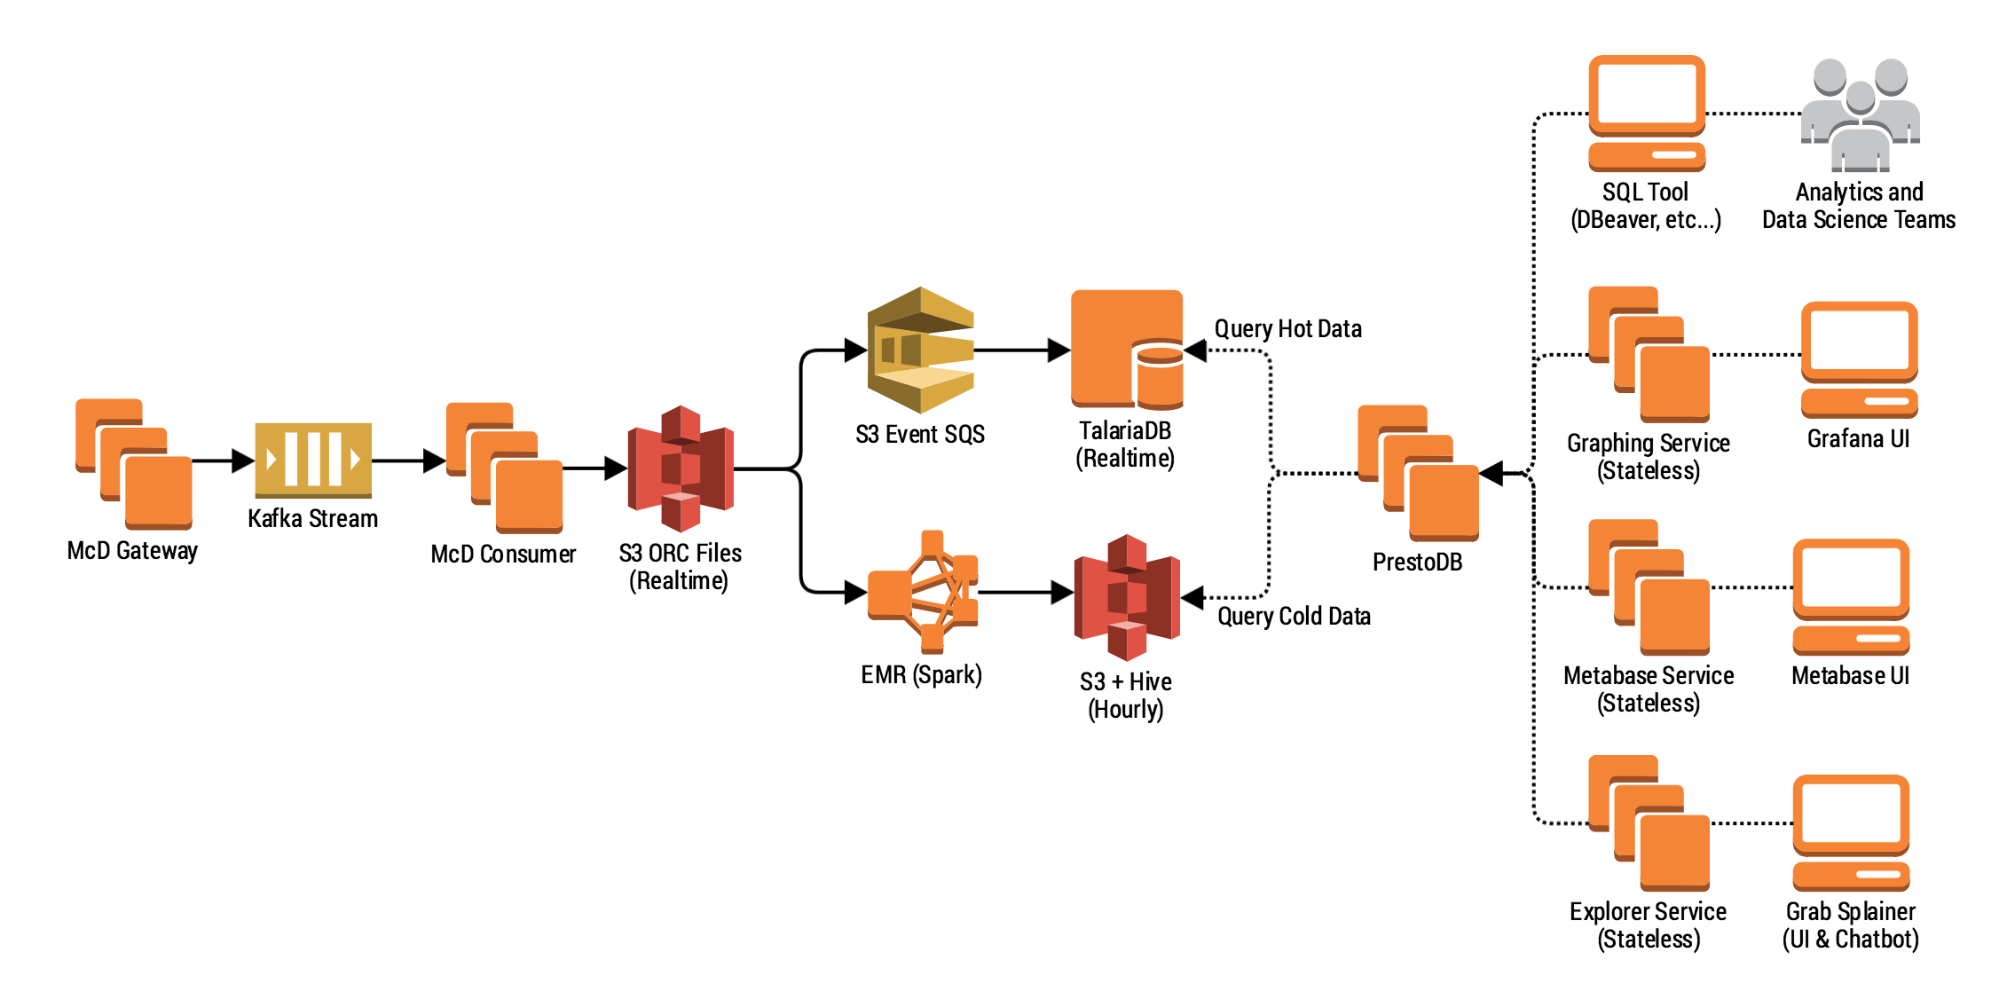
This post details the evolution of Grab's batch data pipeline supporting the Experimentation Platform (ExP). It describes the design requirements driven by various user access patterns (data analysts, data scientists, QA/support engineers, monitoring systems, expert systems) and their respective SLAs. The pipeline uses Apache Spark for compute, Apache Hive for metastore, and Apache Airflow for workflow orchestration, running on AWS EMR. Key technical contributions include partitioning data by event type and ingestion time to optimize query performance and enable efficient data retrieval, and leveraging Spark's partitioning and sorting features. The system writes data to Amazon S3 and metadata to a metastore, aiming for a one-hour lag for most applications and a few hours for data analysts.
More from the Feature Toggles and A/B Testing Platform trail
- Grab Experiment Decision Engine - a Unified Toolkit for Experimentation
- Streamlining Grab's Segmentation Platform with faster creation and lower latency
- Automated Experiment Analysis - Making experimental analysis scalable
- Automating Multi-Armed Bandit testing during feature rollout
- Reliable and Scalable Feature Toggles and A/B Testing SDK at Grab