Querying Big Data in Real-time with Presto & Grab's TalariaDB
Jan 2, 2019Roman Atachiants
Summary
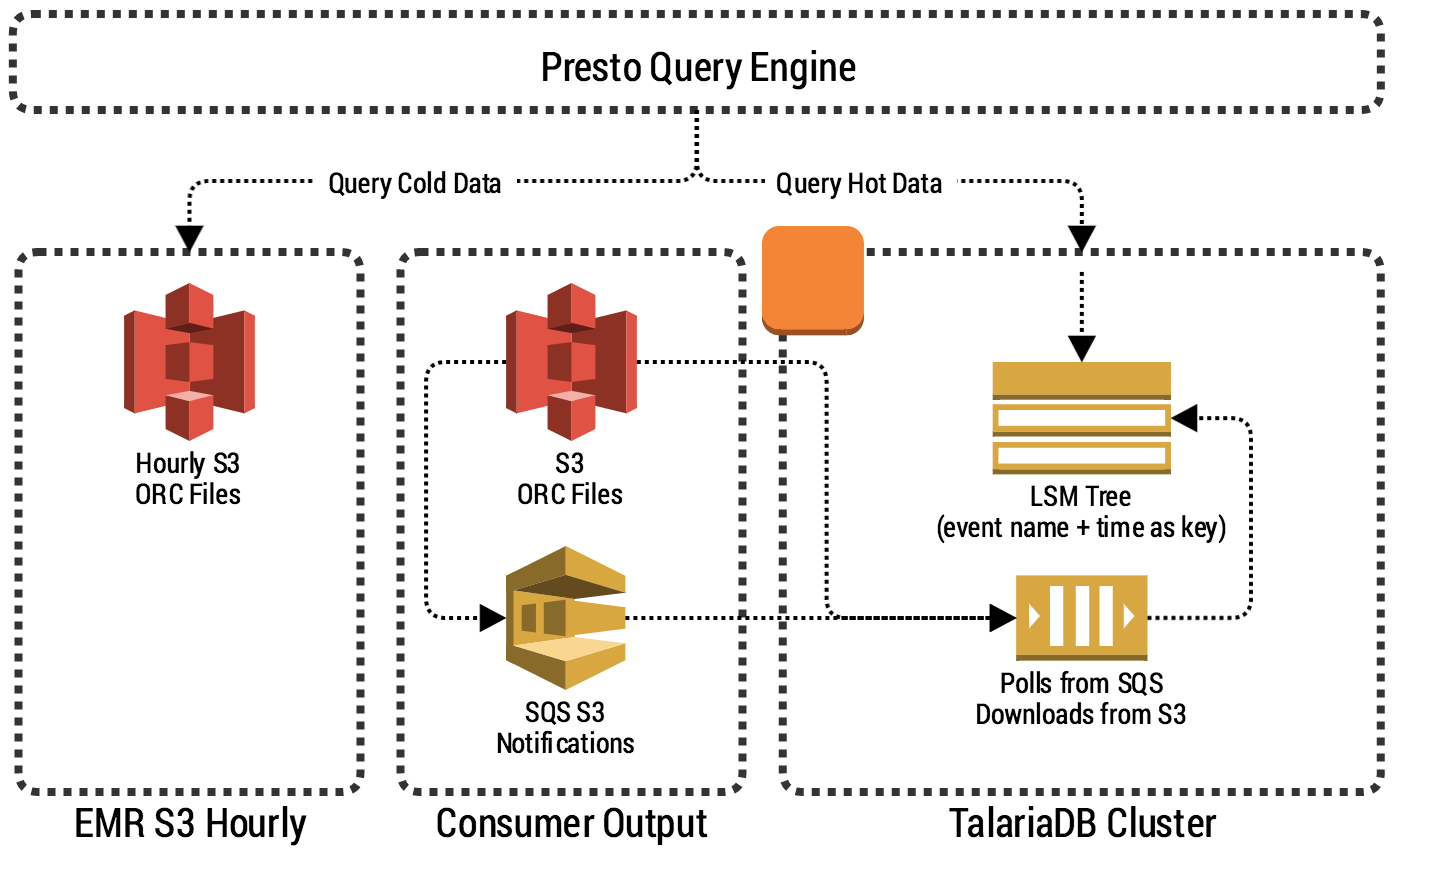
This post details the design and implementation of TalariaDB, a distributed, highly available, and low-latency time-series database for storing real-time data like logs, metrics, and click streams. TalariaDB addresses the need to query terabytes of data per hour with predictable low latency and cost, storing data in pre-partitioned batches in a binary, columnar format. It leverages the Badger key-value store and integrates with Presto via the Presto Thrift Connector for SQL querying. The system focuses on simplicity, linear horizontal scalability, low latency, availability, zero operation, high write throughput, and cost-effectiveness.
More from the Data Lake Modernization with Apache Iceberg trail
- The Hugo evolution: Engineering Grab's unified, one-click data ingestion platform with Apache Flink
- Scaling Grab's Data Lake: Our journey to Apache Iceberg adoption
- Enabling near real-time data analytics on the data lake
- Rethinking Stream Processing: Data Exploration
- 2.3x faster using the Go plugin to replace Lua virtual machine