Post-Training RLM Agents for End-to-End M&A Diligence
Sep 8, 2026
Summary
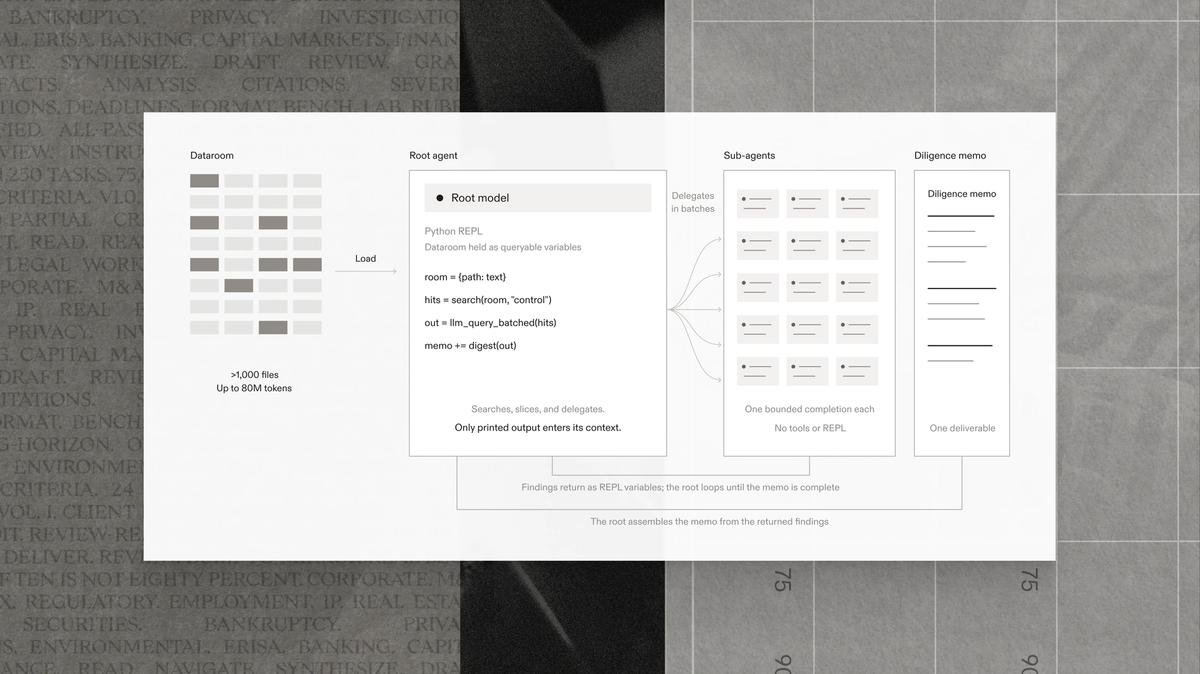
This post details the technical process of applying post-training techniques, specifically reinforcement learning and self-distillation SFT, within a recursive language model (RLM) harness for M&A diligence. It introduces the LAB Diligence environment with large document contexts and evaluates the performance gains achieved by post-training a Qwen3.5-122B-A10B orchestrator, increasing rubric criteria pass rate from 29.9% to 63.0%. The post also analyzes the division of labor between root and sub-agents in the RLM harness and discusses coverage and cost implications.