Accelerating PyTorch Transformers with Intel Sapphire Rapids - part 2
Feb 6, 2023
Summary
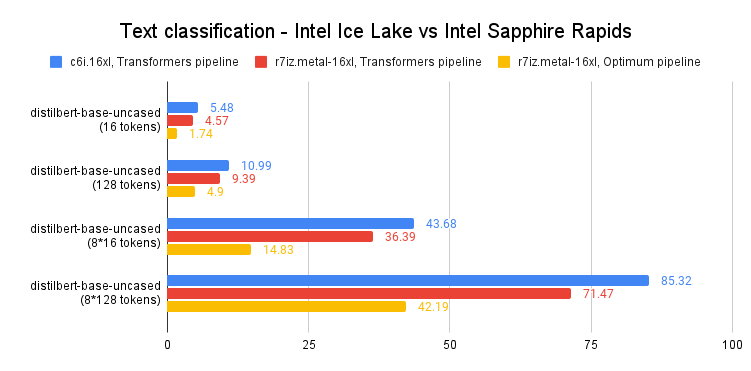
This post benchmarks inference performance of popular PyTorch Transformers models on Intel Sapphire Rapids CPUs using Hugging Face Optimum Intel. It demonstrates a 60-65% speedup for single predictions and achieves single-digit prediction latency, comparable to GPUs, by leveraging AMX instructions with bfloat16 and JIT compilation. The post provides detailed setup instructions, benchmarking methodology, and full results for various models and sequence lengths.
More from the IPU-Ready Transformers Optimization trail
- Optimum+ONNX Runtime - Easier, Faster training for your Hugging Face models
- Accelerating PyTorch Transformers with Intel Sapphire Rapids - part 1
- Accelerate your models with 🤗 Optimum Intel and OpenVINO
- Pre-Train BERT with Hugging Face Transformers and Habana Gaudi
- Deep Dive: Vision Transformers On Hugging Face Optimum Graphcore