Illustrating Reinforcement Learning from Human Feedback (RLHF)
May 26, 2023
Summary
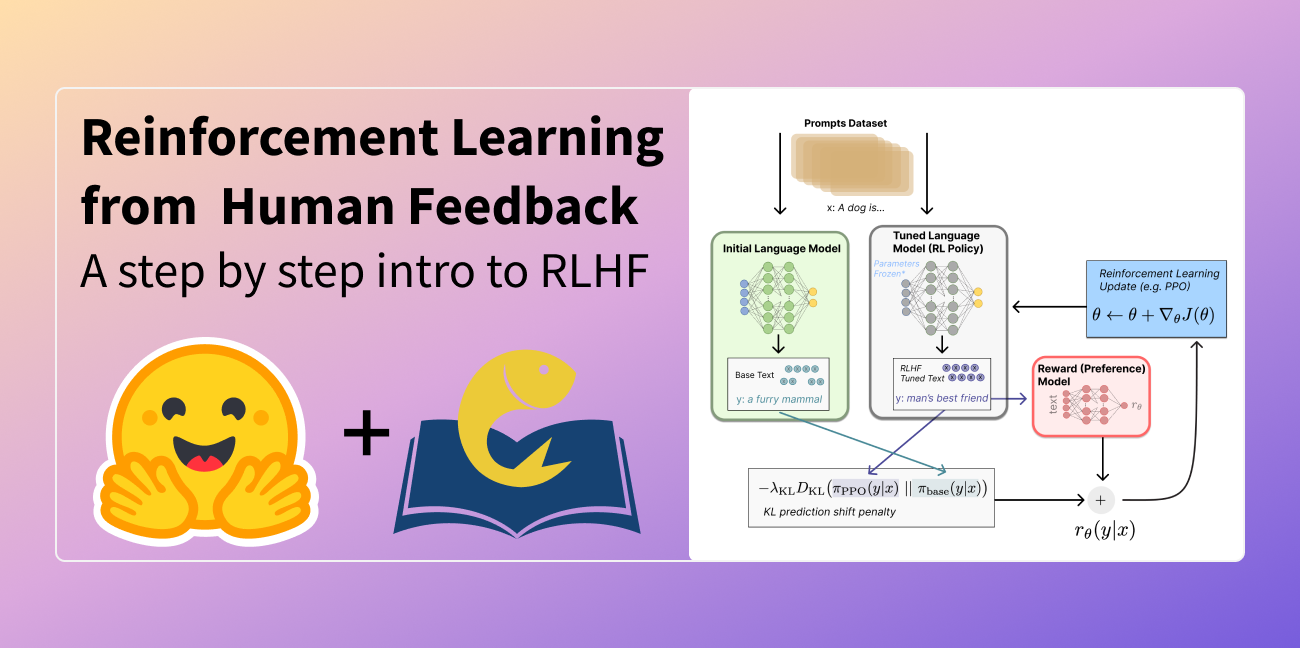
This post details the practical application and understanding of Reinforcement Learning from Human Feedback (RLHF) for aligning dialog agent behavior with human preferences. It elaborates on the use of preference datasets and reward modeling to guide agent responses, building upon previous discussions of Instruction Fine-Tuning (IFT) and Supervised Fine-Tuning (SFT).