Aria Presto: Making table scan more efficient
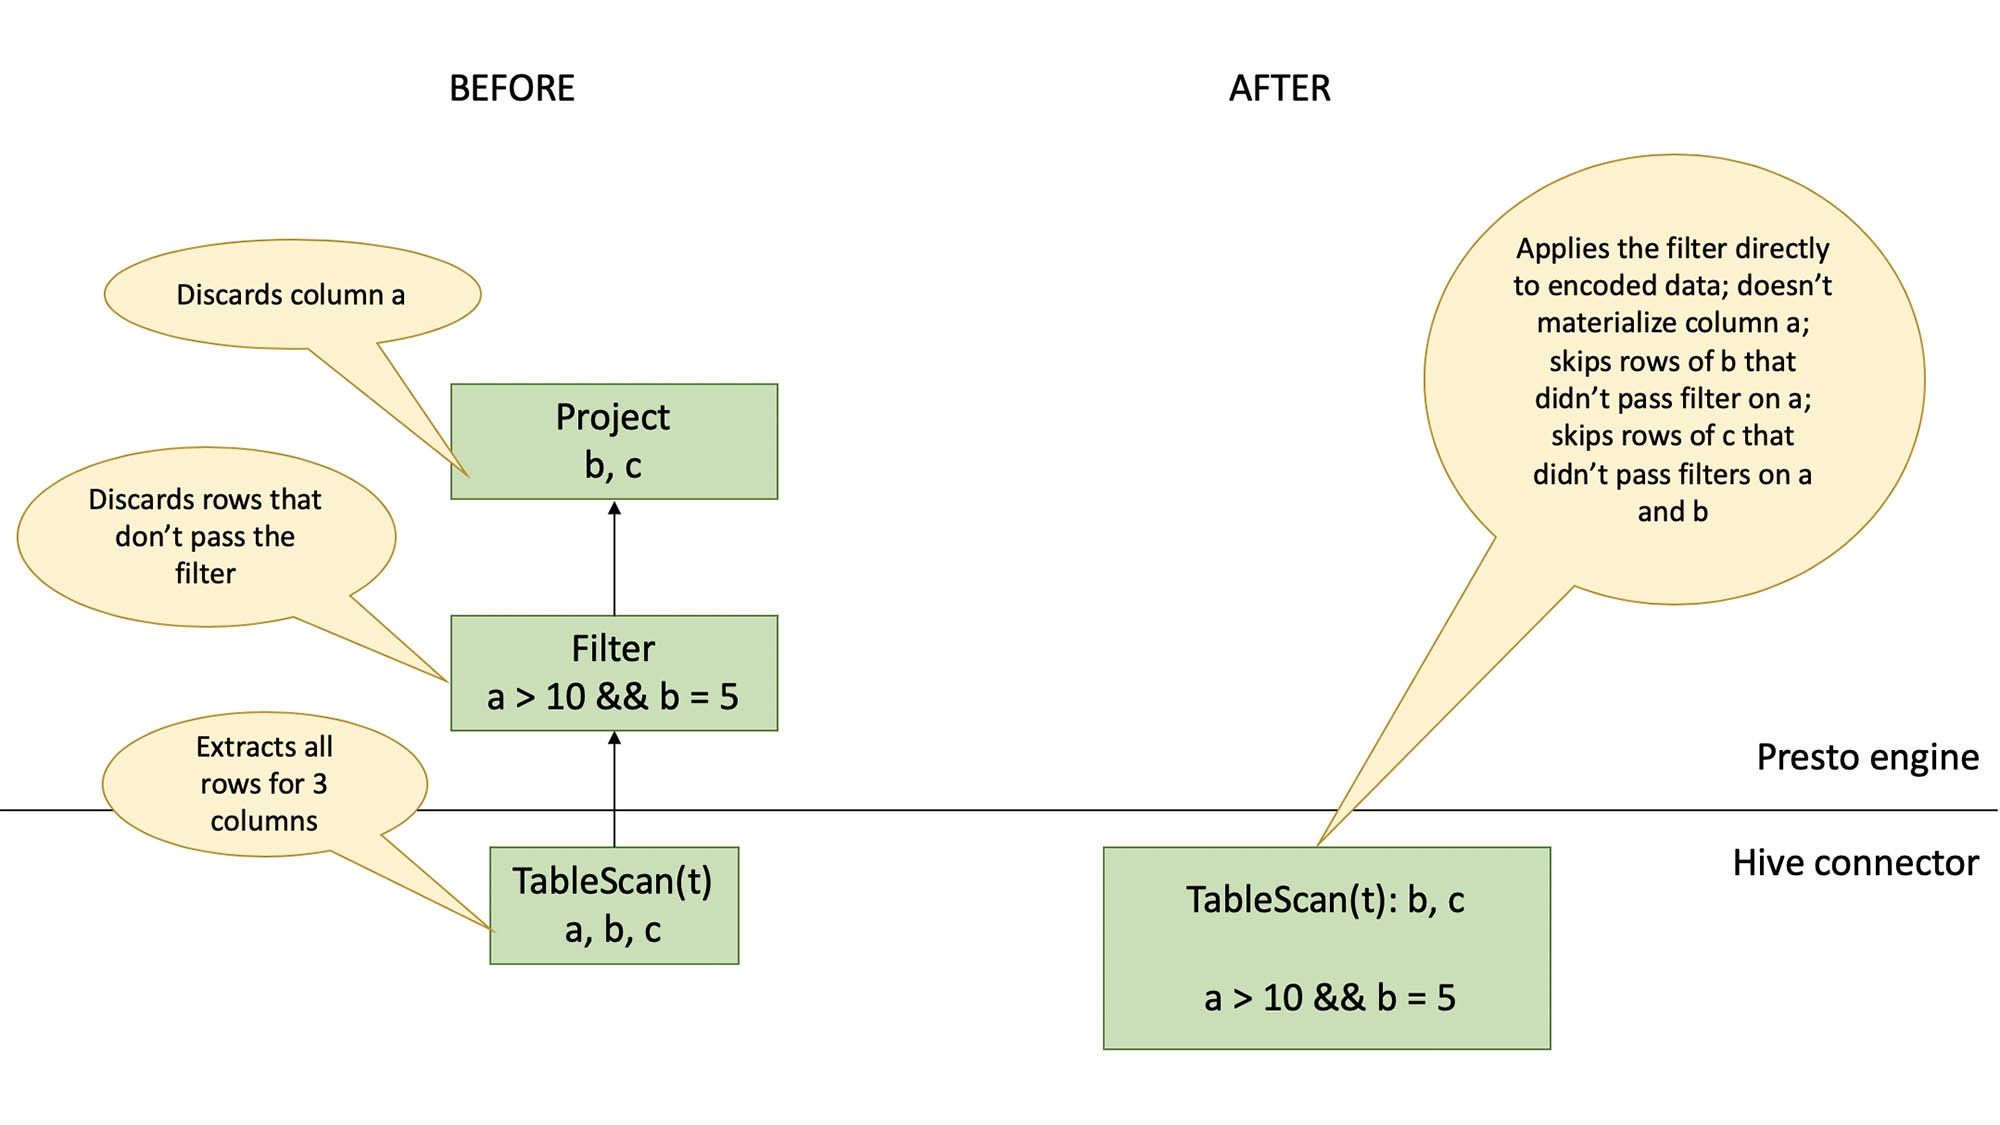
This post introduces optimizations for Aria Presto's table scan efficiency, specifically for ORC format data. Key contributions include: 1. Subfield pruning: Extracting only referenced complex type subfields (e.g., specific map keys) instead of entire complex types. 2. Adaptive filter ordering: Dynamically reordering filter evaluation to prioritize filters that drop more rows with fewer CPU cycles. 3. Efficient row skipping: Reading and discarding only necessary values for rows that pass filters, rather than reading entire rows and then discarding them. These optimizations are implemented by shifting filter evaluation into the Hive connector and introducing a stream reader responsible for applying simple filters and producing filtered row number arrays. A record reader coordinates stream readers, tracks filter efficiency, and handles multi-column filter functions. A working prototype shows ~20% CPU gains on production workloads.