Building Meta’s GenAI Infrastructure
Mar 12, 2024Kevin Lee, Adi Gangidi, Mathew Oldham
Summary
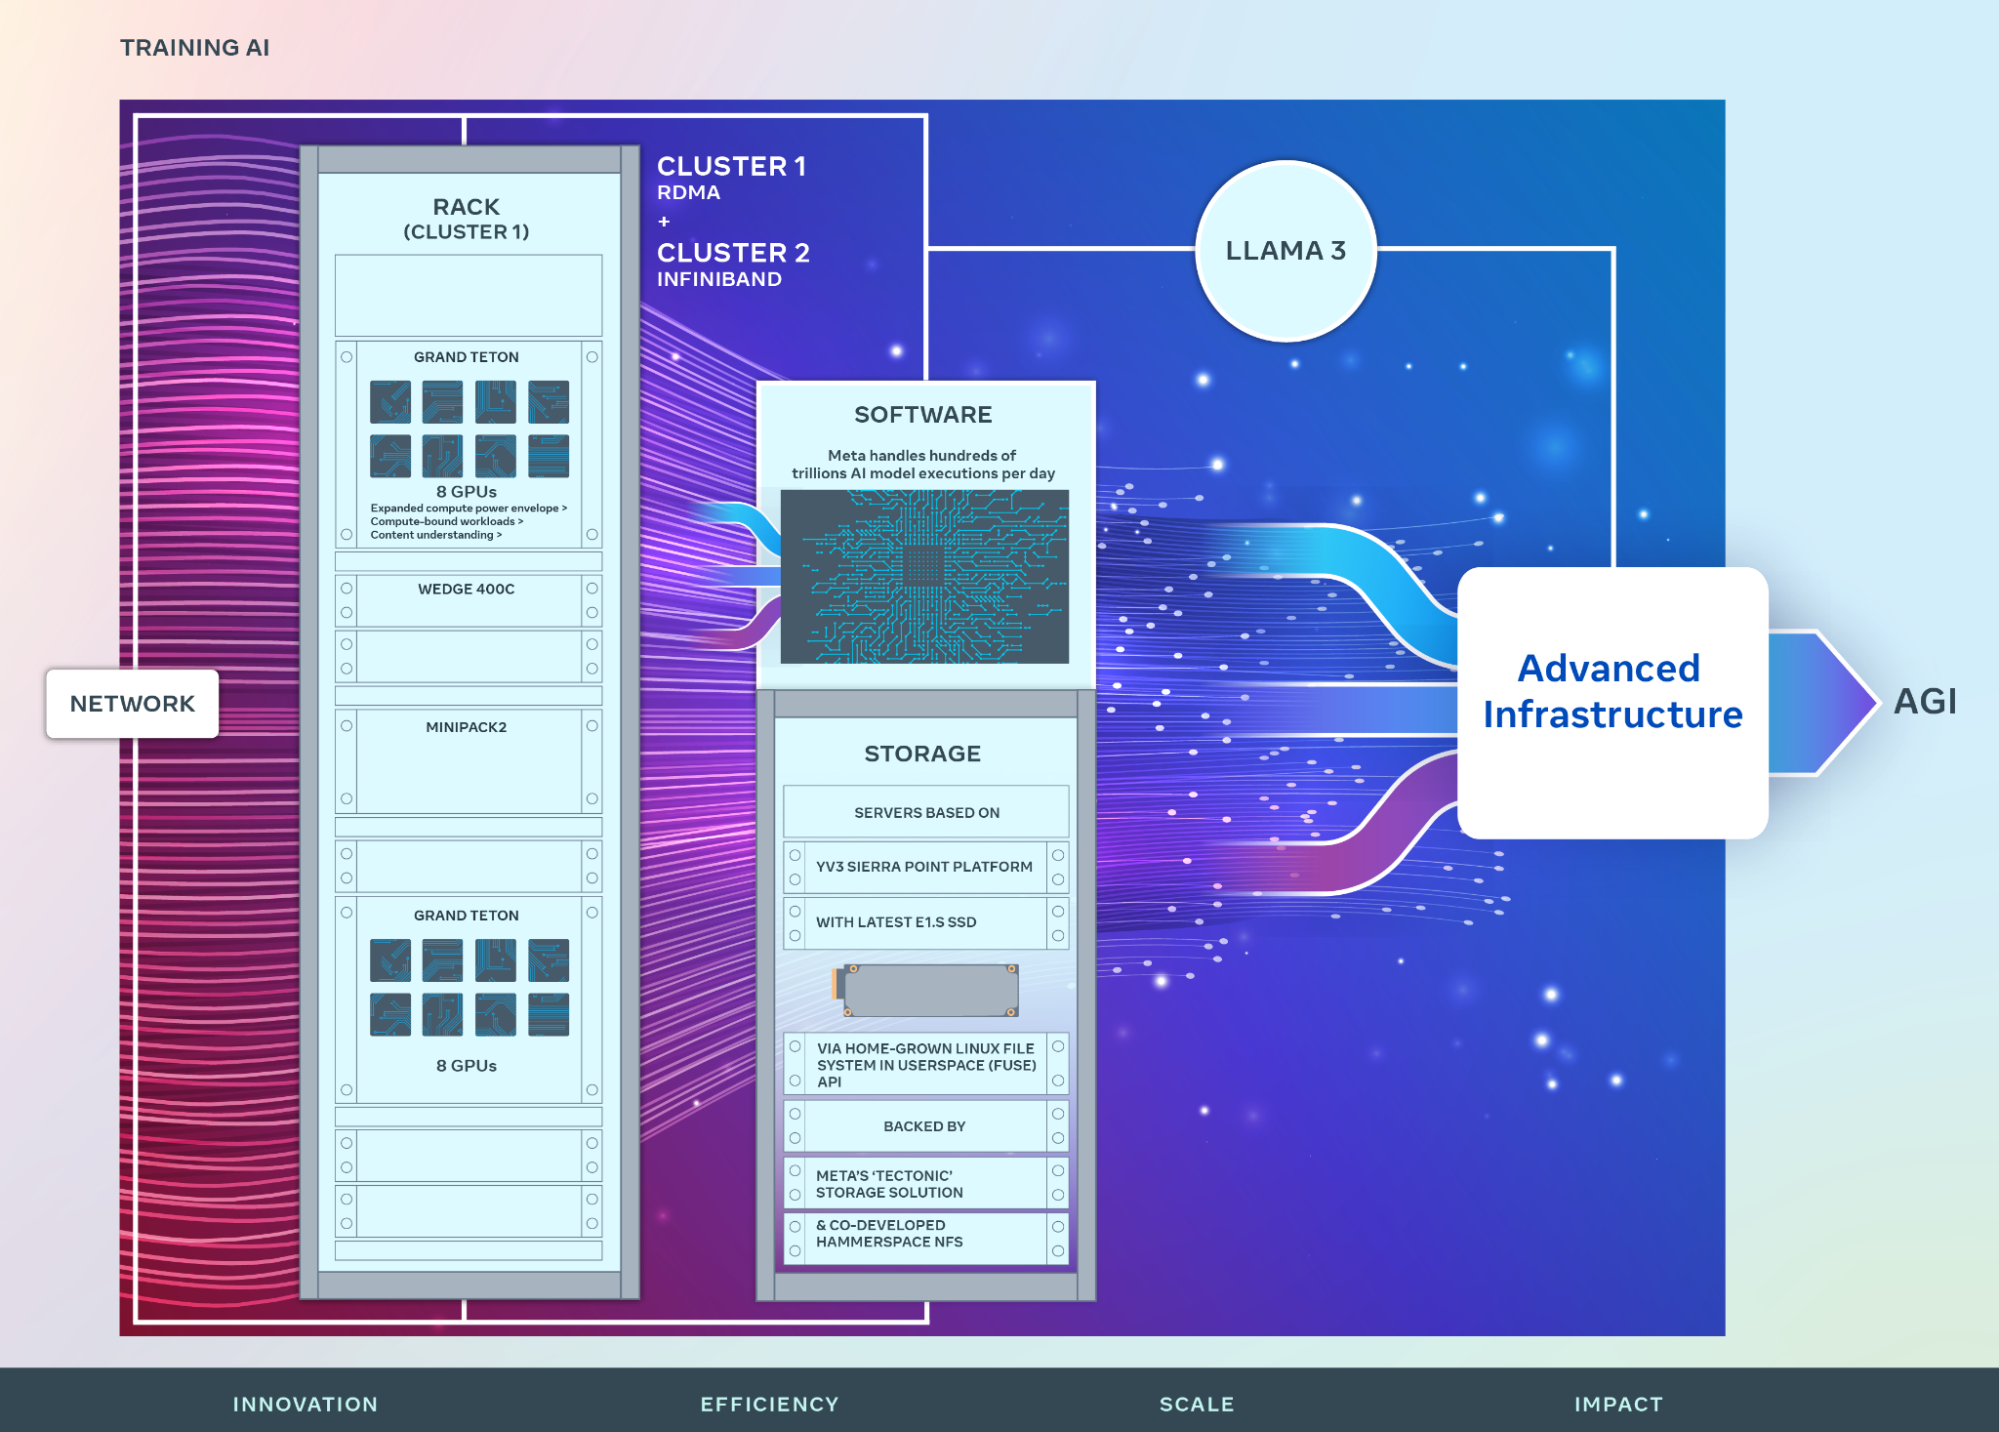
This post details the architecture and implementation of Meta's new 24k GPU AI clusters, designed for GenAI workloads like Llama 3 training. It covers hardware (Grand Teton, OpenRack), networking (RoCE with Arista 7800, InfiniBand with NVIDIA Quantum2), storage (Tectonic FUSE, Hammerspace NFS), and performance optimizations (network topology awareness, NCCL tuning, FP8 support, checkpointing). It also highlights efforts in debuggability (desync debug) and PyTorch evolution for large-scale training.
More from the AI Research and Development trail
- An Organizational Second Brain: Building an AI That Learns From Experts
- From User Sequences to Scaling Laws: A Multi-Stage Architecture for Meta’s Ads Ranking
- GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model
- Exploring Hierarchical Interest Representation For Meta Ads Deep Funnel Optimization
- Meta’s AI Storage Blueprint at Scale