Fully Sharded Data Parallel: faster AI training with fewer GPUs
Jul 15, 2021Myle Ott, Sam Shleifer, Min Xu, Priya Goyal, Quentin Duval, Vittorio Caggiano
Summary
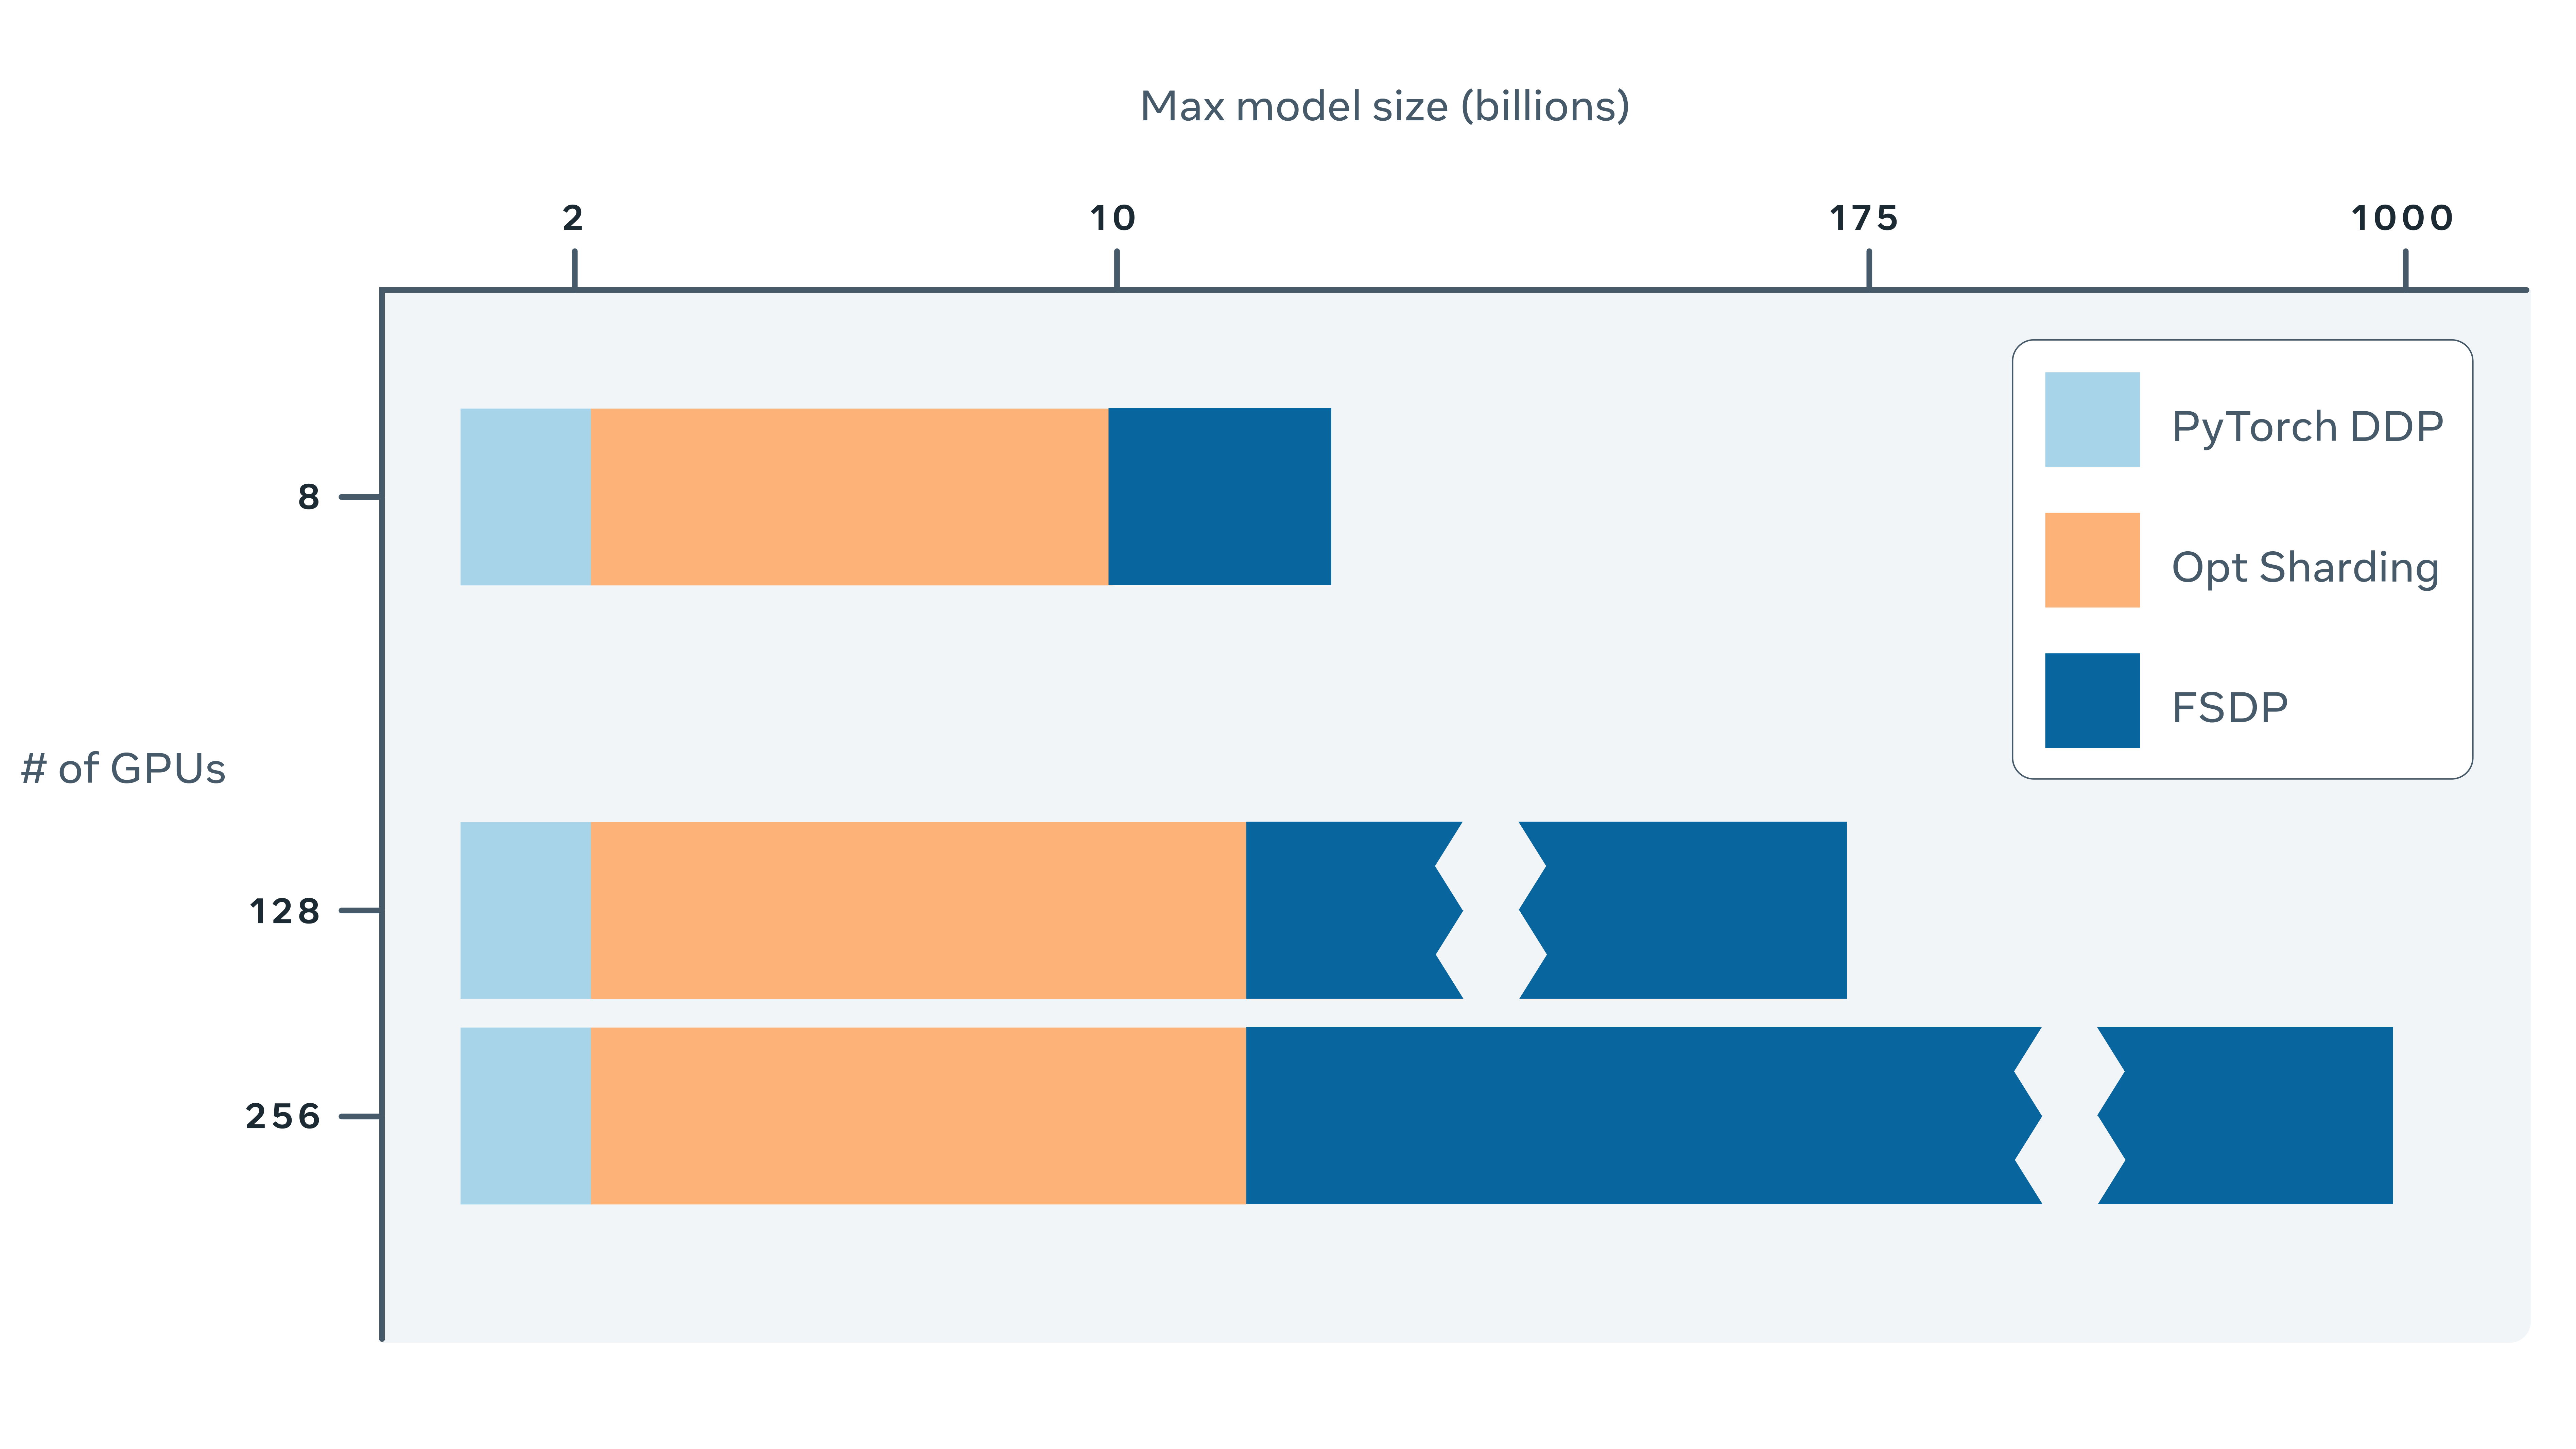
Introduced Fully Sharded Data Parallel (FSDP) as a new tool for more efficient AI model training. FSDP shards model parameters, gradients, and optimizer states across data parallel workers, improving memory efficiency and computational efficiency through communication/computation overlapping. It is implemented in the FairScale library and offers simple APIs as a drop-in replacement for PyTorch's DistributedDataParallel module. The post details the technical mechanism of FSDP, explaining how it decomposes all-reduce operations into reduce-scatter and all-gather, and provides usage examples for language models (fairseq), computer vision models (VISSL), PyTorch Lightning, and direct FairScale integration.
More from the AI Research and Development trail
- An Organizational Second Brain: Building an AI That Learns From Experts
- From User Sequences to Scaling Laws: A Multi-Stage Architecture for Meta’s Ads Ranking
- GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model
- Exploring Hierarchical Interest Representation For Meta Ads Deep Funnel Optimization
- Meta’s AI Storage Blueprint at Scale