Introducing Big Basin: Our next-generation AI hardware
Mar 8, 2017Kevin Lee
Summary
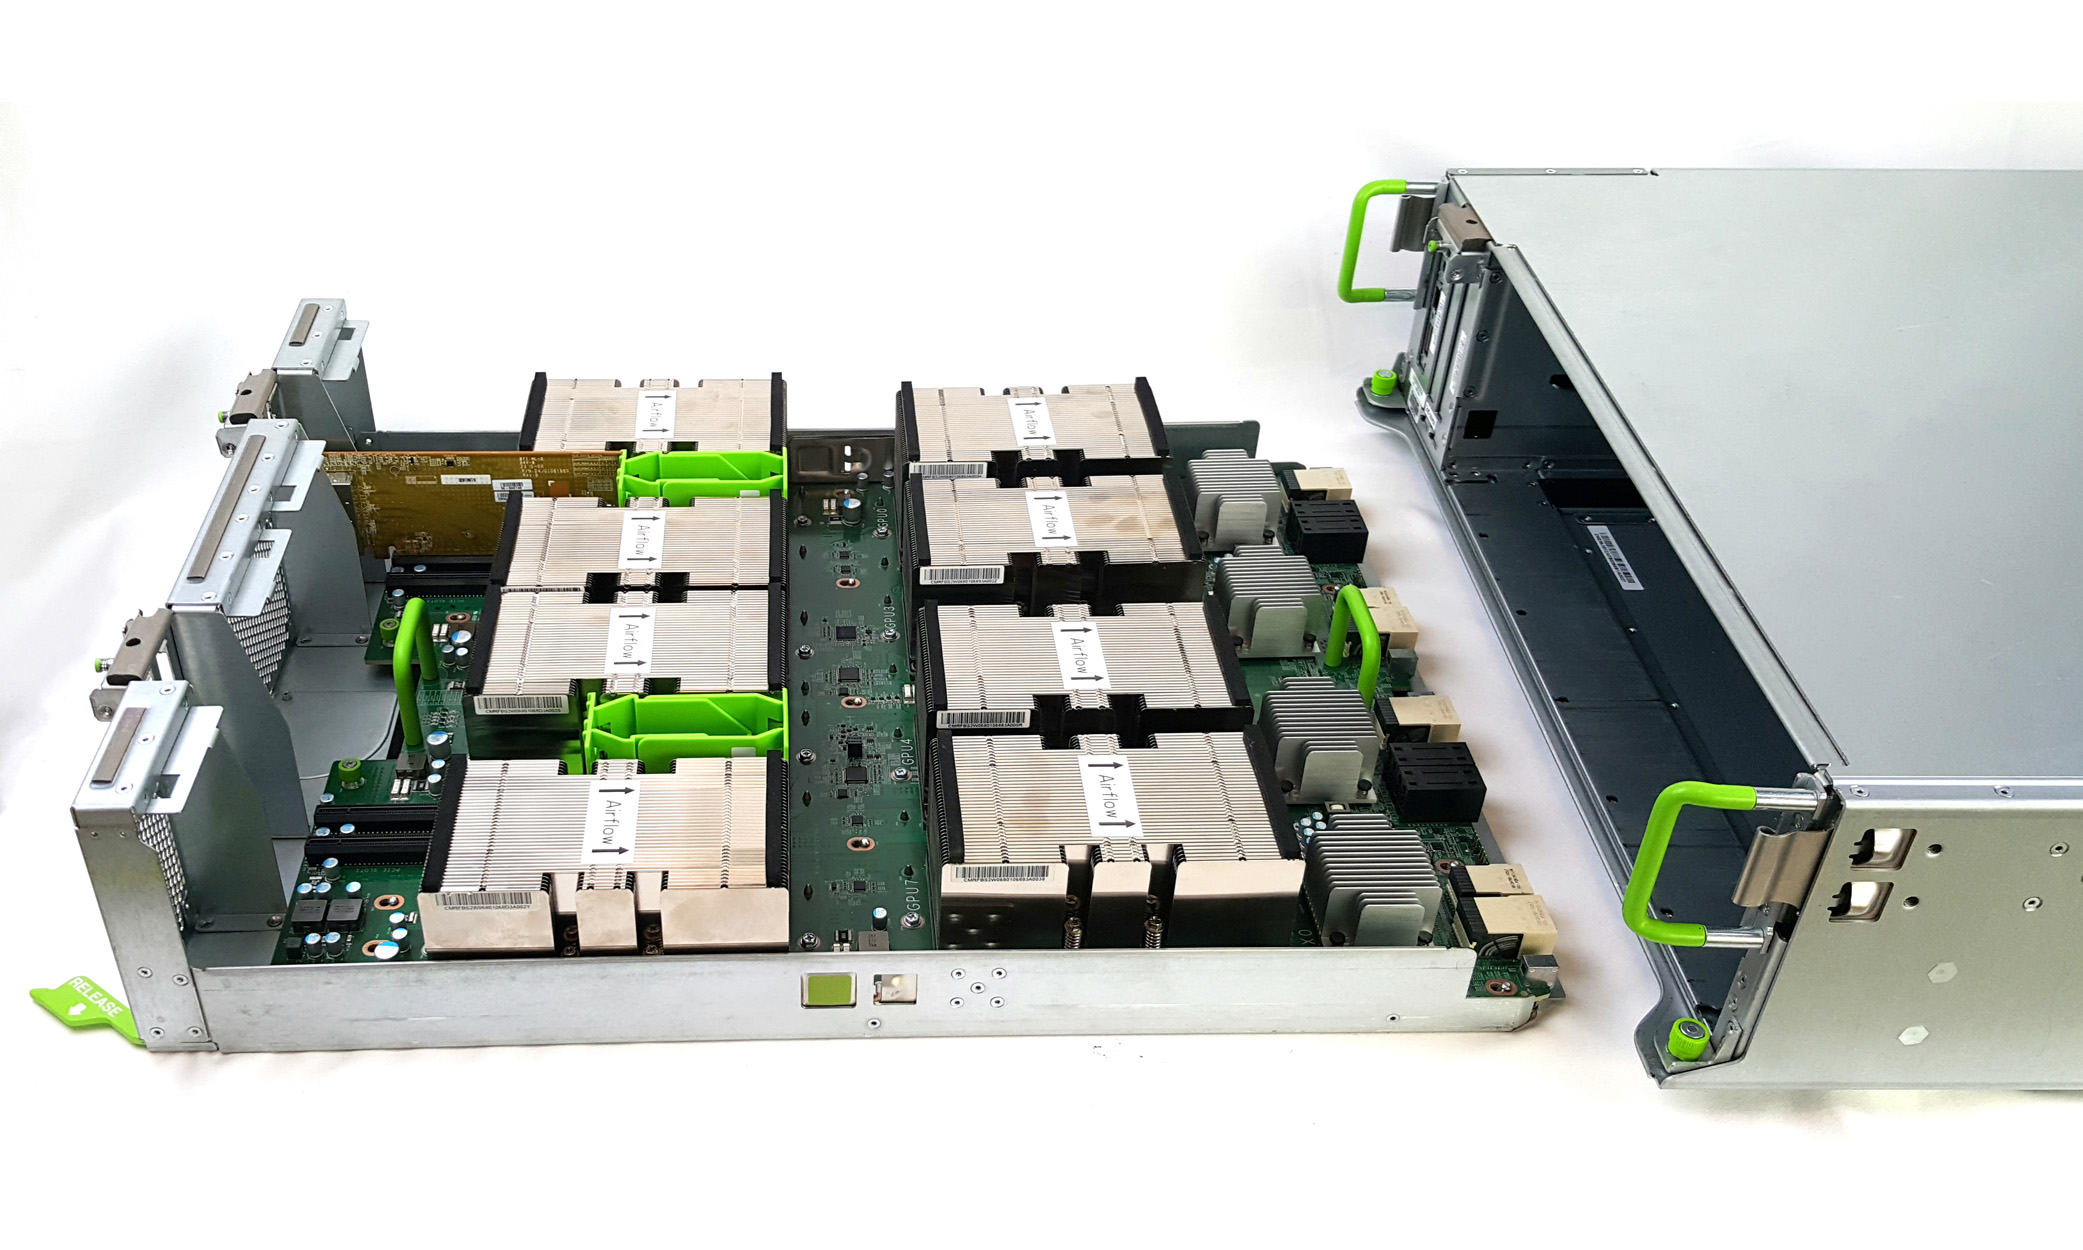
Introduced Big Basin, a next-generation GPU server for AI hardware, as the successor to Big Sur. Big Basin offers a 30% increase in trainable model size due to greater arithmetic throughput and a memory increase from 12 GB to 16 GB. It features a modular, disaggregated design separating CPU compute from GPUs, enabling independent scaling and improved serviceability. The system utilizes NVIDIA Tesla P100 GPU accelerators connected via NVLink in a hybrid cube mesh, offering improved deep learning training performance and higher single-precision (10.6 teraflops) and half-precision floating-point arithmetic. Open-sourced the design through the Open Compute Project.
More from the AI Research and Development trail
- An Organizational Second Brain: Building an AI That Learns From Experts
- From User Sequences to Scaling Laws: A Multi-Stage Architecture for Meta’s Ads Ranking
- GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model
- Exploring Hierarchical Interest Representation For Meta Ads Deep Funnel Optimization
- Meta’s AI Storage Blueprint at Scale