Large-scale graph partitioning with Apache Giraph
Apr 9, 2014Alessandro Presta
Summary
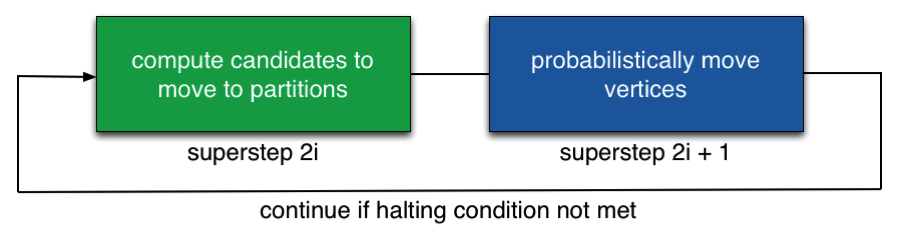
This post introduces a novel approach to large-scale graph partitioning using Apache Giraph to optimize data distribution in sharded systems. It addresses the challenge of high latency in queries that require fetching data across multiple machines by co-locating related data (e.g., friends of a person) within the same partition. The post details a heuristic algorithm inspired by balanced label propagation, adapted for Giraph's distributed model, which iteratively swaps vertices to maximize local edges while maintaining partition balance. It demonstrates significant improvements in iteration time for graph processing algorithms like PageRank and a 2x improvement in bandwidth utilization for a specific service by improving data locality.
More from the News Feed and Timeline Evolution trail
- Friend Bubbles: Enhancing Social Discovery on Facebook Reels
- A New Ranking Framework for Better Notification Quality on Instagram
- Inside Facebook’s video delivery system
- Improving Instagram notification management with machine learning and causal inference
- A linear programming approach for optimizing features in ML models