Open-sourcing FBGEMM for state-of-the-art server-side inference
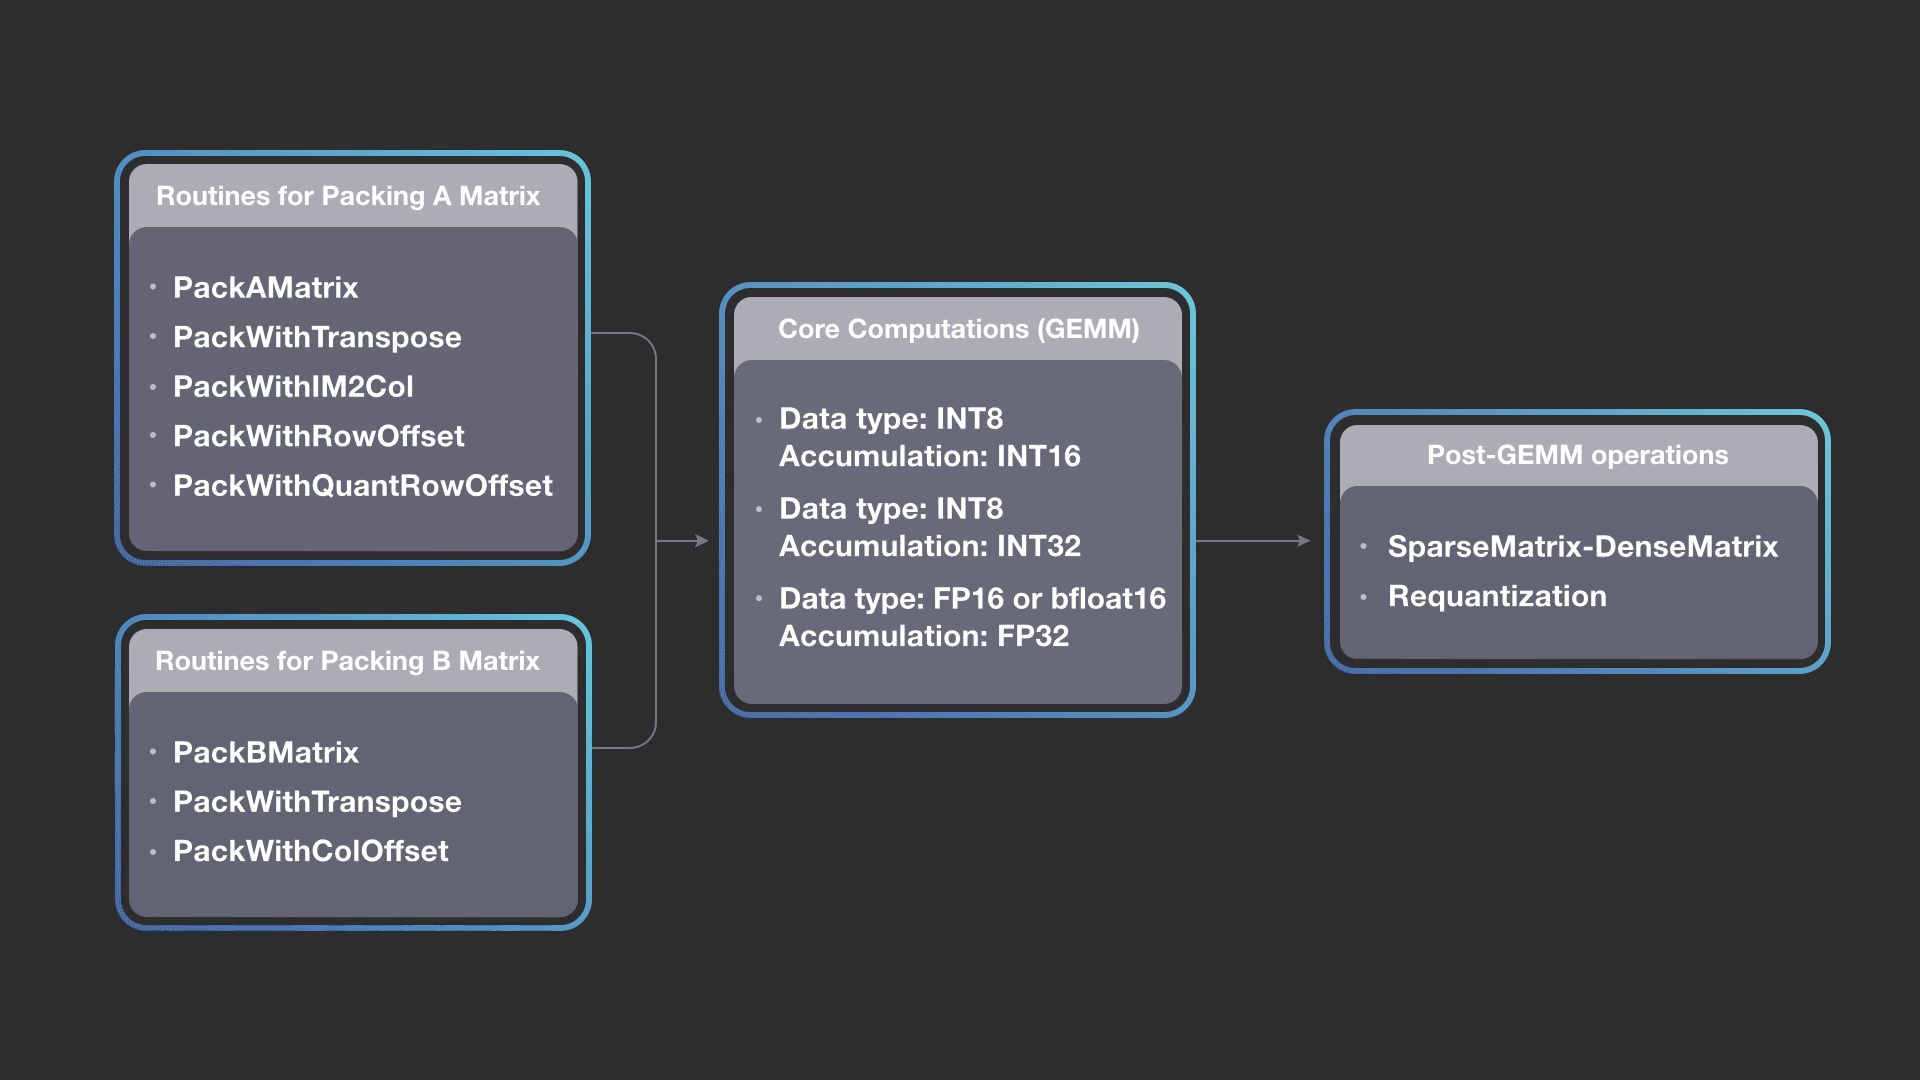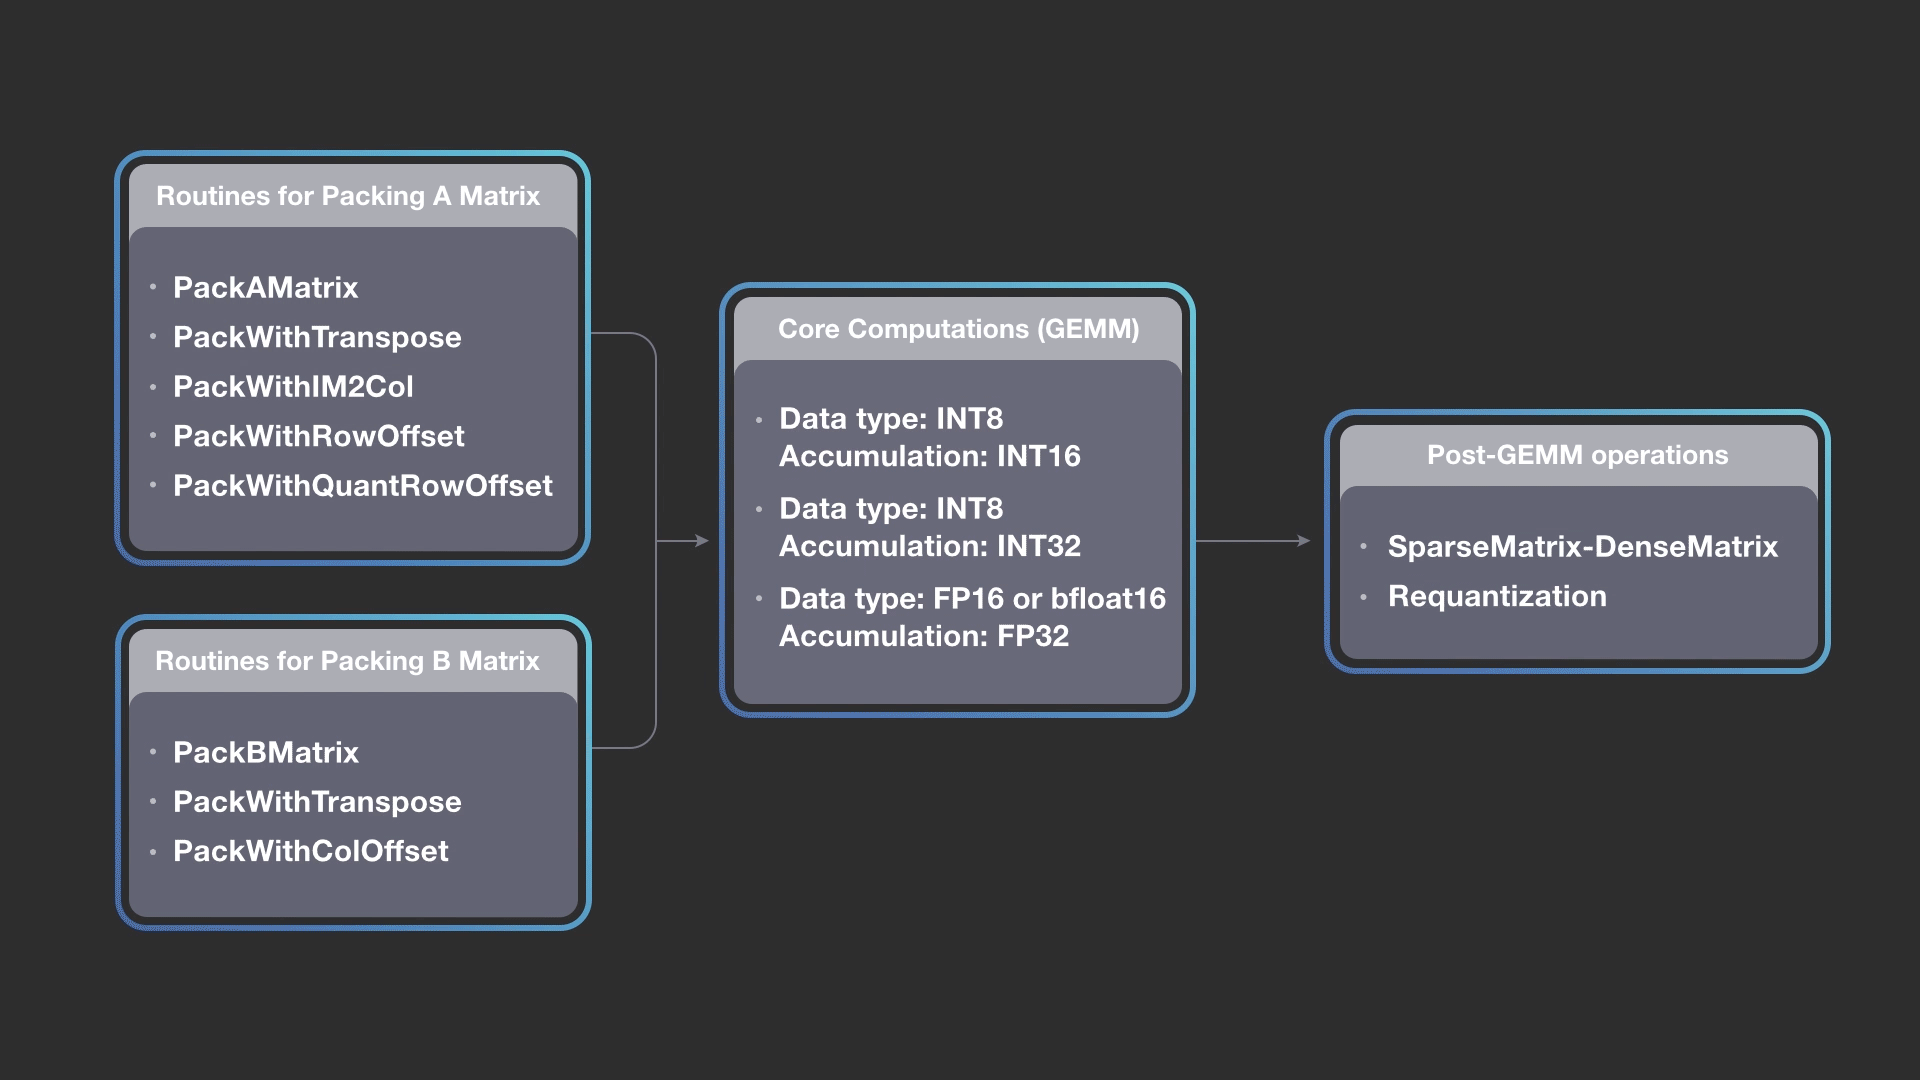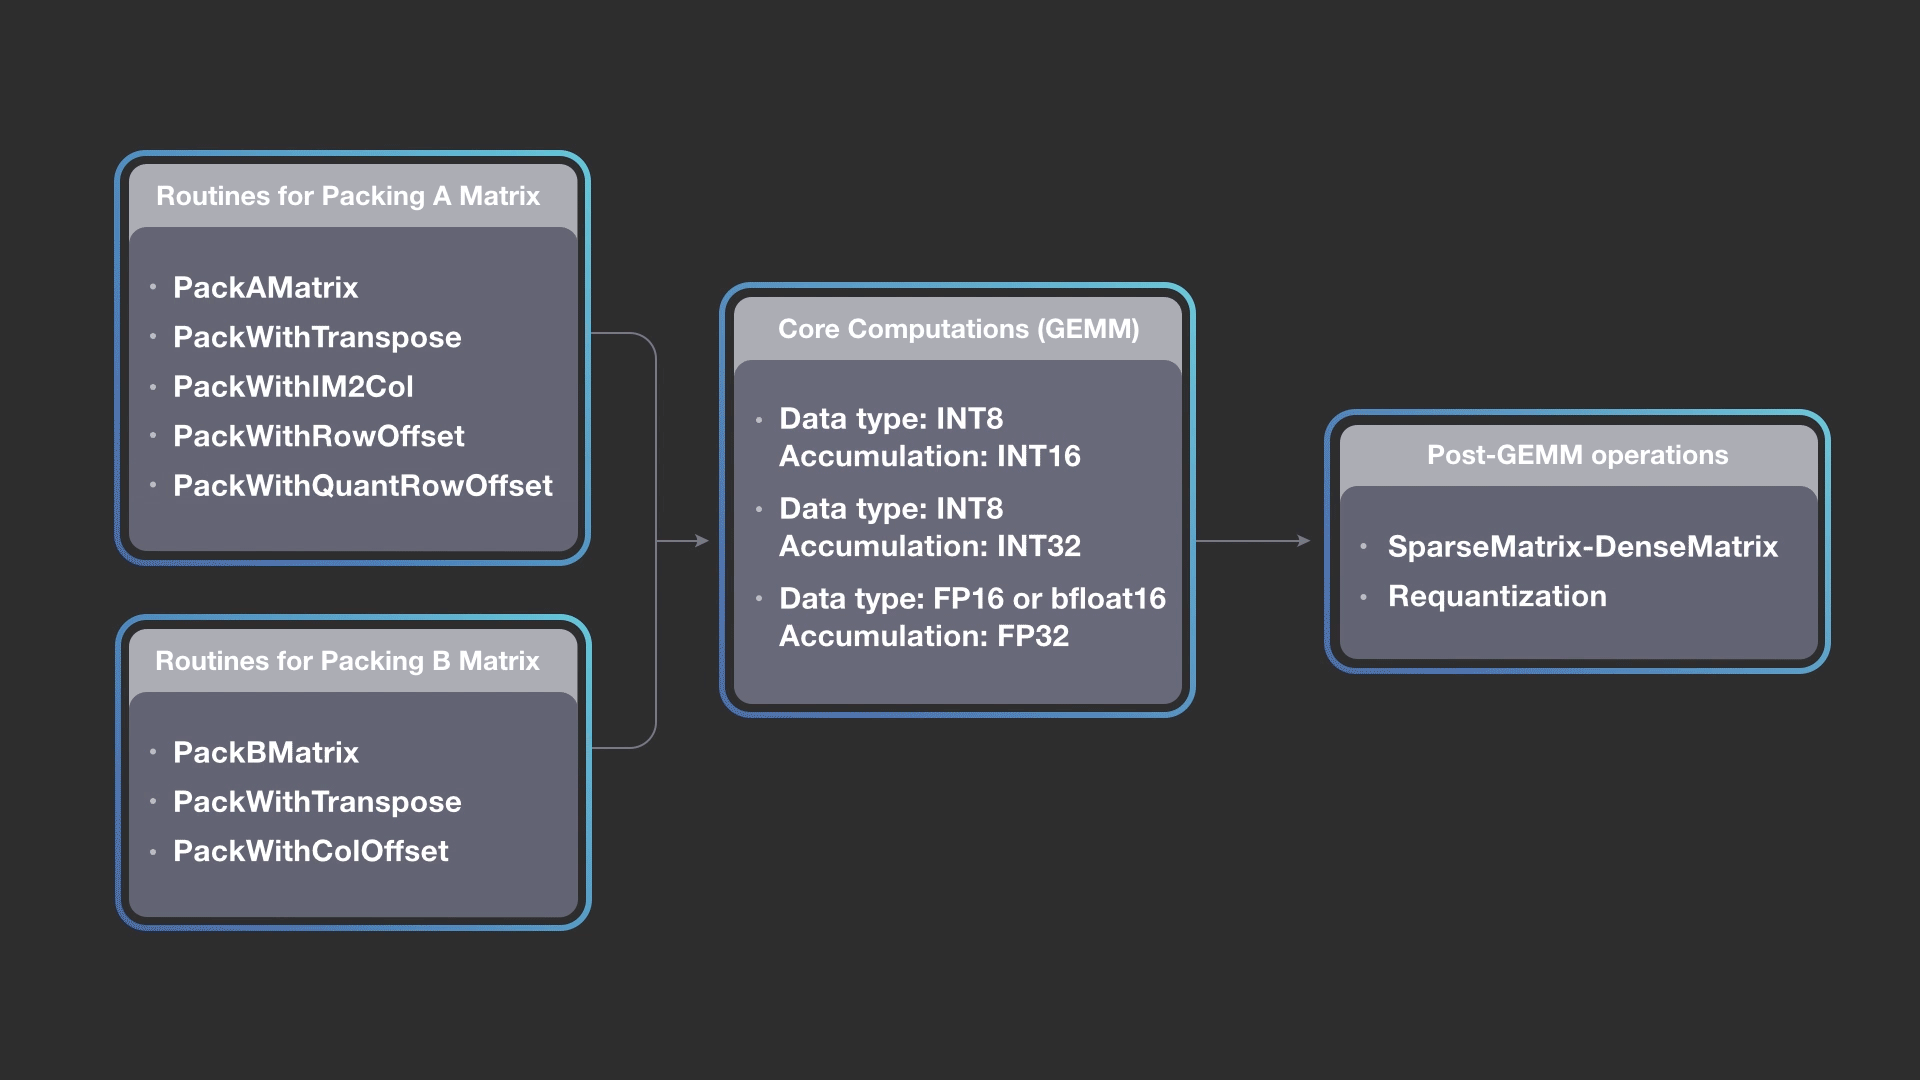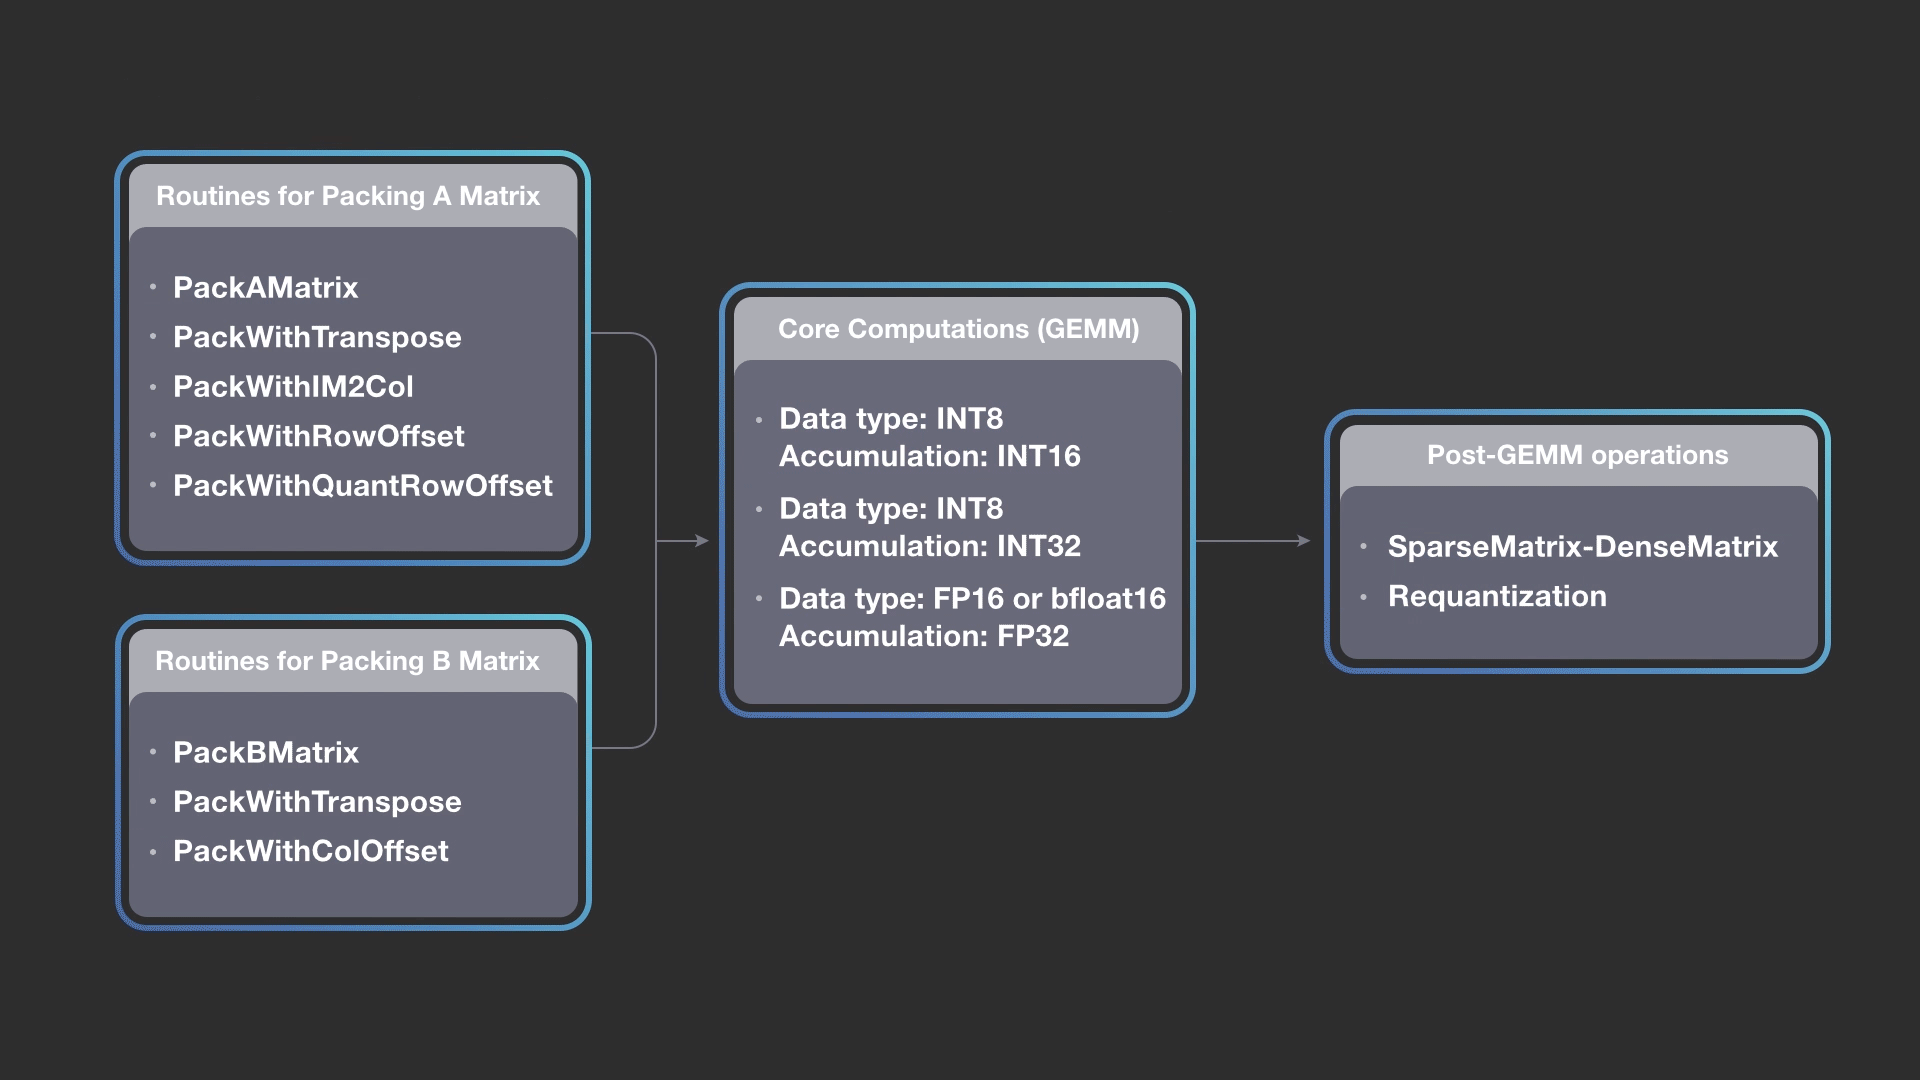
This post introduces and open-sources FBGEMM, a high-performance kernel library specifically optimized for server-side inference of deep learning models. It focuses on efficient low-precision calculations (e.g., INT8, FP16) and matrix-matrix multiplications (GEMM), which are critical for fully connected operators in deep learning models. FBGEMM achieves over 2x performance gains compared to the existing production baseline by optimizing for contemporary CPU architectures, exploiting cache locality, and fusing compute with bandwidth-bound operations like packing. It also supports accuracy-loss-minimizing techniques like row-wise quantization and outlier-aware quantization. The library is deployable with Caffe2 and will soon be callable by PyTorch 1.0.
More from the AI Research and Development trail
- An Organizational Second Brain: Building an AI That Learns From Experts
- From User Sequences to Scaling Laws: A Multi-Stage Architecture for Meta’s Ads Ranking
- GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model
- Exploring Hierarchical Interest Representation For Meta Ads Deep Funnel Optimization
- Meta’s AI Storage Blueprint at Scale