QNNPACK: Open source library for optimized mobile deep learning
Oct 29, 2018Marat Dukhan, Yiming Wu, Hao Lu
Summary
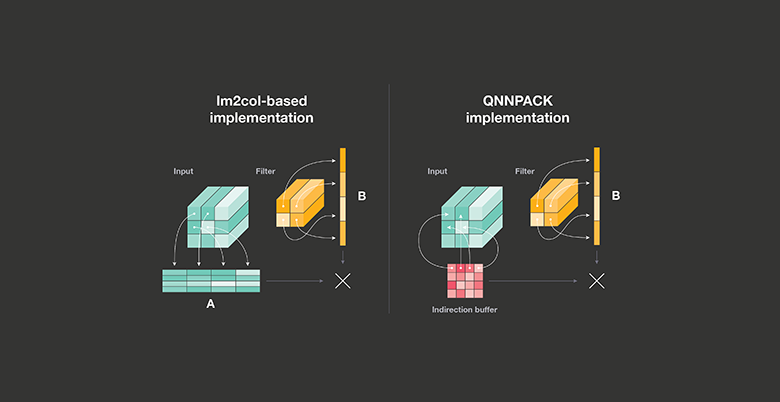
This post introduces QNNPACK, an open-source library of high-performance kernels optimized for mobile deep learning inference. QNNPACK focuses on quantized neural networks, providing efficient implementations of convolutional and fully connected operations on 8-bit integer tensors. It achieves significant performance gains (up to 2x) on mobile devices by optimizing for low-precision computations and leveraging the PDOT microkernel with fused requantization, enabling it to fit entire panels of input matrices into L1 cache and eliminate unnecessary memory transformations. QNNPACK supports common neural network primitives like grouped and depthwise convolutions, which were previously underutilized on mobile due to performance limitations.
More from the AI Research and Development trail
- An Organizational Second Brain: Building an AI That Learns From Experts
- From User Sequences to Scaling Laws: A Multi-Stage Architecture for Meta’s Ads Ranking
- GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model
- Exploring Hierarchical Interest Representation For Meta Ads Deep Funnel Optimization
- Meta’s AI Storage Blueprint at Scale