RoCE networks for distributed AI training at scale
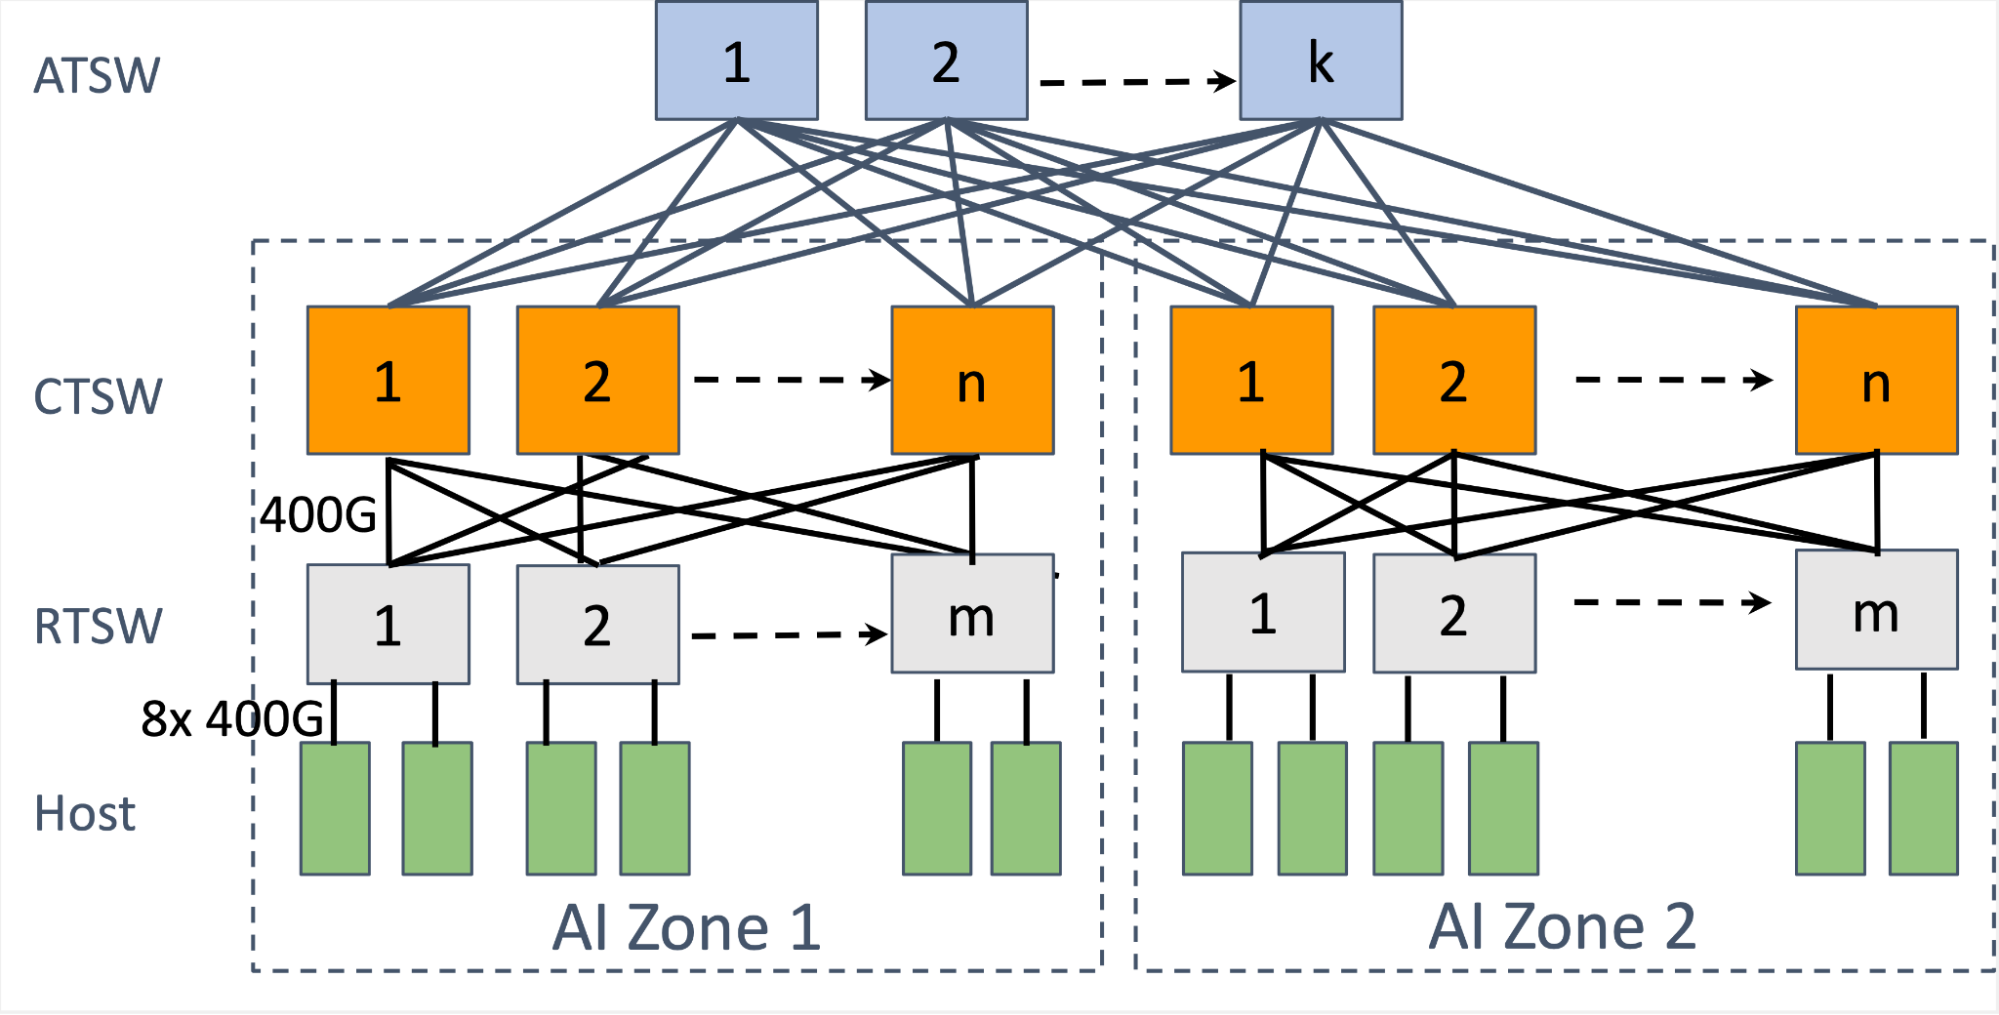
This post details Meta's evolution of RoCE networks for distributed AI training. Key contributions include: 1. **Topology Evolution**: Transition from simple star topologies to two-stage Clos topologies (AI Zones) for scalability, and the introduction of Aggregator Training Switches (ATSW) for DC-scale LLM training. It also discusses the oversubscription strategy and scheduler enhancements for cross-AI Zone traffic. 2. **Routing Evolution**: Moving from ECMP with low entropy issues to path-pinning, and then to Enhanced ECMP (E-ECMP) with Queue Pair (QP) scaling to increase flow entropy and improve performance for collectives like AllReduce. 3. **Congestion Control Shift**: Abandoning DCQCN for 400G deployments due to firmware issues and reduced visibility, and instead relying on PFC for flow control. For 400G+, a co-designed receiver-driven traffic admission mechanism between the collective library and RoCE transport is implemented to limit in-flight traffic and mitigate congestion.