Scaling Apache Giraph to a trillion edges
Aug 14, 2013Avery Ching
Summary
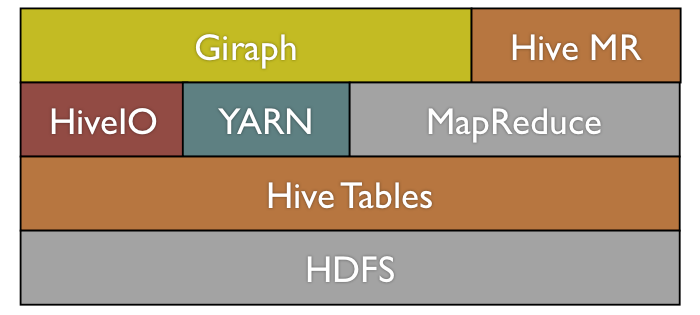
This post details the significant enhancements made to Apache Giraph to scale it to handle trillions of edges. Key contributions include: flexible vertex/edge based input allowing loading from separate sources and multiple Hive tables; HiveIO for up to 4x faster reading/writing to Hive tables; multithreading for graph loading, computation, and result storage; memory optimizations via serialization of vertices/edges into byte arrays and using Java primitives with FastUtil; and sharded aggregators implemented with Netty to bypass Zookeeper limitations and handle large-scale global computations efficiently.