SLICK: Adopting SLOs for improved reliability
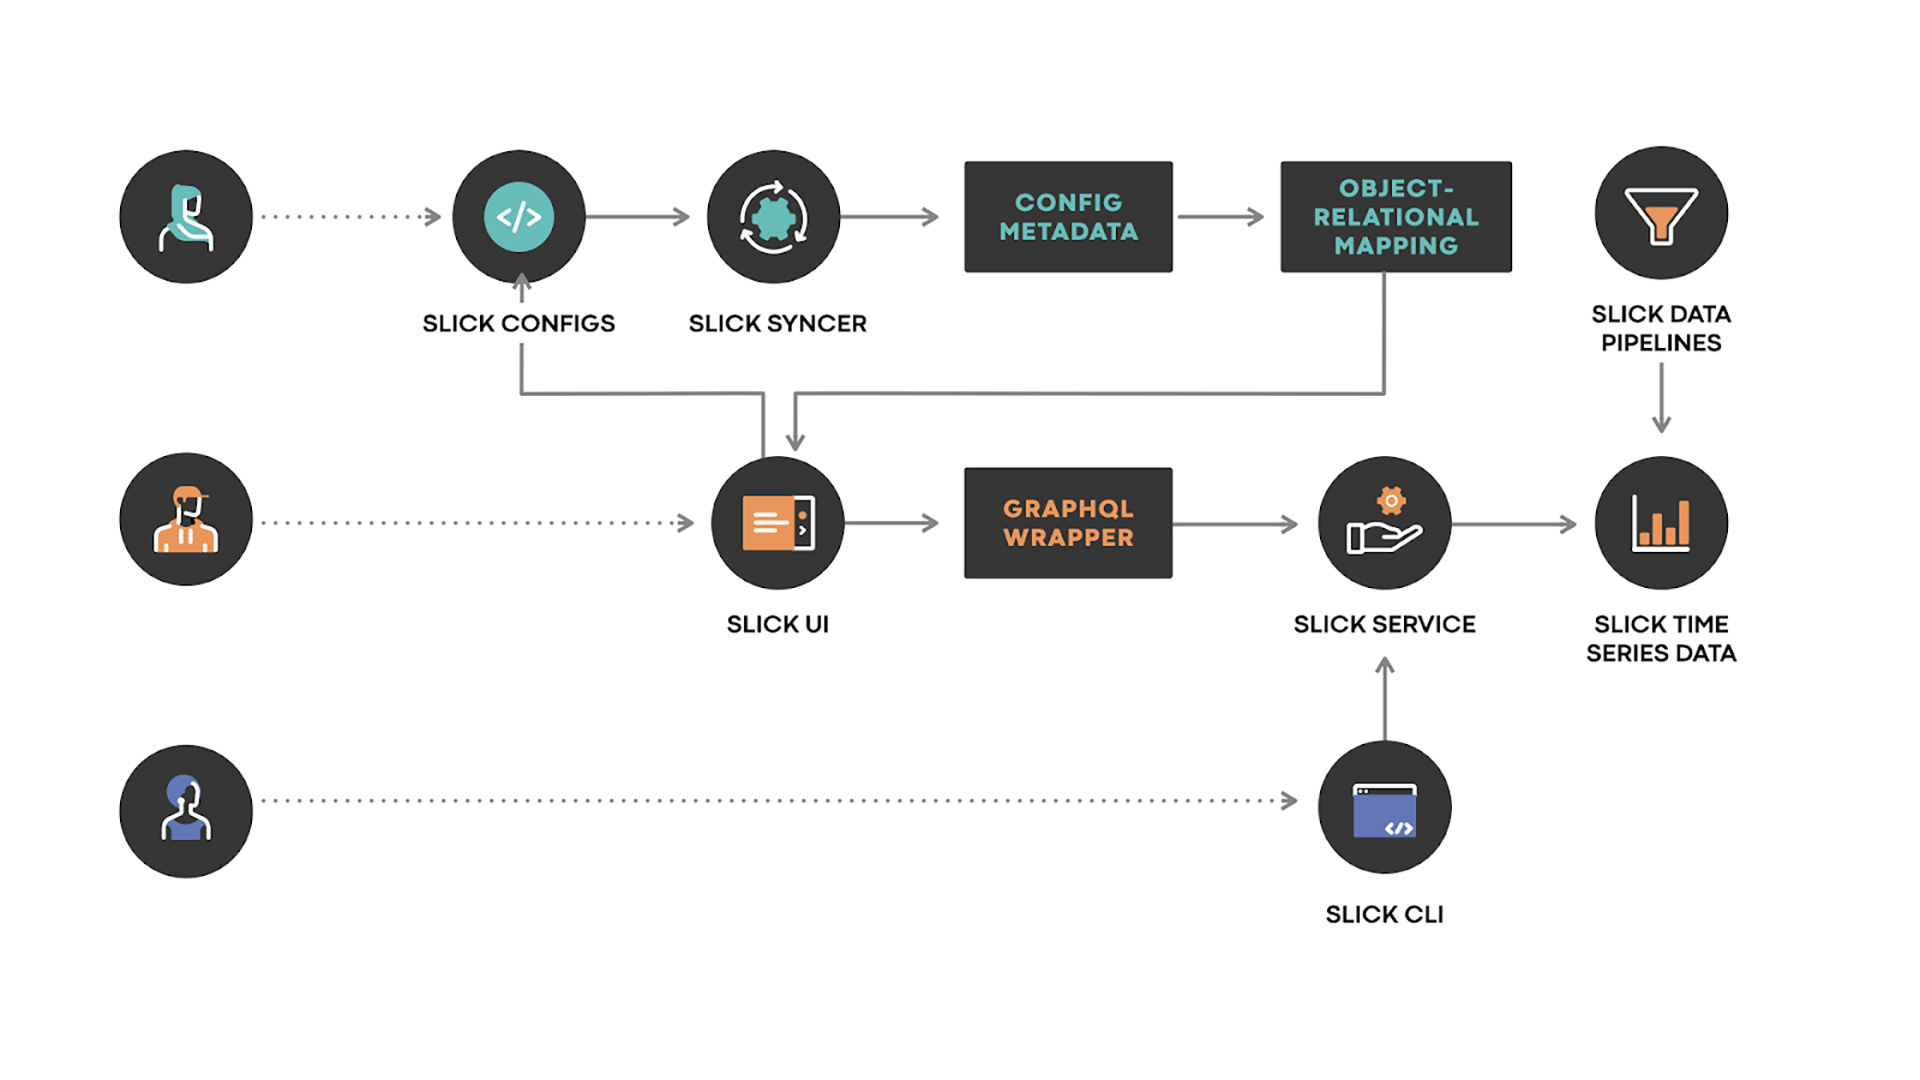
This post introduces SLICK, a dedicated SLO store built to centralize SLI and SLO definitions at Meta. SLICK provides tooling support for defining SLOs, offers high-retention, full-granularity data (per-minute, up to two years) for key service metrics, and integrates SLOs into various workflows (on-call tooling, incident declaration criteria). It aims to improve discoverability of service reliability metrics, enable long-term trend analysis, and standardize reliability expectations across the company. The architecture includes a DSL for defining SLOs, a syncer, UI for dashboards and index, a service for querying SLOs, and data pipelines for ingesting SLI time series data into a sharded MySQL database. Over 1,000 services were onboarded by 2021, with examples of its use in improving LogDevice and a back-end ML service reliability.
More from the Site Reliability and Outage Management trail
- Lights Out, Systems On: Validating Instant Power Loss Readiness
- DrP: Meta’s Root Cause Analysis Platform at Scale
- Zoomer: Powering AI Performance at Meta’s Scale Through Intelligent Debugging and Optimization
- Diff Risk Score: AI-driven risk-aware software development
- How Meta keeps its AI hardware reliable