Under the hood: Multilingual embeddings
Jan 24, 2018Ves Stoyanov
Summary
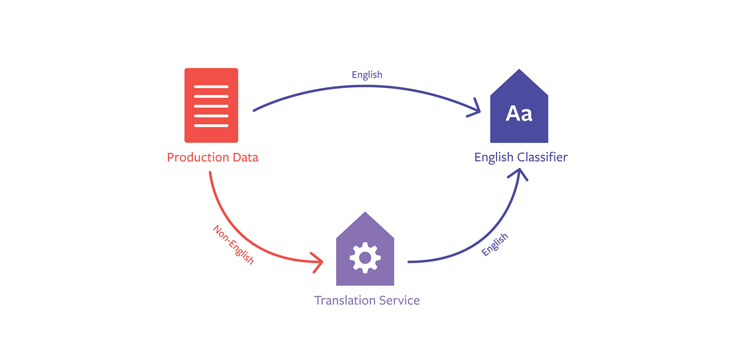
Introduced multilingual embeddings for NLP tasks, enabling text classification across languages without explicit translation. This involves training language-specific embeddings using fastText, projecting them into a common space using an orthogonal matrix derived from parallel data, and integrating them into the DeepText framework. This approach significantly improves cross-lingual accuracy and reduces latency compared to translation-based methods.
More from the Internationalization and Language Modeling trail
- Language packs: Meta’s mobile localization solution
- Integrating autoconversion: Facebook’s path from Zawgyi to Unicode
- Expanding automatic machine translation to more languages
- Scaling neural machine translation to bigger data sets with faster training and inference
- Transitioning entirely to neural machine translation