Introducing Qdrant Cloud Inference - Qdrant
Jul 15, 2025Daniel Azoulai
Summary
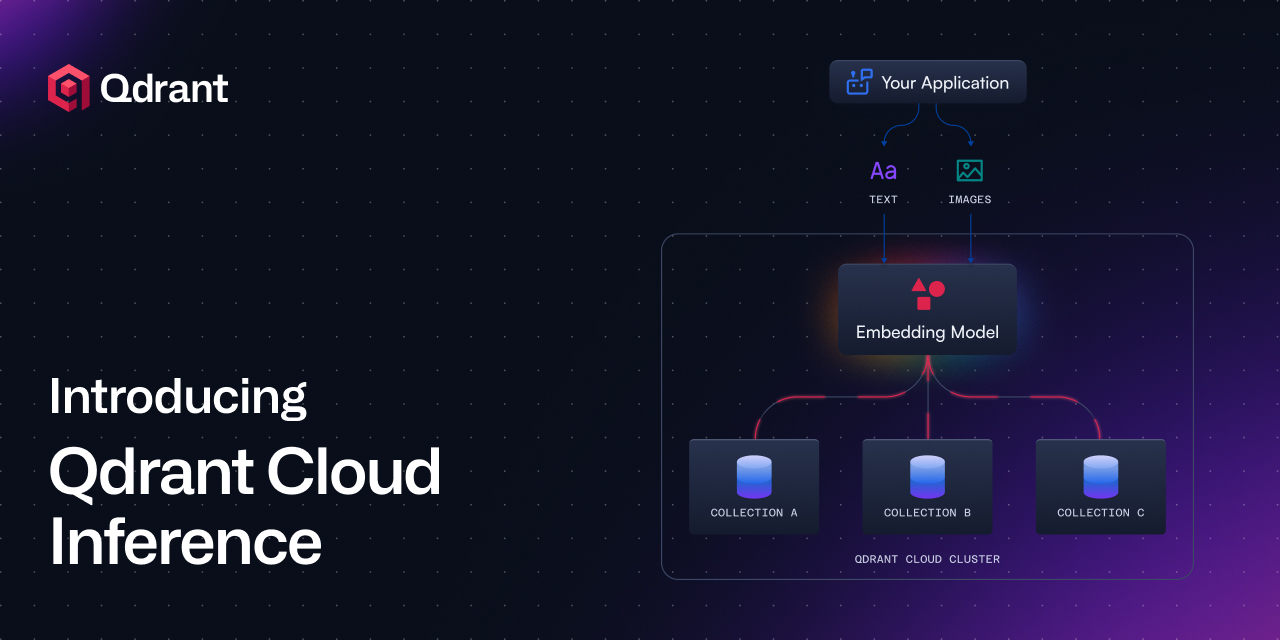
This post announces the launch of Qdrant Cloud Inference, a new capability that unifies embedding generation and vector storage within a single API call. It eliminates the need for separate inference infrastructure, reducing complexity, latency, and network costs. The feature supports six curated models at launch, including dense, sparse (BM25), and multimodal (CLIP-style) options. It offers free token allowances for onboarding and is automatically enabled for paid accounts. The post also highlights how this simplifies building RAG, multimodal, and hybrid search applications.