Together AI delivers fastest inference for the top open-source models
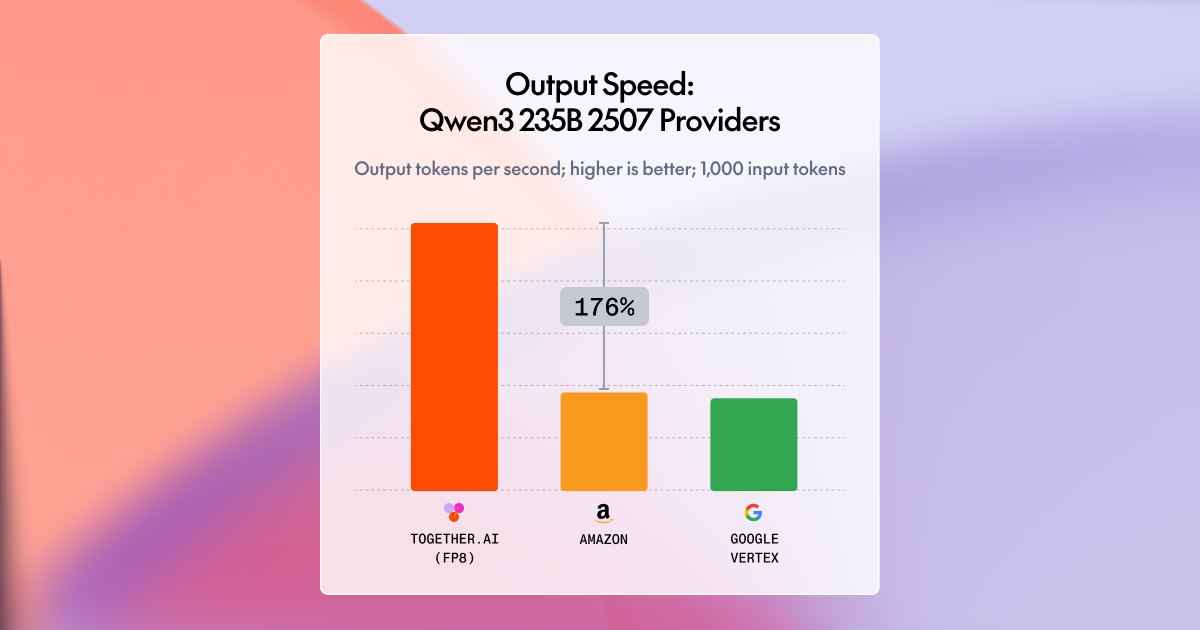
This post details the engineering behind Together AI's achievement of up to 2x faster serverless inference for open-source LLMs, ranking #1 in output speed benchmarks. Key technical contributions include: 1. Next-gen GPU hardware optimization for NVIDIA Blackwell architecture (GB200 NVL72), including optimized paths for low-precision compute (FP8, FP4) and high-bandwidth data movement. 2. Development of 'Together Kernels' for NVIDIA Blackwell, including optimized FlashAttention-4 and fused MoE kernels. 3. A Turbo Optimization Suite featuring near-lossless quantization (FP8, FP4, hybrid precision) with architecture-aware calibration and fused FP4/FP8 kernels. 4. Production-grade speculative decoding algorithms with training-efficient methods, high-accuracy draft models, adaptive acceptance strategies, and fail-safe fallback mechanisms. 5. A scalable draft-model training pipeline supporting models up to 1T+ parameters, utilizing curriculum-based training, post-training recipes, data-mixing, and an alignment evaluation framework.