What’s Cooking
Running open-Jev in SQL on Databricks
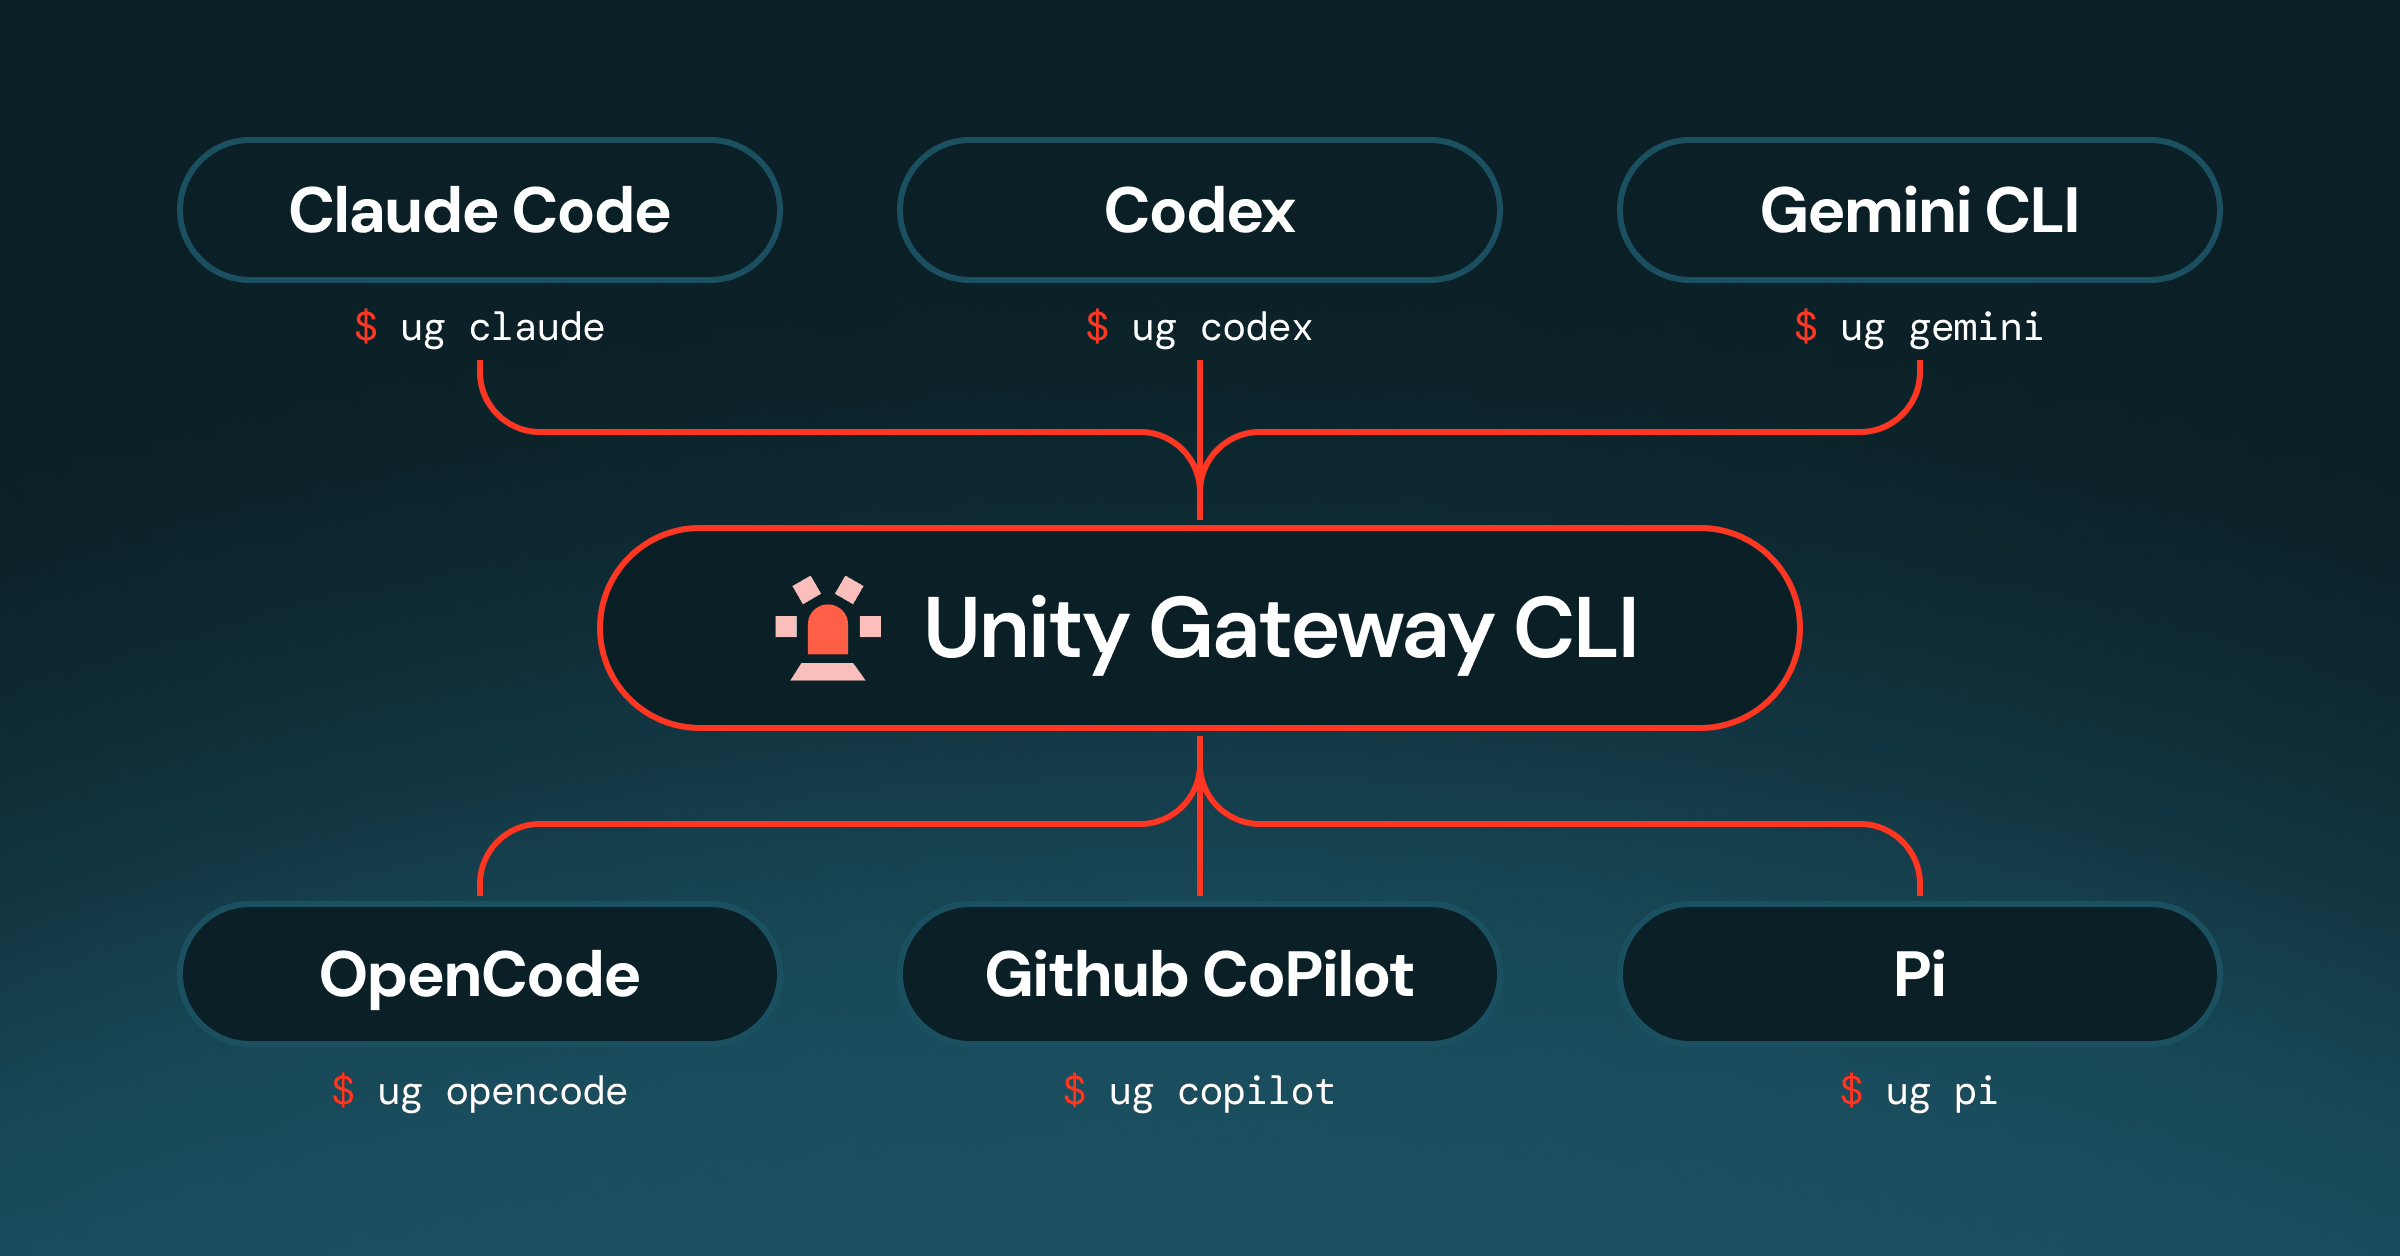
Deploy and manage coding agents at scale with the Unity Gateway CLI
Introducing Cloud Sandboxes: Start on Your Laptop, Finish in the Cloud
Docker Brings Sandbox Kit Spec to the CNCF
Docker Sandbox Kit Spec: Authority as Code
Introducing Gemini 3.8 Live with Live Avatar
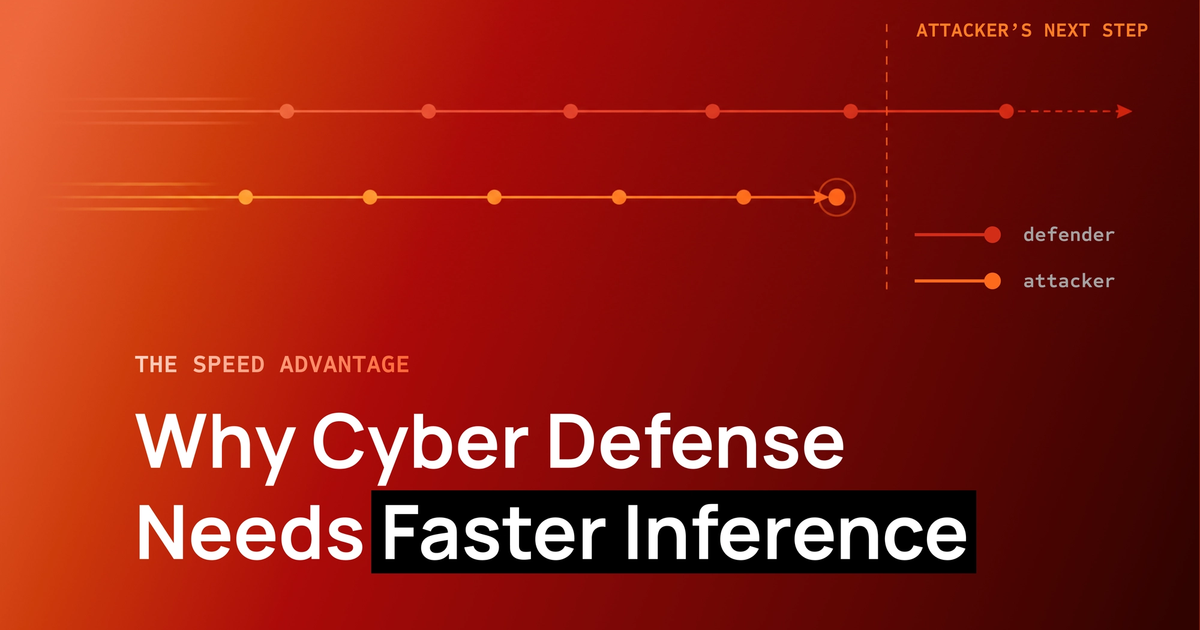
Why Cyber Defense Needs Faster Inference
How Cloudflare addressed a cross-tenant data exposure vulnerability in Containers

Efficient MoE Training for Biological Foundation Models

A New Tempo for Defense Software
Why AI Clouds Need a Tiered Storage Architecture
Accelerating vision-language models with LFM2.5-VL-DSpark

Hitting a billion tokens per minute on one GPU by combining a query planner and an inference engine
Turn your REST APIs into MCP tools with Google Cloud API Gateway- Google Developers Blog

Reproducing OLMo 3 7B Pre-training in MaxText: case study of large scale training on TPUs- Google Developers Blog

Building multimodal models for spatial reasoning
 VercelBlog