What’s Cooking
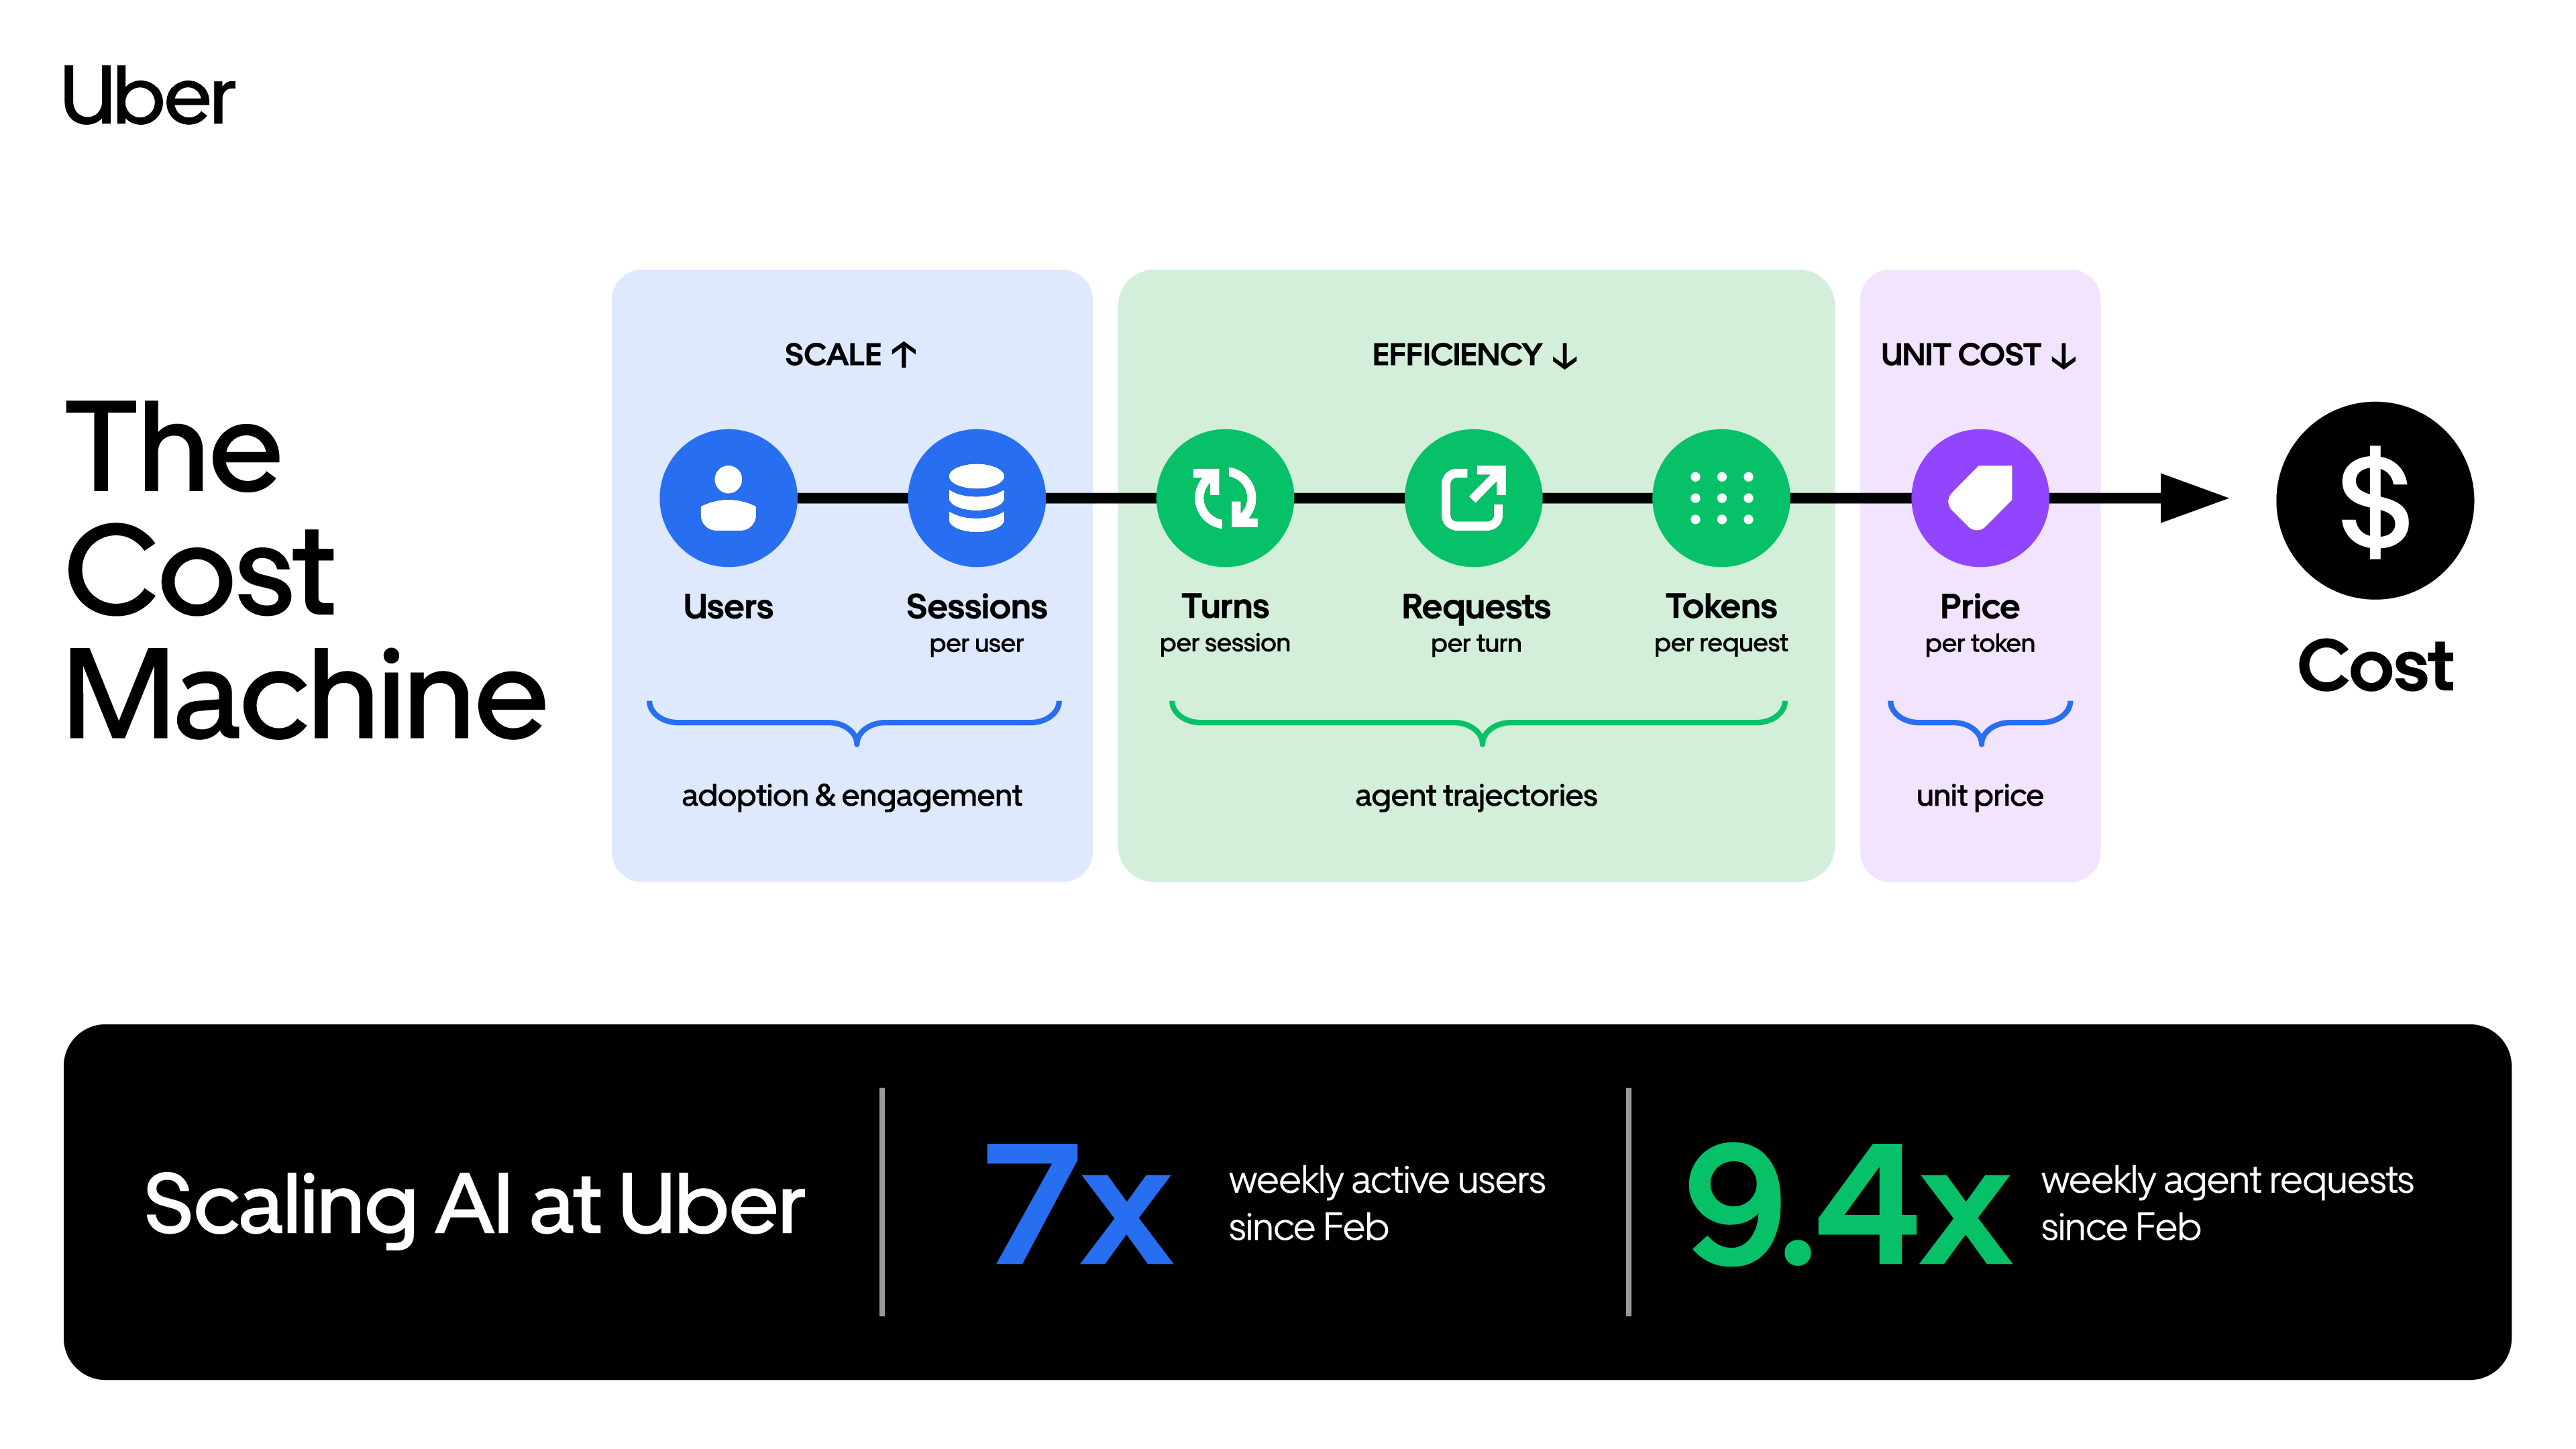
Running a Software Factory Efficiently at Uber Scale
Deploy Kimi K3 Dedicated Inference on CoreWeave
Intelligent transcription with Gemini 3.5 Transcribe

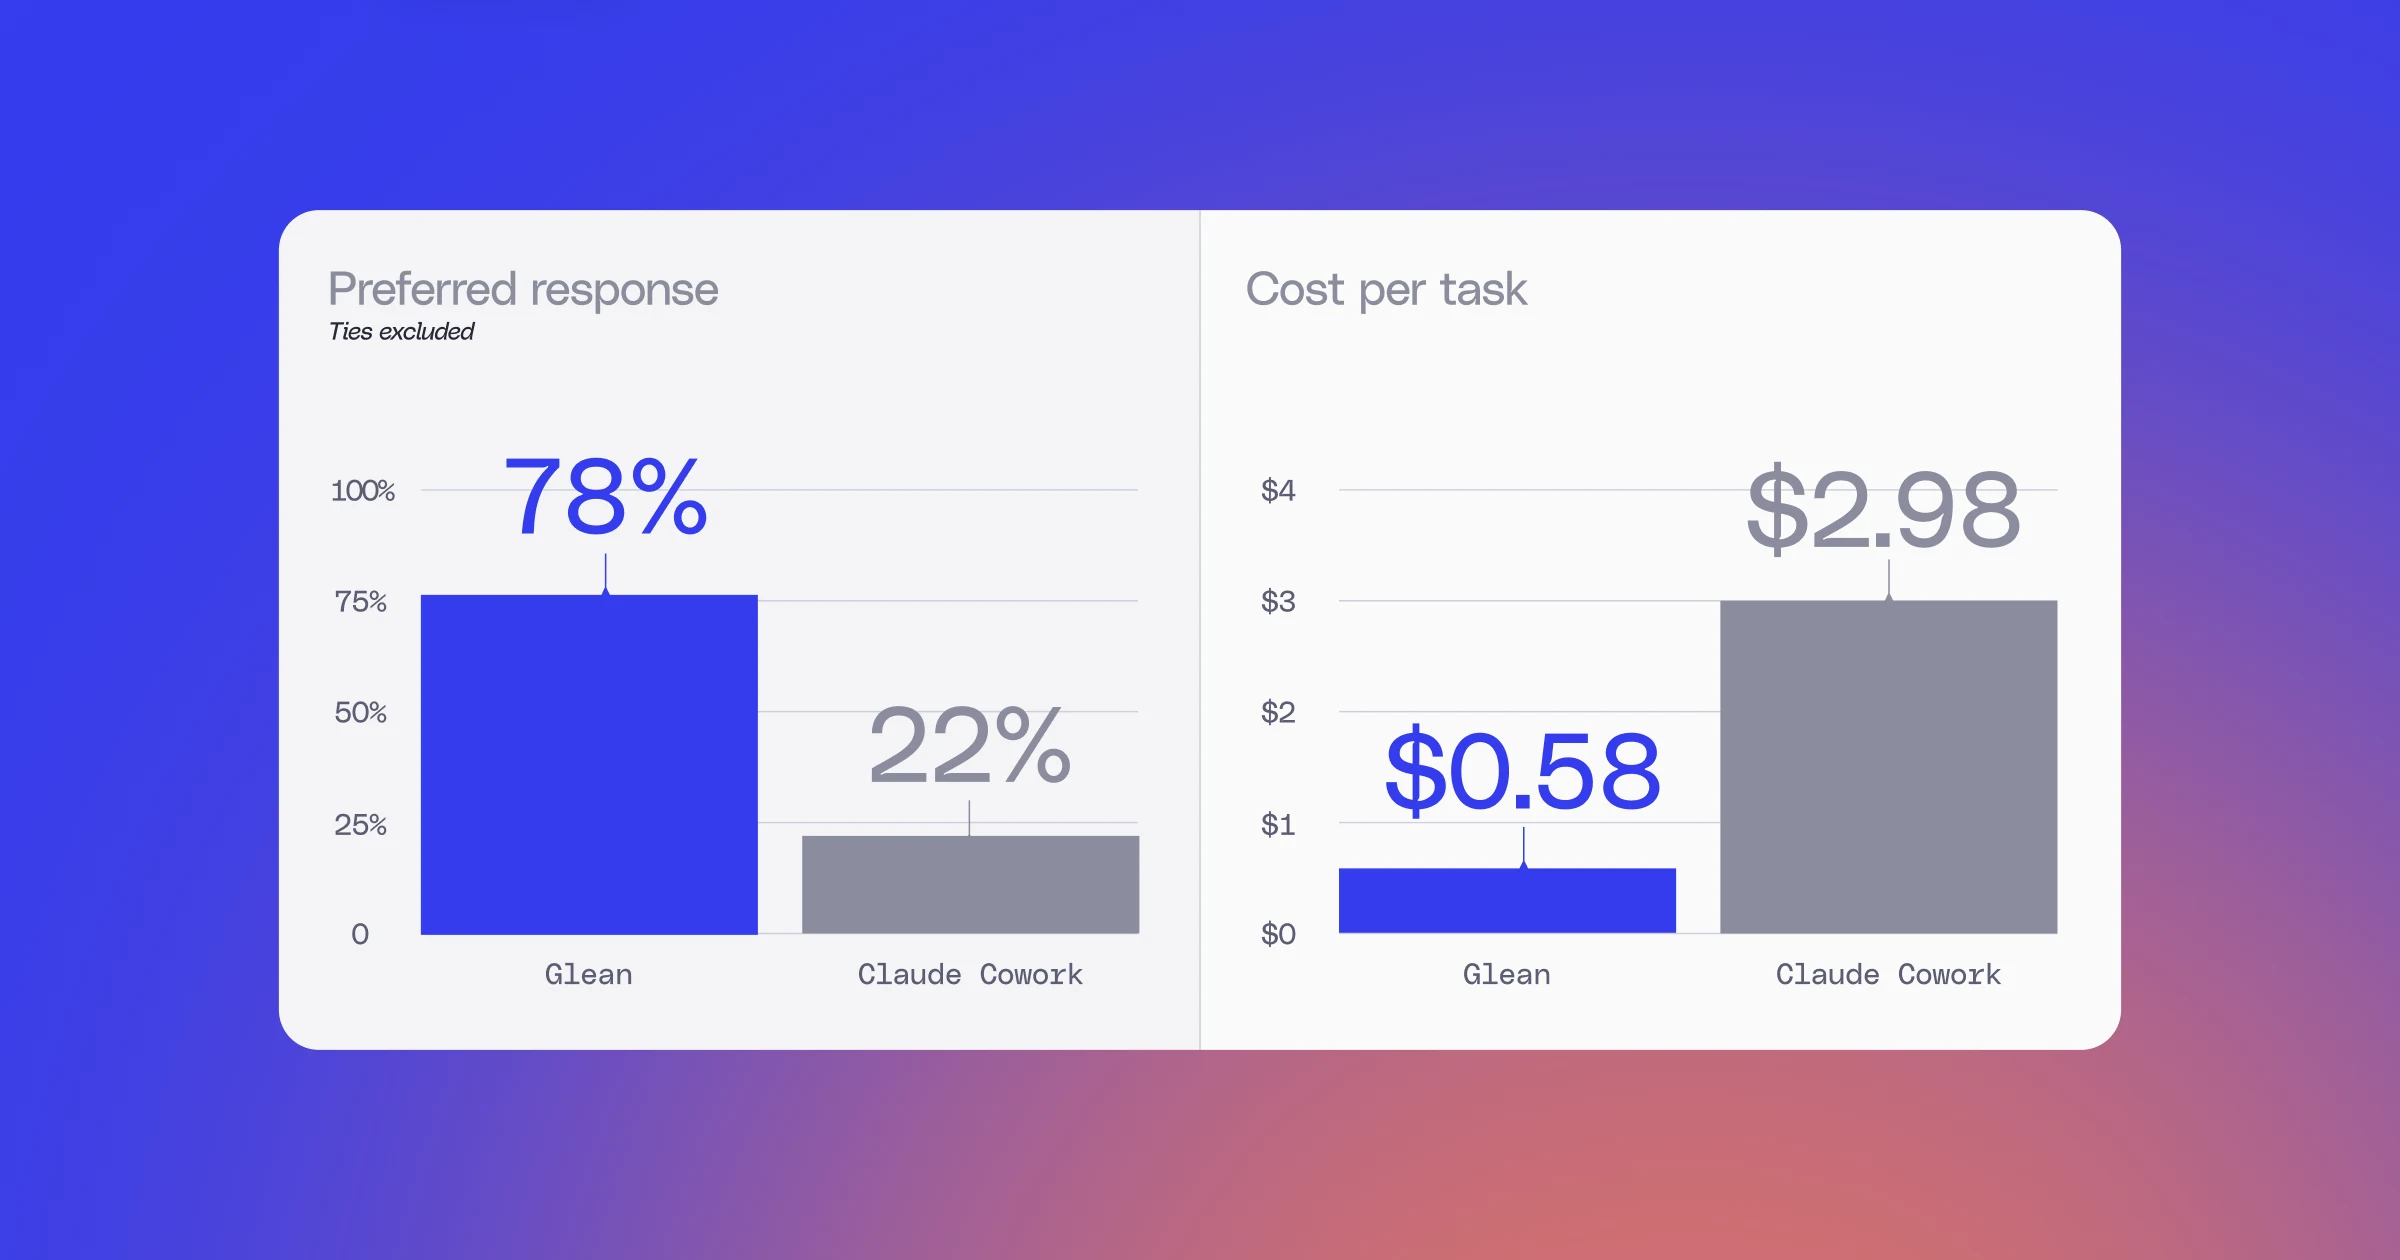
Right-sizing intelligence: Glean saves 81% on token costs and is preferred 78% of the time versus Claude Cowork
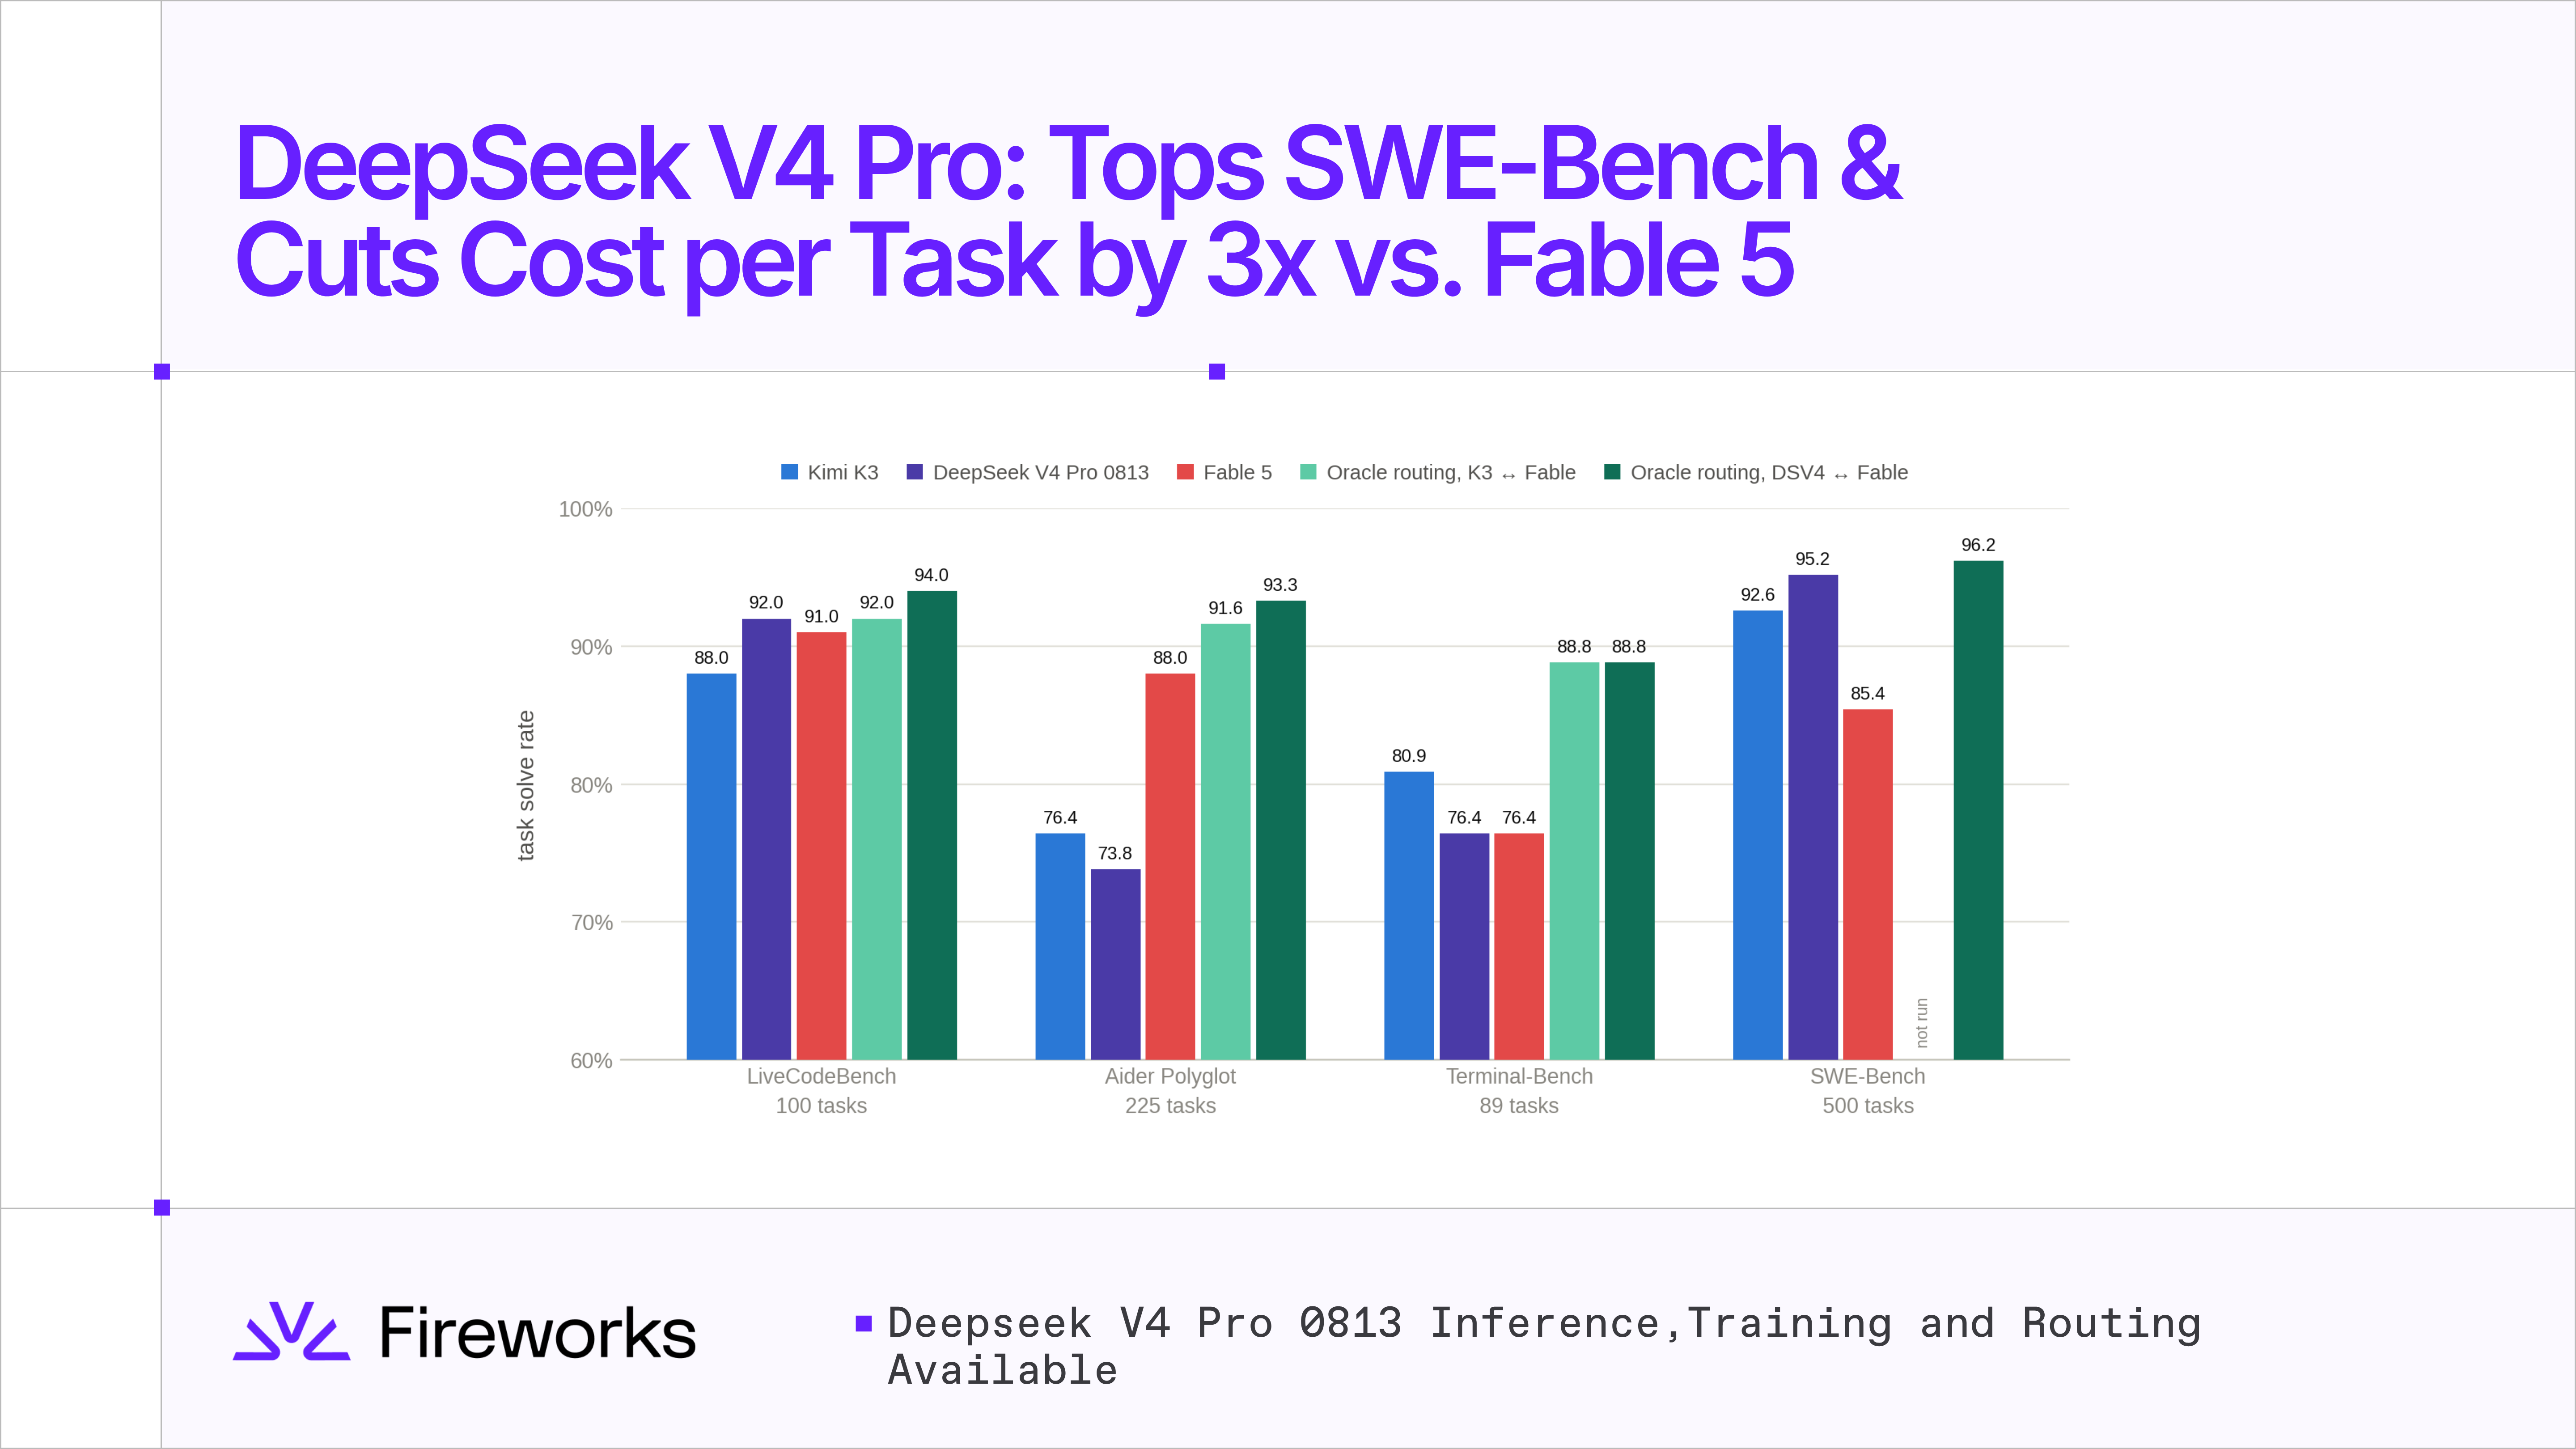
DeepSeek V4 Pro: Tops SWE-Bench & Cuts Cost per Task by 3x vs. Fable 5
Restore LLM Inference Capacity in Seconds with Shadow Engine Recovery in NVIDIA Dynamo

How to run any open model inside DeepSeek Harness
How leading platforms ensure observability for LLM inference
Beyond Visual CoT: Internalized Visual Thinking for Proactive Video Reasoning

Retrieval-augmented generation (RAG) for LLMs

 ShopifyBlog
Gisting: Compressing LLM Agent context to ↑ throughput and ↓ cost (2026)

ReAct Agents Explained: Concepts & Practical Uses

Developing Nemotron 3.5 Lightning NVFP4 with QAD Using NVIDIA Model Optimizer

A/B test models in production
Inference engineering for DeepSeek V4 Pro 0813
What are AI Hallucinations?
Introducing Gemini 3.7 Flash
How Decagon shipped real-time voice AI on Modal
Qdrant and Minima Deliver 2.92x More Agentic RAG Tasks per GPU-Hour
Serve Qwen3.8-2.4T-A95B, a 2.4T-Parameter Model, with Configurable Reasoning on NVIDIA GB300 NVL72

Qwen3.8-2.4T-A95B now available on Modal
 VercelBlog