Accelerating Large Language Model Training with Variable Sparse Pre-training and Dense Fine-tuning - Cerebras
Mar 4, 2025
Summary
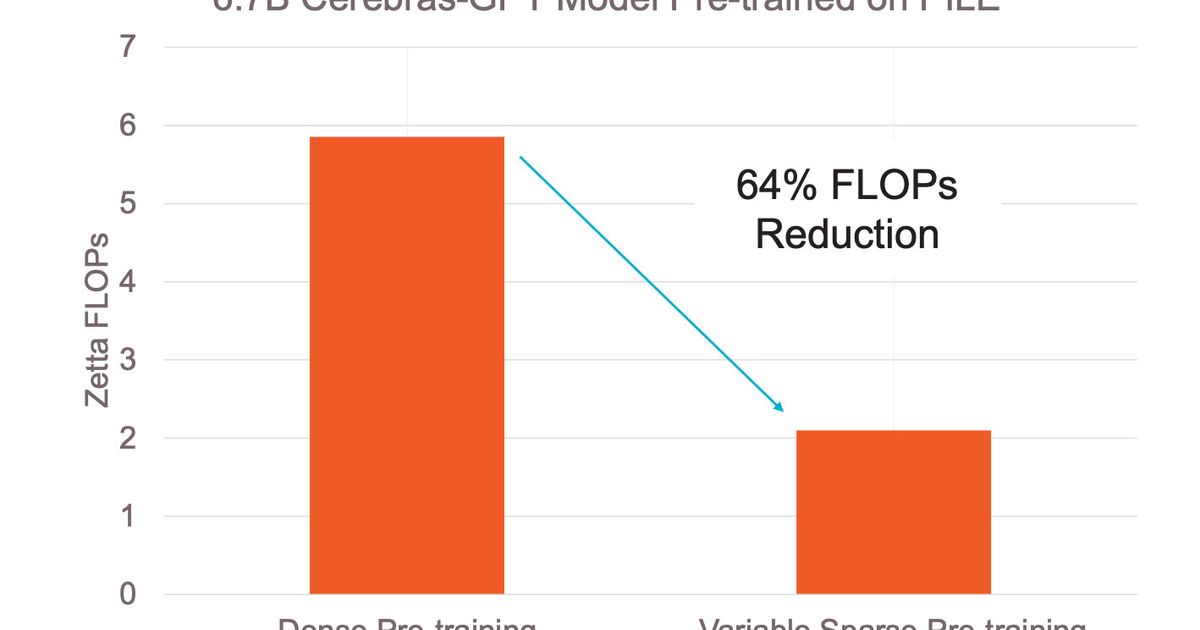
Introduces the Variable SPDF framework, which enhances the previous SPDF by densifying during pre-training (Stage-2) after an initial sparse pre-training stage (Stage-1). This approach aims to improve task-agnostic representations and offers finer control over pre-training FLOPs. Experiments show Variable SPDF outperforms SPDF for the same effective sparsity and matches dense baseline metrics for a 6.7B parameter model with 64% fewer pre-training FLOPs. The Cerebras Software Platform (CSoft) is highlighted for simplifying the implementation of this sparse training methodology.