Cerebras
Jun 18, 2025
Summary
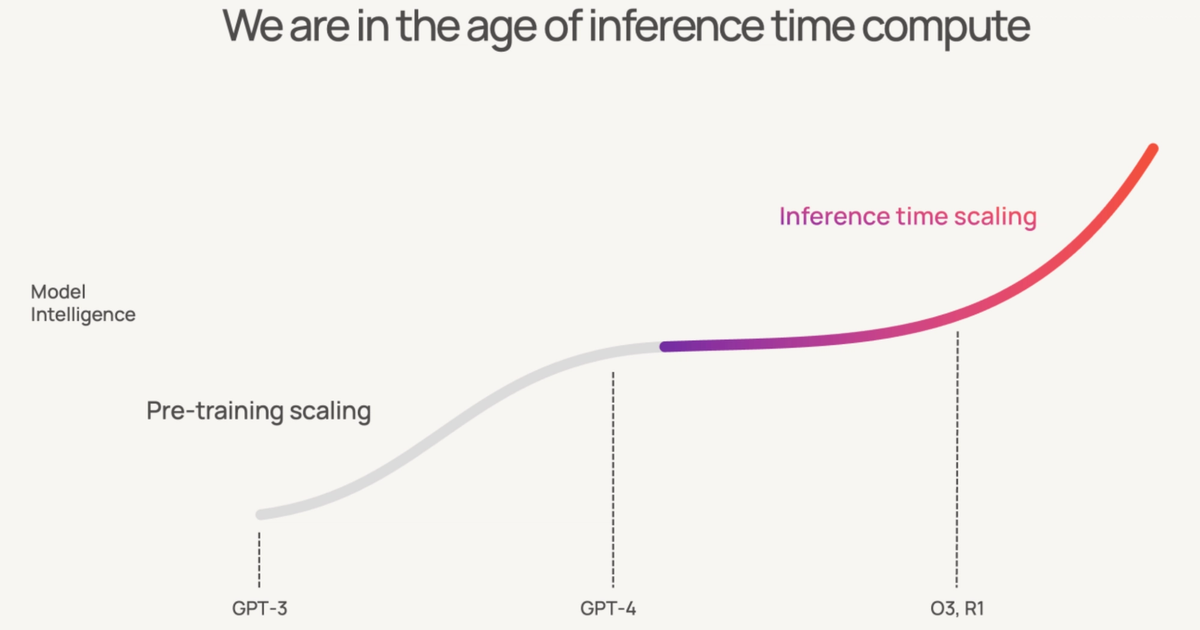
This post introduces the 'Cerebras scaling law,' which states that faster inference speed directly translates to higher model intelligence. It contrasts this with traditional scaling laws focused on model size and training data. The post highlights how Cerebras's wafer-scale architecture, by storing entire models on-chip, eliminates memory bandwidth bottlenecks and achieves inference speeds over 2,500 tokens/s. This speed enables the use of reasoning models (e.g., Qwen3-32B) in real-time applications, outperforming non-reasoning models and even closed-source frontier models in terms of intelligence and cost-effectiveness.