Cerebras
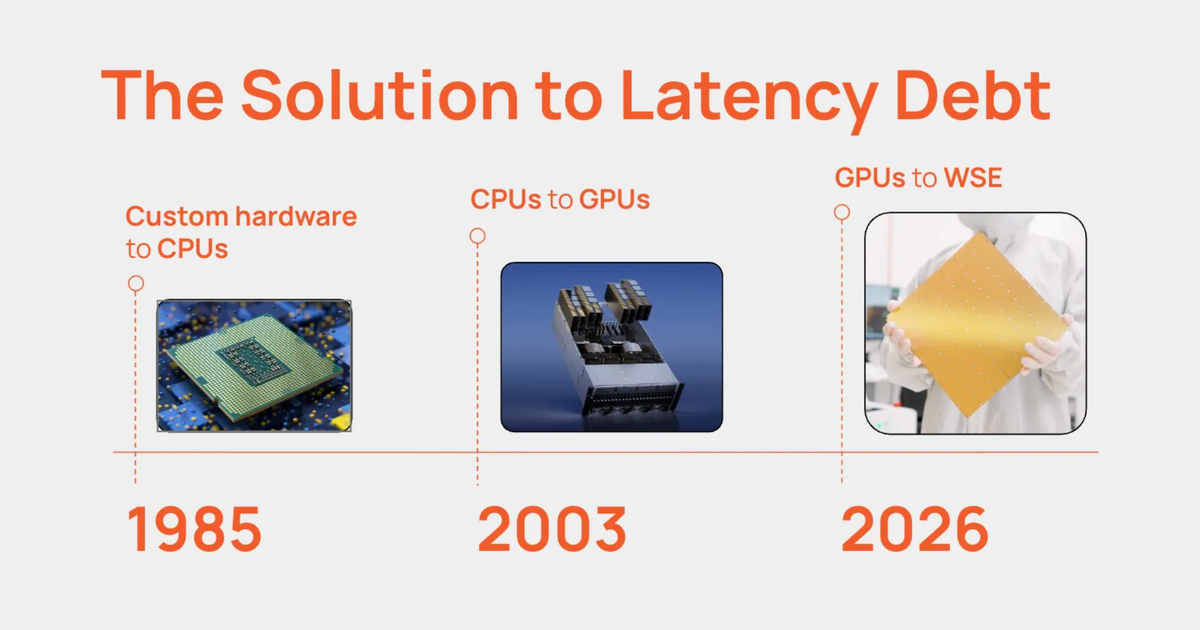
This post introduces the concept of 'latency debt' in AI, defining it as the accumulated cost of optimizing models faster than infrastructure, leading to slow user experiences. It quantifies the impact of larger models, reasoning tokens, longer context windows, and increased output lengths on this debt. The post argues that current GPU architectures are becoming a bottleneck for these latency-sensitive AI workloads and proposes Cerebras's Wafer-Scale Engine (WSE) as a superior alternative due to its on-chip data processing, which eliminates memory bandwidth constraints. It also cites major AI companies' investments in alternative inference hardware as validation of this trend. The post concludes by emphasizing the immediate benefits of optimized hardware for AI inference, transforming AI from a bottleneck to a collaborator.