Llama3.1 Model Quality Evaluation: Cerebras, Groq, SambaNova, Together, and Fireworks - Cerebras
Mar 17, 2025
Summary
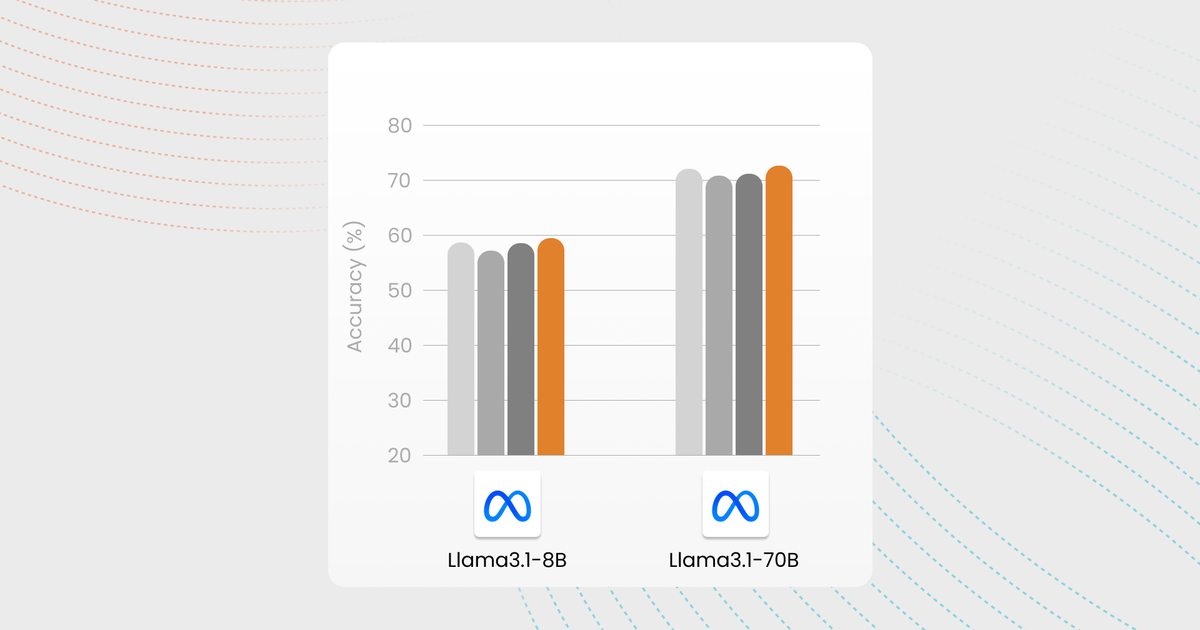
This post benchmarks the Llama3.1-8B and Llama3.1-70B Instruct models on Cerebras inference hardware against competitors (Groq, SambaNova, Together, Fireworks). It details rigorous evaluations across general reasoning (MMLU, MATH, GPQA, DROP, MGSM), coding (HumanEval, MBPP, HumanEval+, MBPP+), and multi-turn conversations (MT-Bench). Cerebras' Llama3.1-70B model is shown to outperform competitors on 9 out of 10 benchmarks, demonstrating leading accuracy and efficiency. The post emphasizes the importance of comprehensive, apples-to-apples benchmarking to ensure model quality, especially when techniques like quantization are used.