Why AI Assistants Are Slow—and How to Make Them Faster
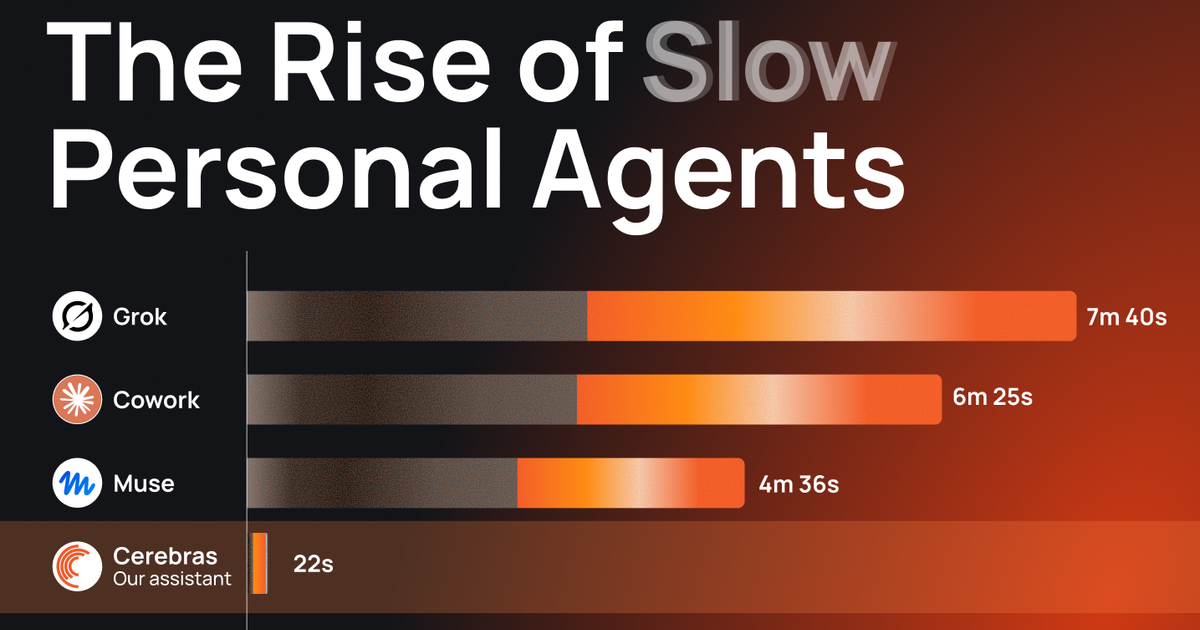
This post details how Cerebras's fast AI inference capabilities, combined with agent harness engineering, significantly reduce the latency of AI personal assistants. The authors demonstrate a 19x speedup in a dinner reservation task by optimizing the agent's workflow. Key improvements include: 1. Parallelizing independent checks (e.g., restaurant availability) to reduce sequential waiting. 2. Speeding up remaining model calls through faster inference on Cerebras hardware and reducing the model's cognitive load by saving learned procedures. 3. Reusing learned navigation and checking procedures as skills to avoid repetitive discovery work, reducing tool calls by over 80%. The post highlights the use of Qwen 3.8 27B on Cerebras with the Pi agent harness.