Designing layered guardrails for reliable AI agents | Decagon
Feb 23, 2026
Summary
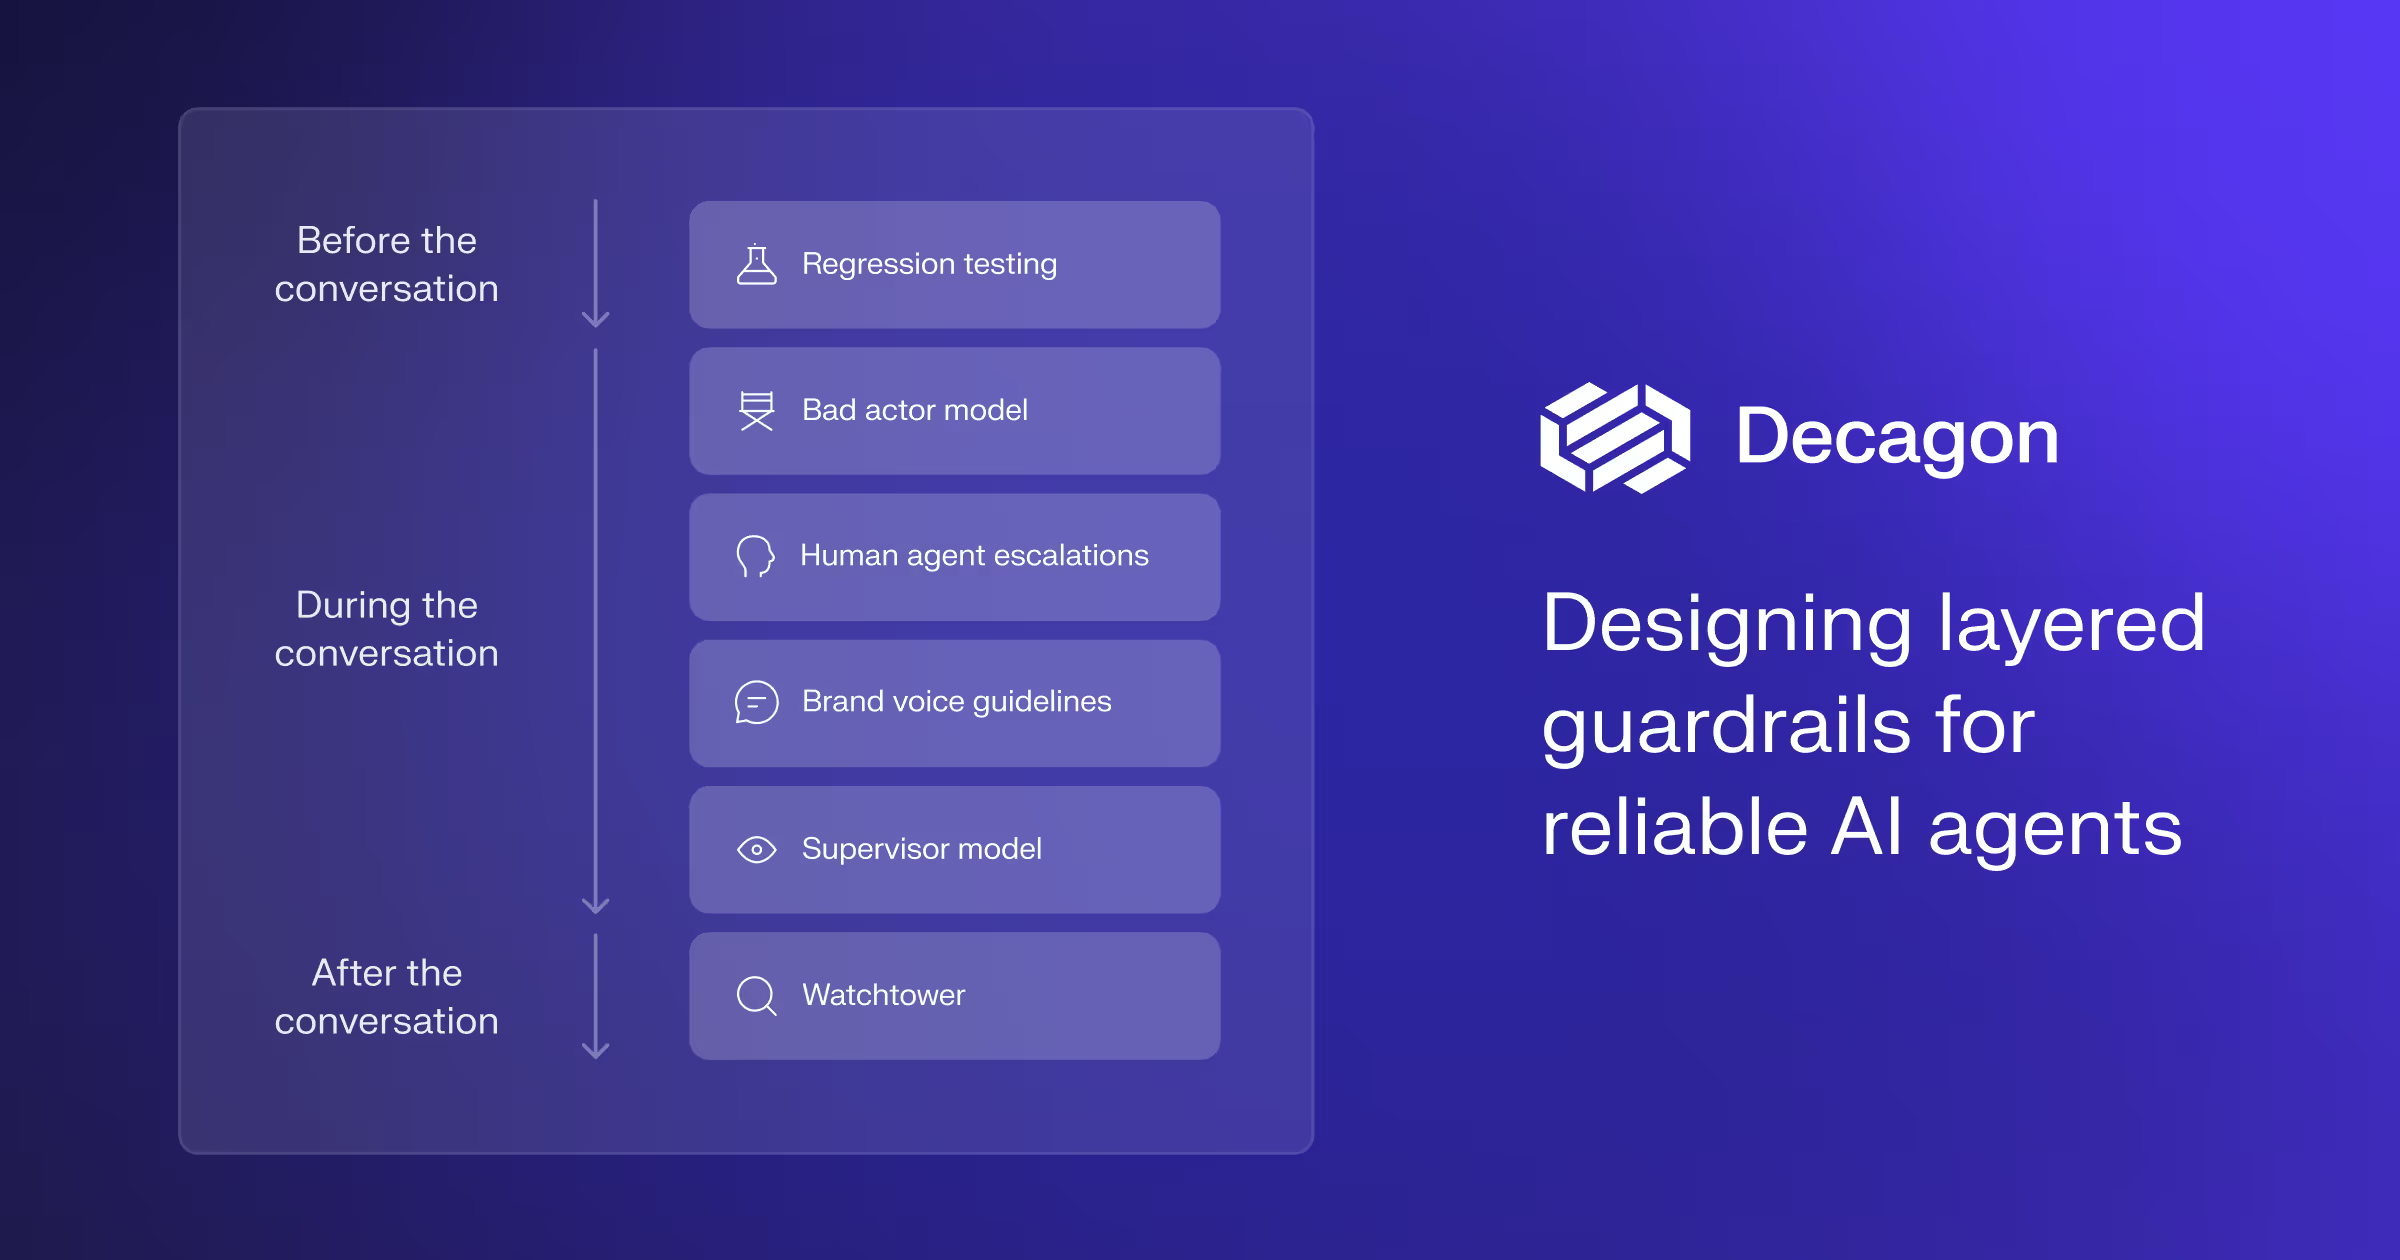
This post details the implementation of layered guardrails for AI agents to ensure reliability, safety, and brand alignment. It describes regression testing (single-turn and multi-turn interactions) before deployment, real-time guardrails during conversations (bad actor detection, human agent escalations, brand voice guidelines, response supervision) using separate fine-tuned models with minimal latency impact, and post-conversation analysis with Watchtower for continuous improvement. The technical depth includes details on how these guardrails function, such as parallel processing for bad actor detection and supervisor models evaluating responses for grounding and accuracy.
More from the AI Support Agent Platform trail
- DuetBench-2: Measuring agent self-improvement in production | Decagon
- Autopilot in production: Governance of self-improving agents | Decagon
- Proactive customer service strategies for CX leaders | Decagon
- Automated customer service without losing the human touch | Decagon
- Your Decagon agent can now search the live web | Decagon