Cannes: How ML saves us $1.7M a year on document previews
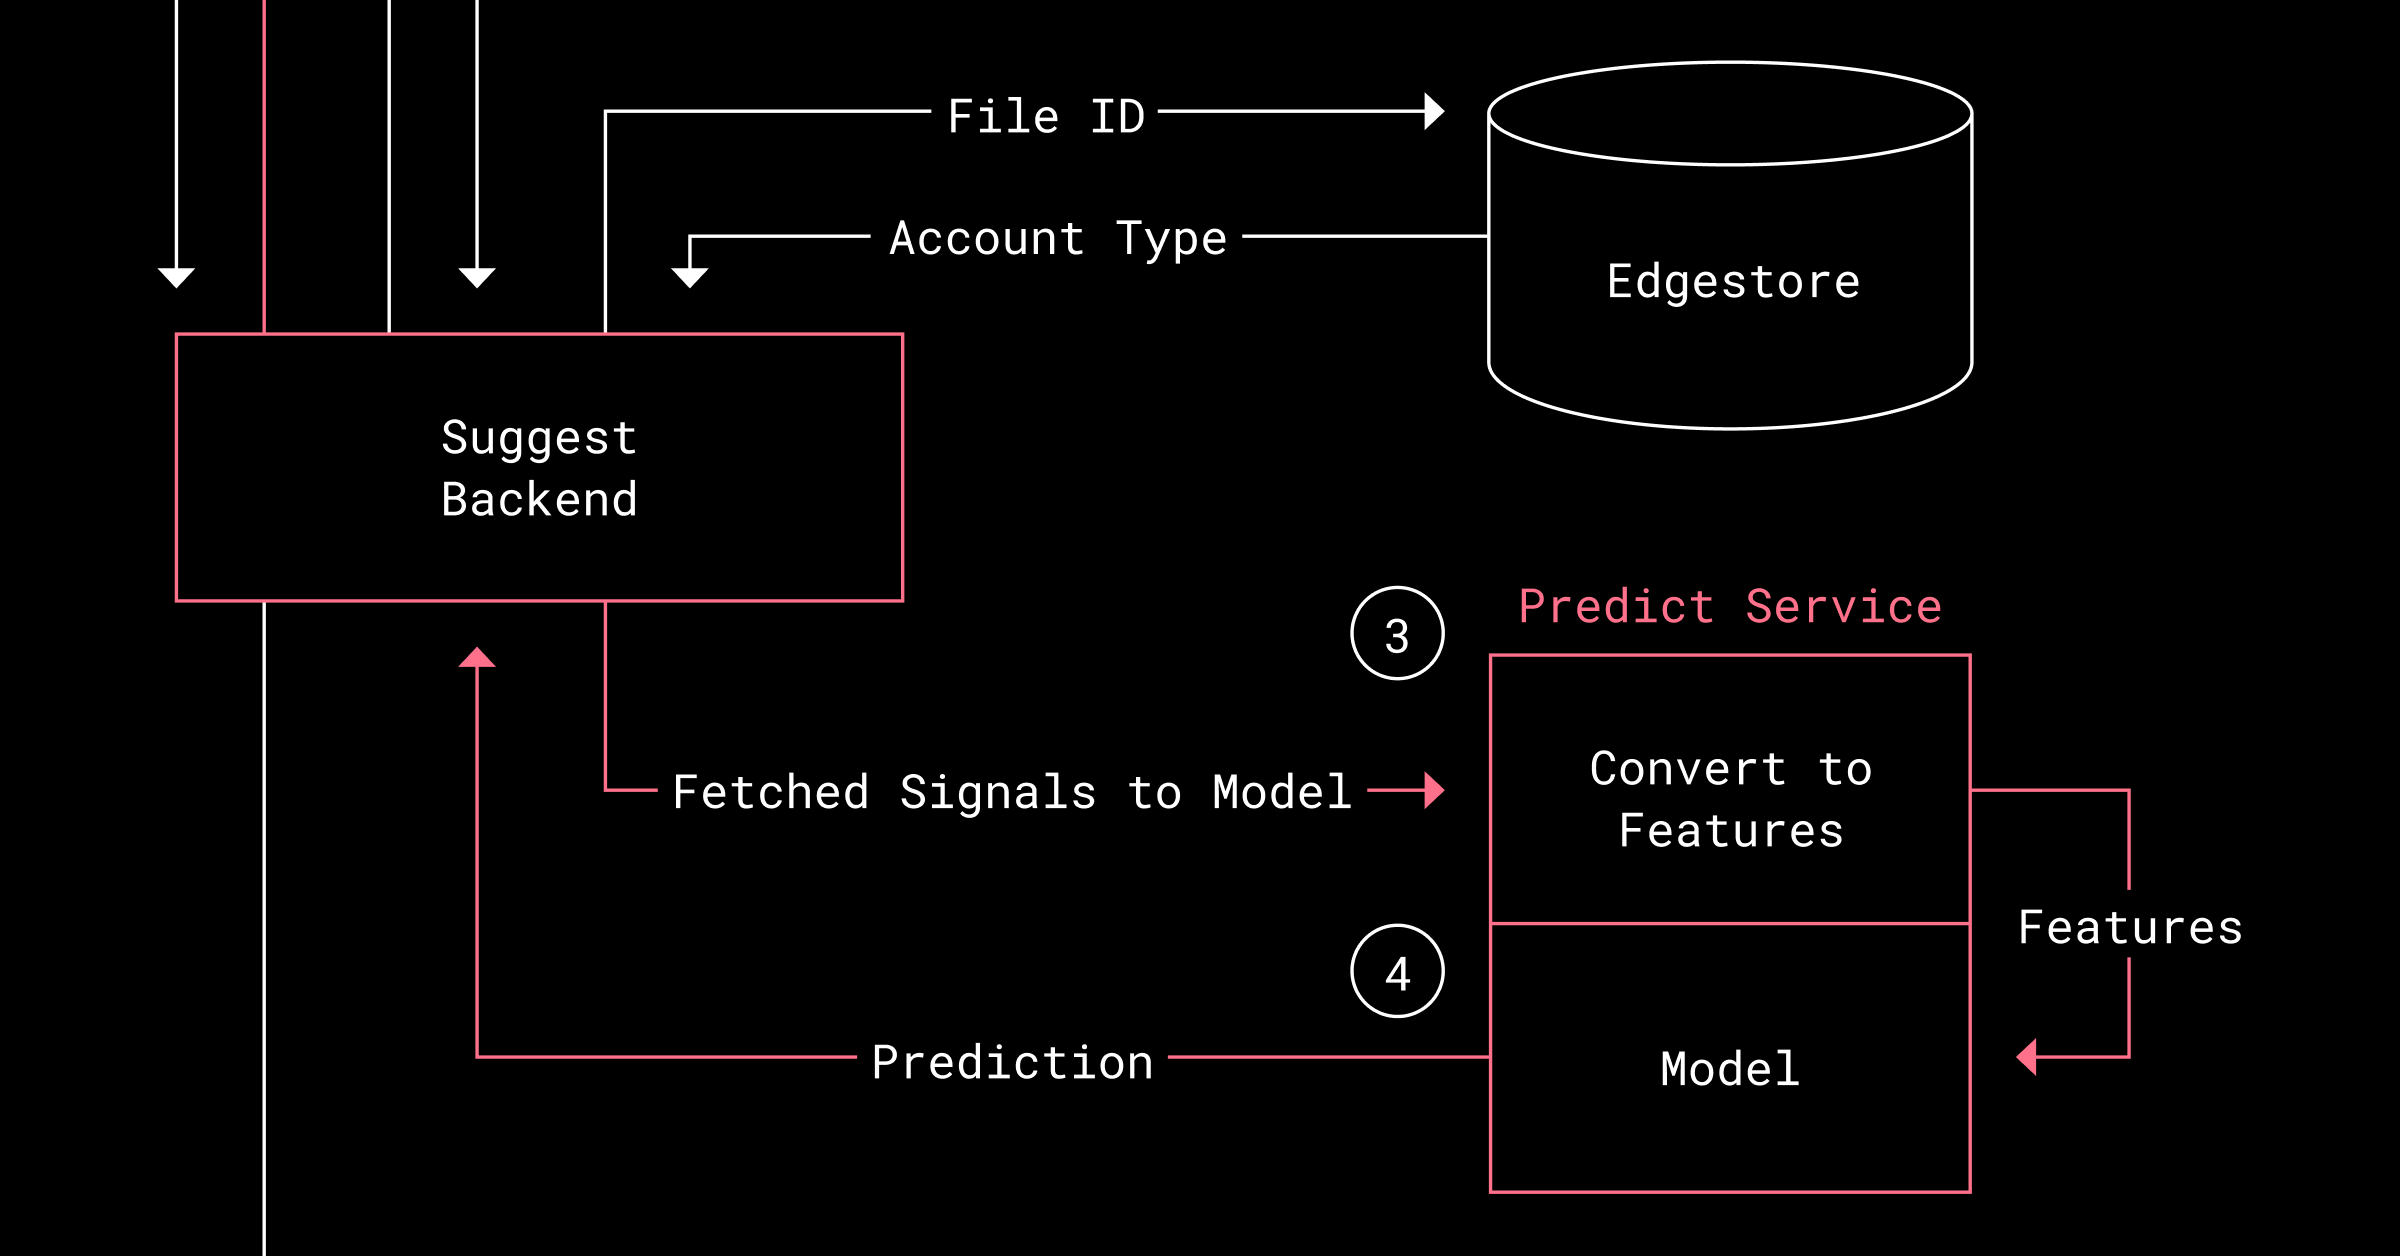
This post details the application of a gradient-boosted classifier (Cannes v1) to predict the likelihood of document previews being viewed. The system integrates with the Riviera platform to optimize pre-warming of preview assets, saving $1.7M annually. Key technical contributions include the development of a prediction pipeline that fetches live signals (from Edgestore and User Profile Service) and feeds them into a model, the use of A/B testing via Stormcrow to validate performance, and the careful consideration of tradeoffs between cost-benefit, complexity, interpretability, and deployment cost. The model uses file extension, account type, and recent activity as features, achieving >70% accuracy in predicting preview usage within 60 days.
More from the Universal Content Processing Platform trail
- Evolving our calendar assistant Reclaim to be AI-native without starting over
- How our universal content processing platform Riviera evolved for AI and beyond
- How we used DSPy to turn AI evaluations into better responses in Dash chat
- How we optimized Dash's relevance judge with DSPy
- Using LLMs to amplify human labeling and improve Dash search relevance