DeepSeek-V4.1-Flash on Fireworks: Astra-level DeepSWE at 1/15th the cost
Sep 14, 2026
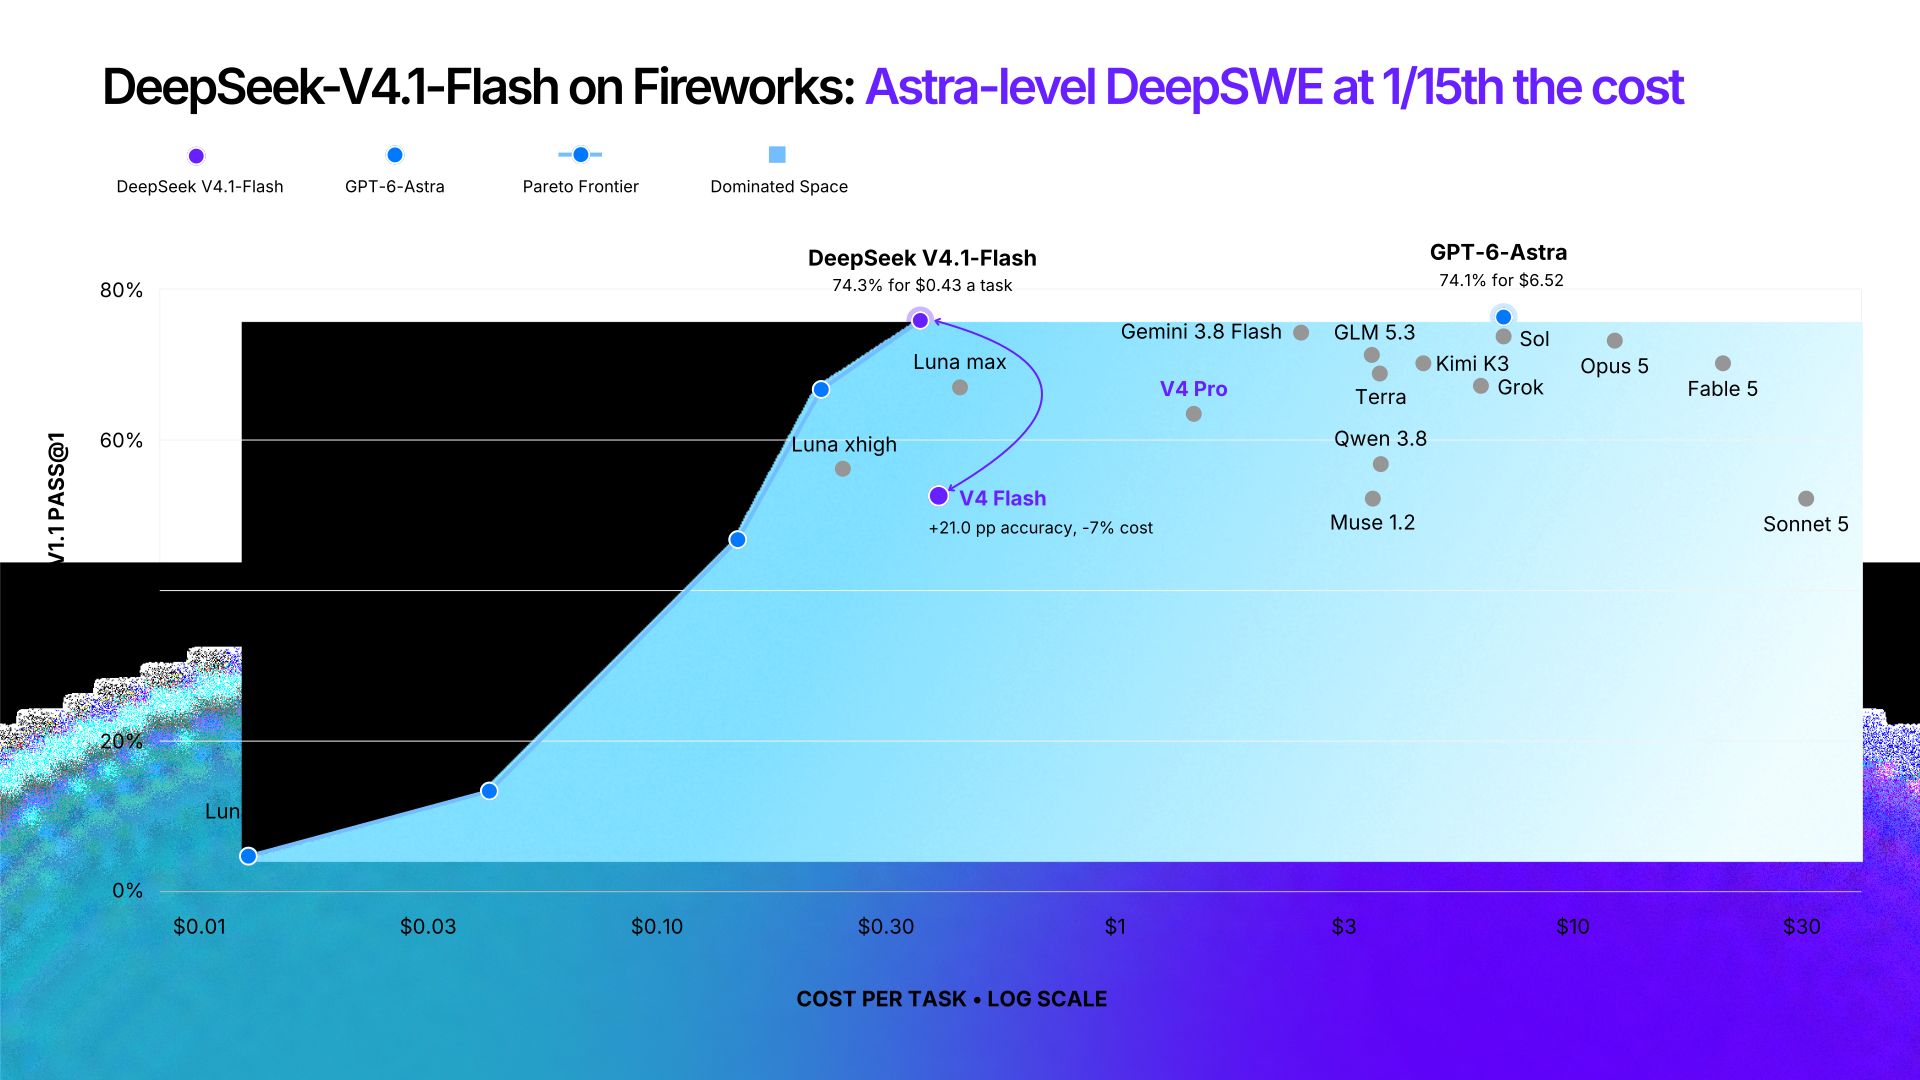
Summary
This post details the integration of DeepSeek-V4.1-Flash onto the Fireworks platform, emphasizing its cost-performance benefits for autonomous software engineering. It introduces the model's split activation architecture (552B MoE with 8B input, 16B output active parameters) and KV cache optimizations (4x HBM reduction, 8x SSD overhead reduction) that significantly reduce token spend, especially for input-heavy agentic workflows. Benchmarks on DeepSWE and Terminal-Bench 2.1 show comparable quality to higher-cost models like GPT-6 Astra at a fraction of the price. It also highlights DeepSeek-V4.1-Flash's limitations on complex reasoning tasks (HLE) and suggests multi-model routing as a strategy to achieve superior performance.