How to build agents that actually work: A practical guide to evaluating AI
Aug 10, 2026
Summary
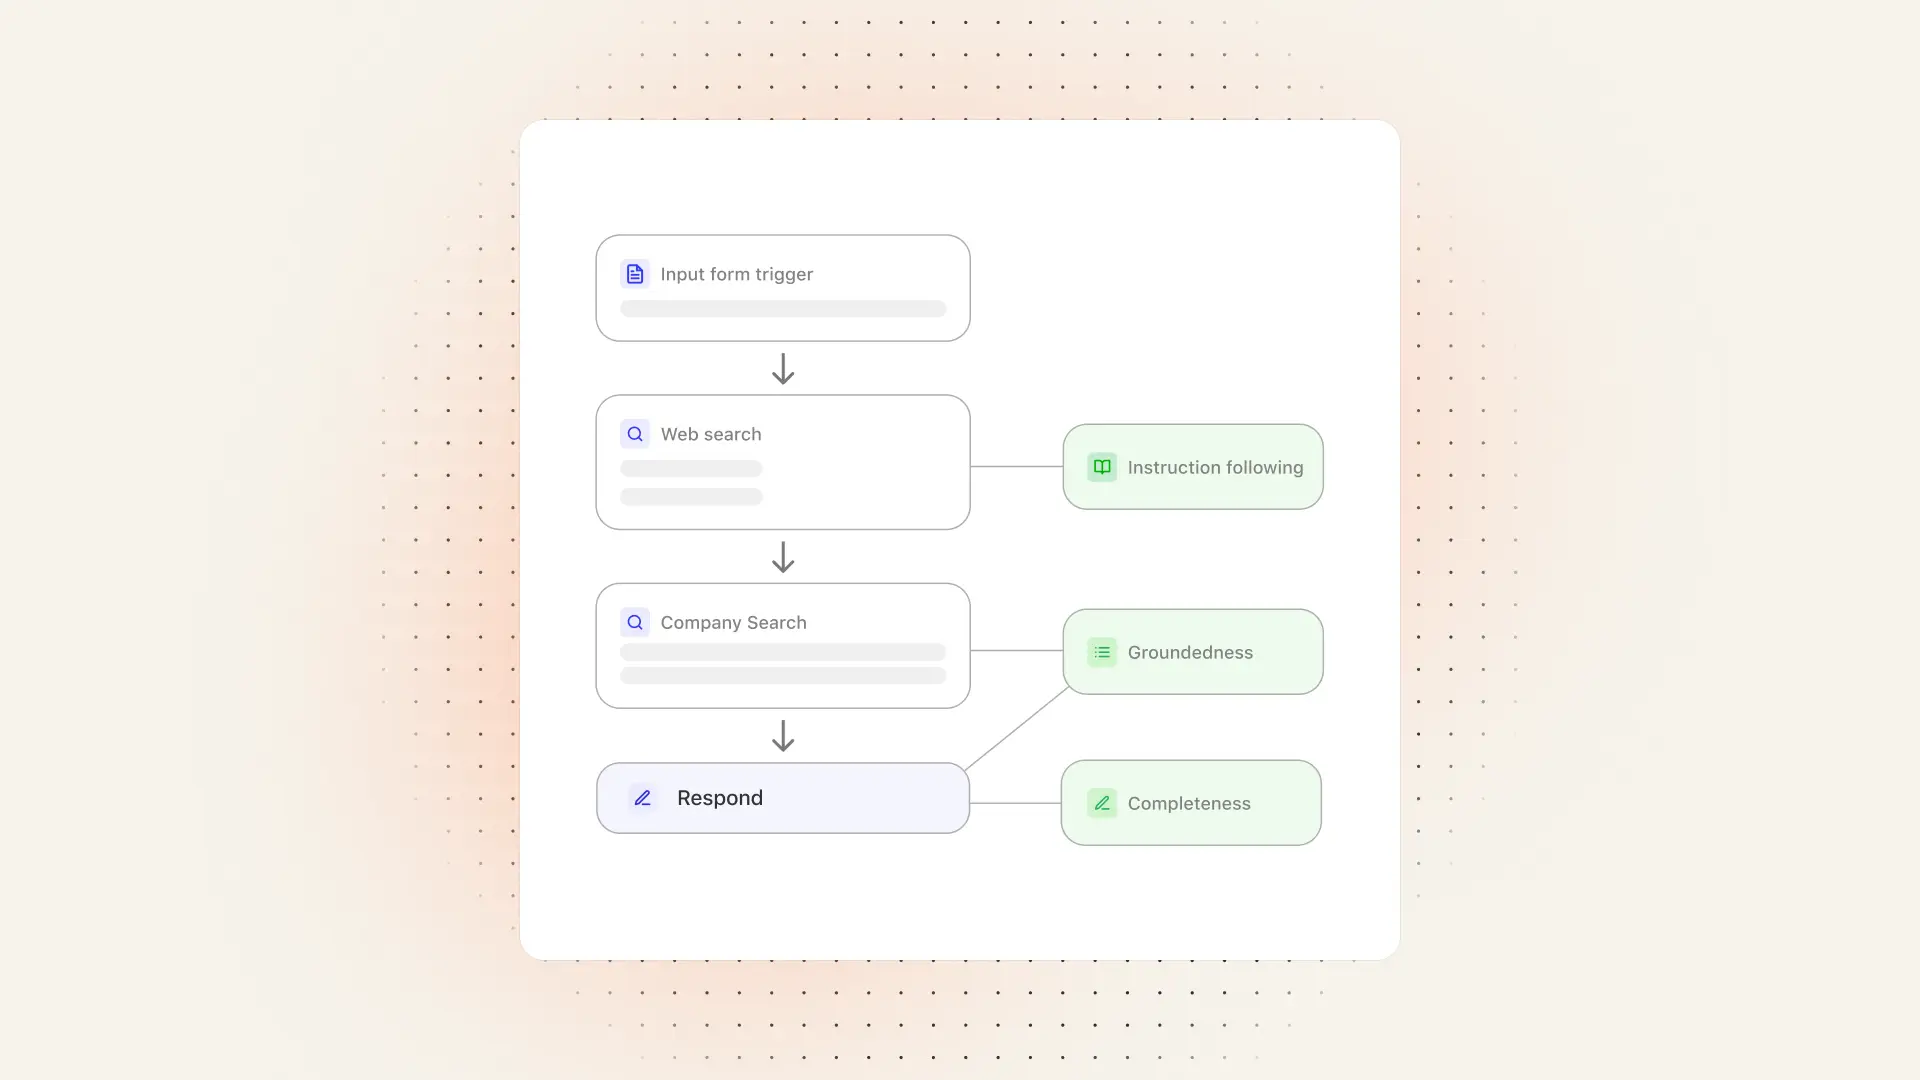
This post details a practical guide to evaluating AI agents, focusing on creating evalsets with real-world examples and defining success metrics like message quality (completeness, personalization, tone, groundedness). It outlines a systematic approach to improving agents by refining instructions, structuring context, tuning parameters, and selecting appropriate LLMs. The post also discusses scaling evaluations through automation and LLM grading, and integrating user feedback. This contributes to the 'Security AI Agents' thread by providing a methodology for ensuring agent reliability and trustworthiness, which is crucial for security applications.
More from the Security AI Agents trail
- How Glean ensures skills stay secure and permissions aware
- AI Agents for Financial Compliance: How Enterprise AI Is Solving the Regulatory Reporting Challenge
- Scale AI usage without runaway spend with Glean’s AI usage controls
- AI is its own best safeguard: Glean uses AI to detect jailbreak attempts at 97.8% accuracy
- What is AI security?