Beyond =~: How Milvus 3.0 Turns Regex into a Native Database Filter
Aug 5, 2026Buqian Zheng
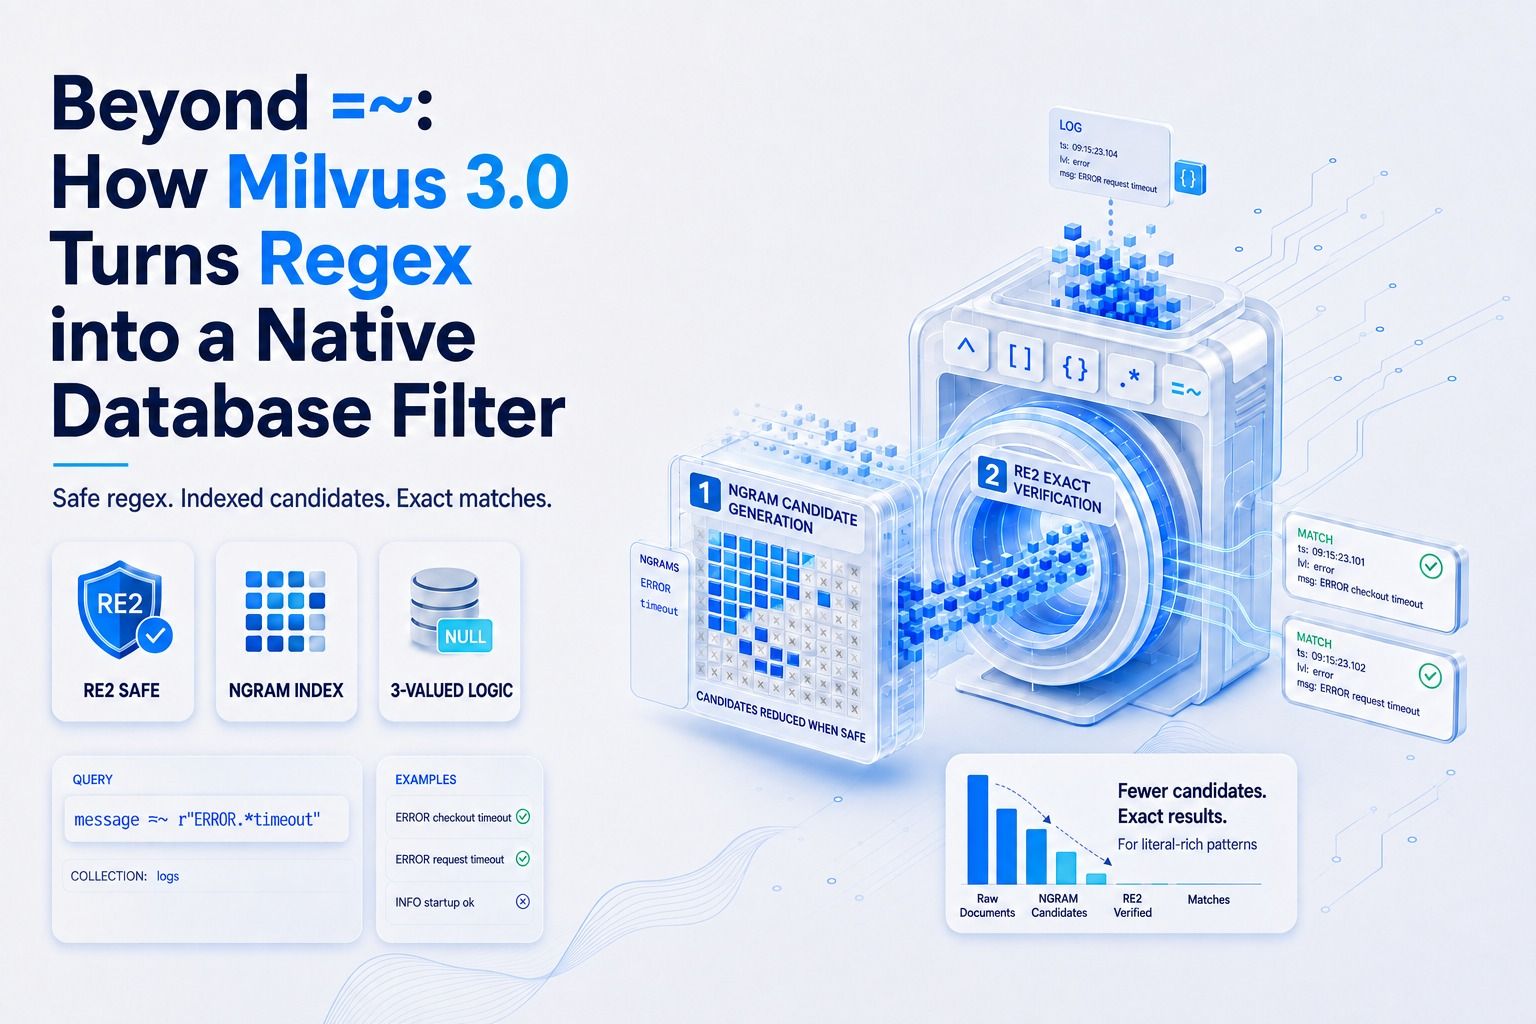
Summary
This post details the implementation of native regex filtering (`=~`, `!~`) in Milvus 3.0. It covers the design choices for user-facing semantics, the use of raw strings for manageable escaping, the adoption of RE2 for predictable cost and avoidance of ReDoS, and a layered execution path including rewriting simple regex, treating regex as a heavy predicate, using Volnitsky string search for literal prefiltering, and NGRAM indexing for candidate generation. It also addresses the handling of nullability with three-valued logic and the importance of preserving correctness when candidate reduction is not provably safe.
More from the Regex Filtering trail
- Phrase Match with Slop in Milvus 2.6: How to Improve Phrase-Level Full-Text Search Accuracy
- Introducing the Milvus Ngram Index: Faster Keyword Matching and LIKE Queries for Agent Workloads
- JSON Shredding in Milvus: 88.9x Faster JSON Filtering with Flexibility
- Vector Search in the Real World: How to Filter Efficiently Without Killing Recall
- Milvus 2.2.9: A Highly Anticipated Release with Optimal User Experience