How to Choose the Right Embedding Model?
Apr 9, 2025Lumina Wang
Summary
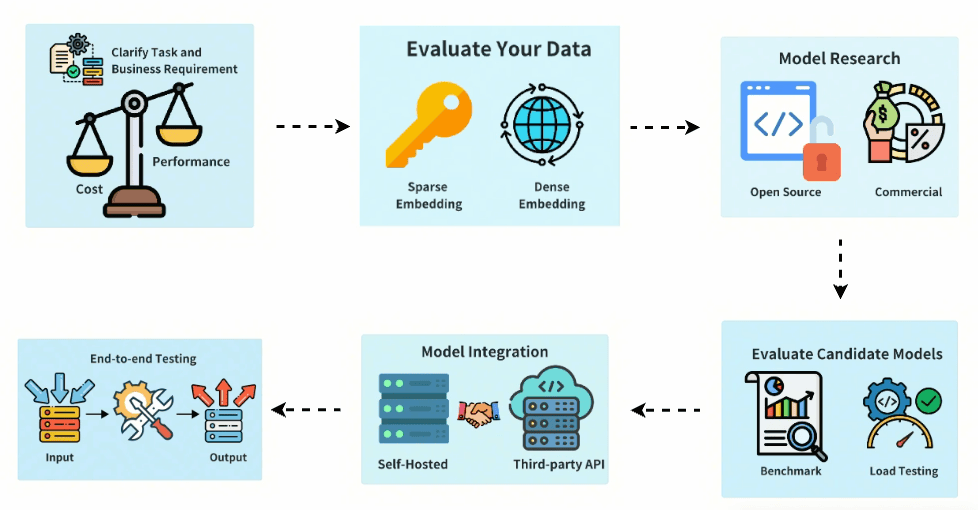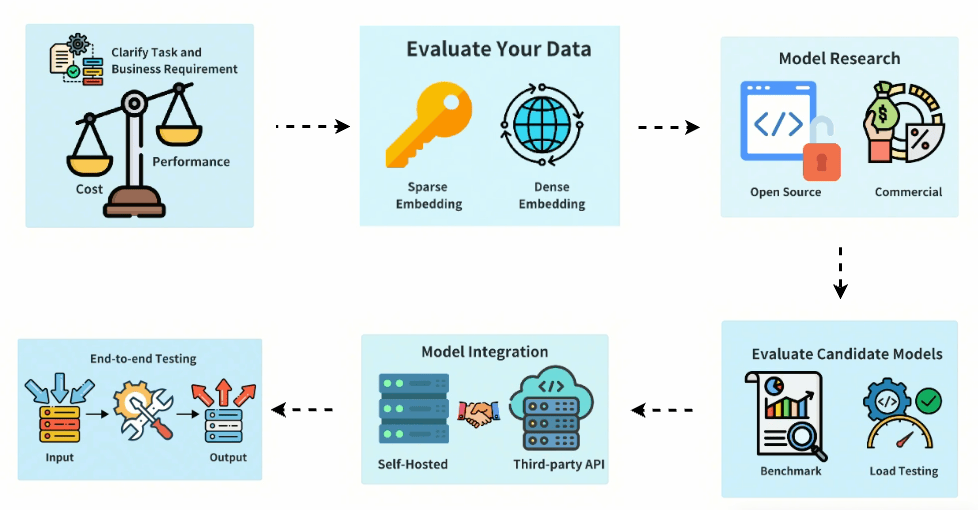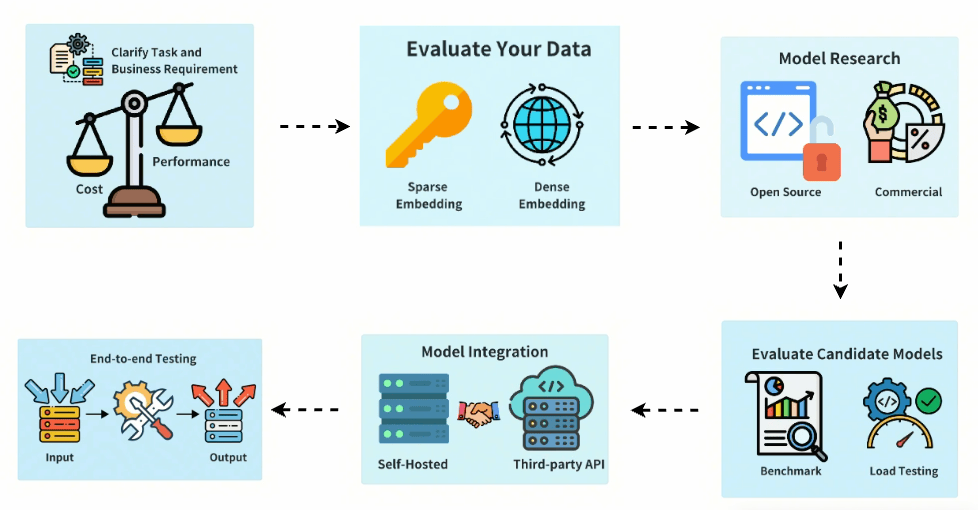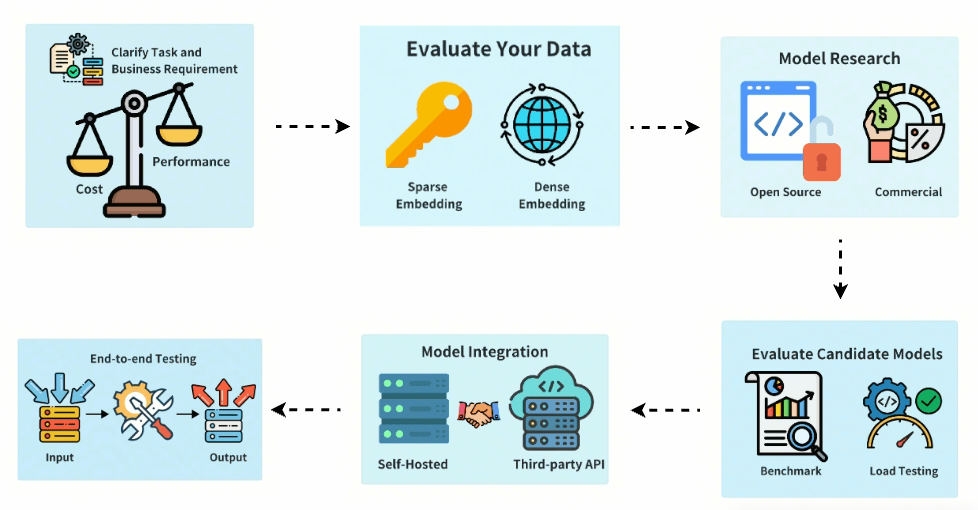
This post provides a practical framework for selecting embedding models, detailing steps such as defining task and business requirements, evaluating data characteristics (modality, domain specificity, embedding type), researching available models (popularity, licensing), evaluating candidate models (accuracy, benchmark performance, load testing), planning model integration (weights selection, self-hosting vs. third-party inference, API design), and conducting end-to-end testing (performance, robustness). It emphasizes the importance of aligning model choice with specific use cases and operational constraints.
More from the AI Data Storage Engine trail
- Milvus Snapshots: Point-in-Time Collection Views Without Copying Data
- Announcing Milvus 3.0: Lake-Native Vector Search and a More Powerful Retrieval Engine
- How to Recover Milvus Data After etcd Corruption Without a Backup
- Open Tag: An Open-Source Claude Tag for Claude Code and Codex
- How Force Merge Compaction Nearly Doubled Milvus Search QPS