Jev vs. LLMs in Agentic Search
Oct 9, 2026Cheney Zhang
Summary
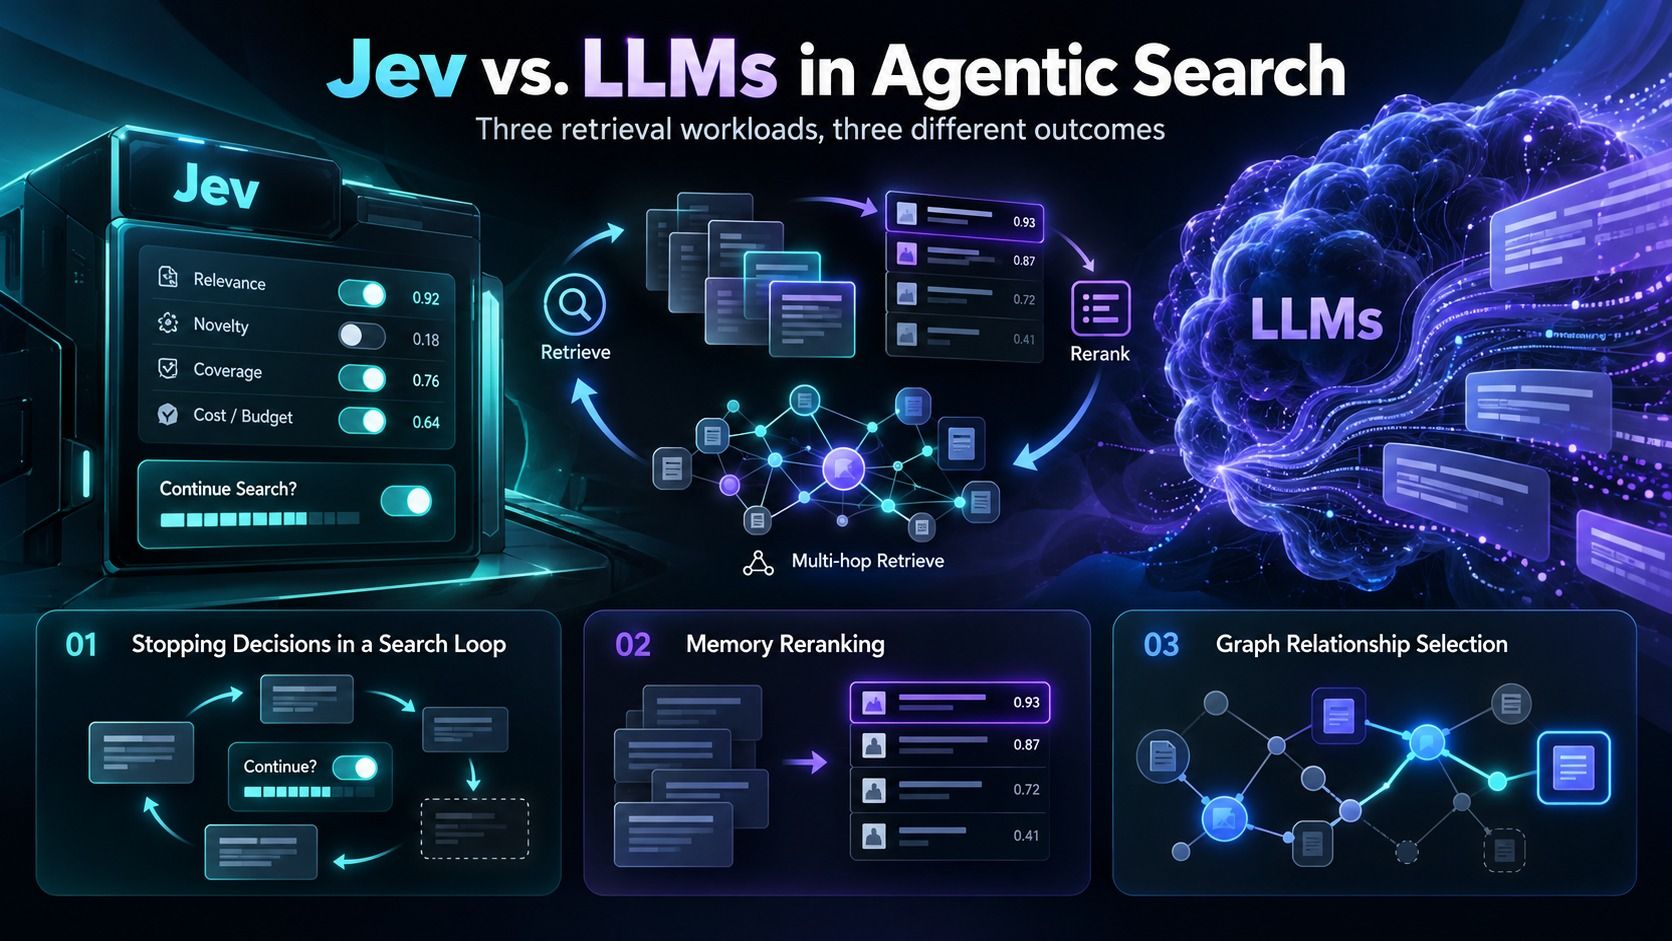
This post evaluates the performance of Jev, a specialized decision-making model, against general-purpose LLMs (DeepSeek Flash, GPT-4o-mini, GPT-5-mini, Voyage rerank-3) in three agentic search scenarios: stopping decisions in iterative search, memory reranking for coding agents, and relationship filtering in multi-hop graph retrieval. It quantifies trade-offs in recall, latency, and estimated API cost for each scenario, demonstrating Jev's potential for faster, cheaper decisions in narrowly defined tasks while highlighting the continued need for more capable generative models in complex reasoning scenarios. The experiments were conducted using Milvus-integrated open-source projects (DeepSearcher, MemSearch, Vector Graph RAG).
More from the AI Agent Tooling and Integration trail
- When AI Agents Do the Work, What Do We Lose?
- Claude Context: Reduce Claude Code Token Usage with Milvus-Powered Code Retrieval
- DeepSeek V4 vs GPT-5.5 vs Qwen3.6: Which Model Should You Use?
- We Built Graph RAG Without the Graph Database
- We Read Claude Code's Leaked Source. Here's How Its Memory Actually Works