Reflections on ChatGPT and Claude’s Memory Systems: What It Takes to Enable On-Demand Conversational Retrieval
Jan 9, 2026Min Yin
Summary
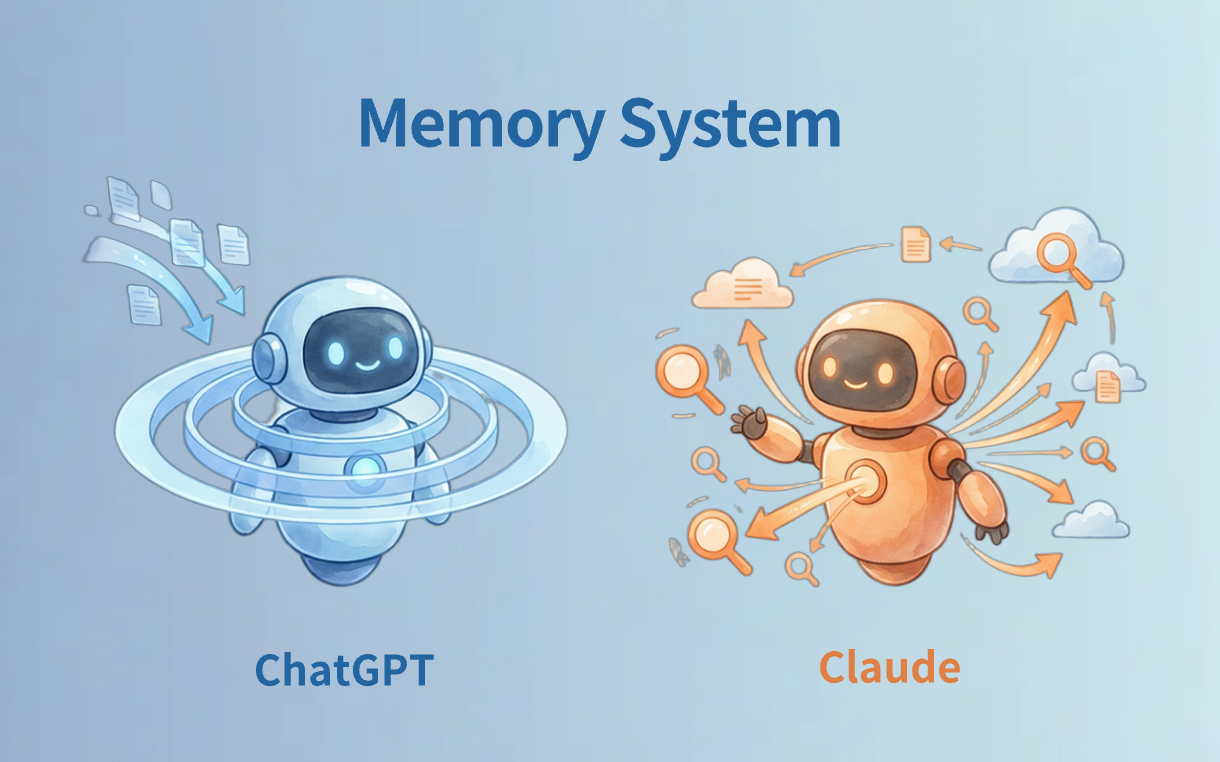
This post details how Milvus 2.6's hybrid dense-sparse retrieval, efficient scalar filtering, and tiered storage enable on-demand conversational retrieval for AI agents. It contrasts ChatGPT's precomputed context injection with Claude's RAG-style, on-demand retrieval, highlighting the architectural constraints (low latency tolerance, hybrid search, storage-compute separation) that make the latter practical with systems like Milvus.
More from the AI Data Storage Engine trail
- Milvus Snapshots: Point-in-Time Collection Views Without Copying Data
- Announcing Milvus 3.0: Lake-Native Vector Search and a More Powerful Retrieval Engine
- How to Recover Milvus Data After etcd Corruption Without a Backup
- Open Tag: An Open-Source Claude Tag for Claude Code and Codex
- How Force Merge Compaction Nearly Doubled Milvus Search QPS