GenRec: Towards LLM-Native Recommendation at Netflix
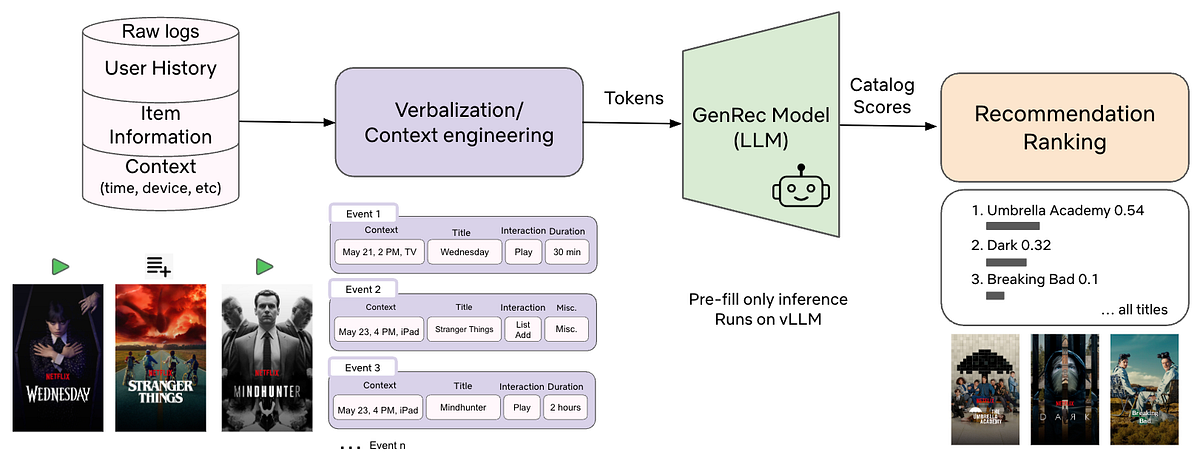
This post introduces GenRec, an LLM-backed recommendation ranker that post-trains an internal foundation LLM on Netflix-specific data and objectives. GenRec verbalizes user histories, item metadata, and context into natural-language prompts, then uses a catalog-aware scoring head to rank items. It employs a two-phase training framework: Phase 1 adapts a foundation LLM on Netflix corpora, and Phase 2 post-trains it for ranking. Context engineering is used to manage the LLM's token budget. The training objectives include a catalog-aware ranking objective, a language modeling objective, and reward-weighted loss for alignment with long-term member value and business goals. GenRec runs in prefill-only mode on vLLM for cost efficiency and achieved statistically significant improvements in a large-scale A/B test.