Cassandra: Data-Driven Configuration
Sep 1, 2015Noel Cody
Summary
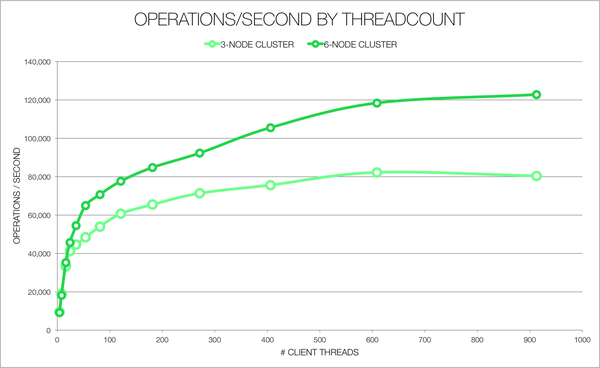
This post details the use of the `cassandra-stress` tool for data-driven configuration and capacity planning of Spotify's Cassandra clusters. It walks through an example scenario of setting up a new service with a write-heavy, real-time pipeline and batch reads. The process involves defining a YAML profile for `cassandra-stress` that specifies the schema, data shape (column specifications), and queries. The post presents results from load tests on 3 and 6-node clusters, varying client connection counts, consistency levels (ONE vs. QUORUM), and column data sizes. The findings inform decisions about cluster size, column data limits, and the feasibility of increasing consistency levels while meeting latency SLAs.