How We Improved Data Discovery for Data Scientists at Spotify
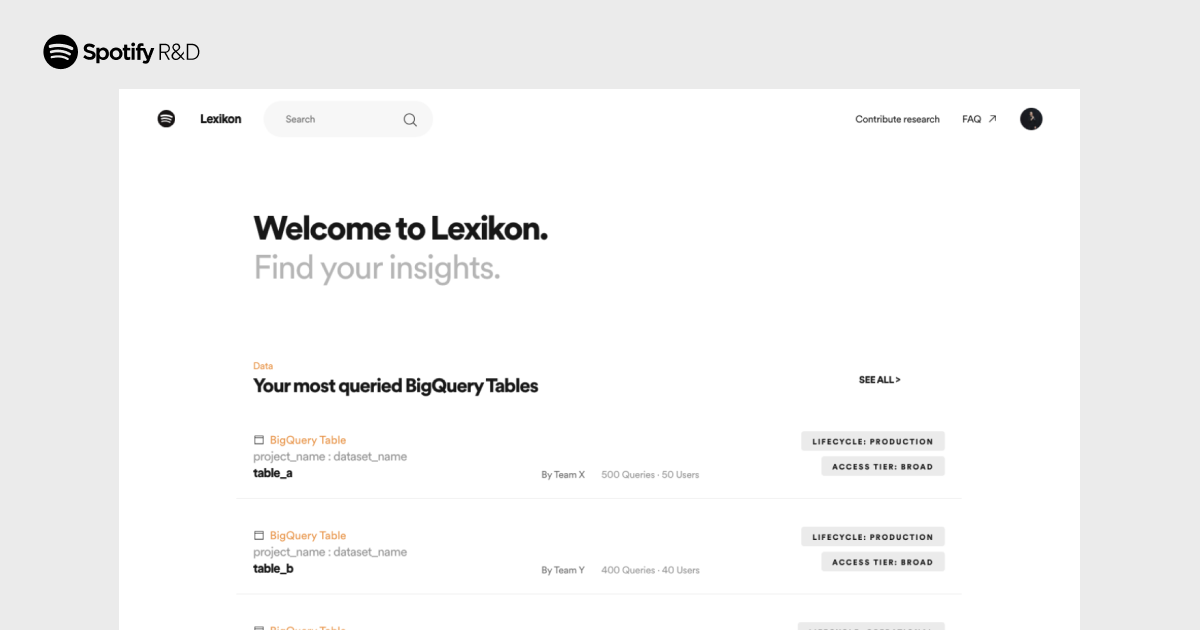
This post details the iteration on Spotify's Lexikon platform to improve data discovery for data scientists. It describes the diagnosis of the problem, which stemmed from an explosion of dataset creation in BigQuery and increased hiring of insights specialists, leading to localized impact and difficulty finding datasets. The post outlines two primary areas of improvement: understanding user intent for both low-intent (personalized recommendations on the homepage) and high-intent (popularity-weighted search ranking, new entity pages like schema fields and people) data discovery. It also discusses enabling knowledge exchange through people by mapping expertise and providing supplemental information in collaboration tools, moving beyond a purely codification strategy.
More from the Data Lake Indexing for Point Queries trail
- Indexing the Data Lake for Online Point Queries | Spotify Engineering
- Encoding Your Domain Expert: The Context Layer Behind Spotify's Data Assistant | Spotify Engineering
- How Spotify Optimized the Largest Dataflow Job Ever for Wrapped 2020
- It’s All Just Wiggly Air: Building Infrastructure to Support Audio Research
- Introducing Chartify: Easier chart creation in Python for data scientists