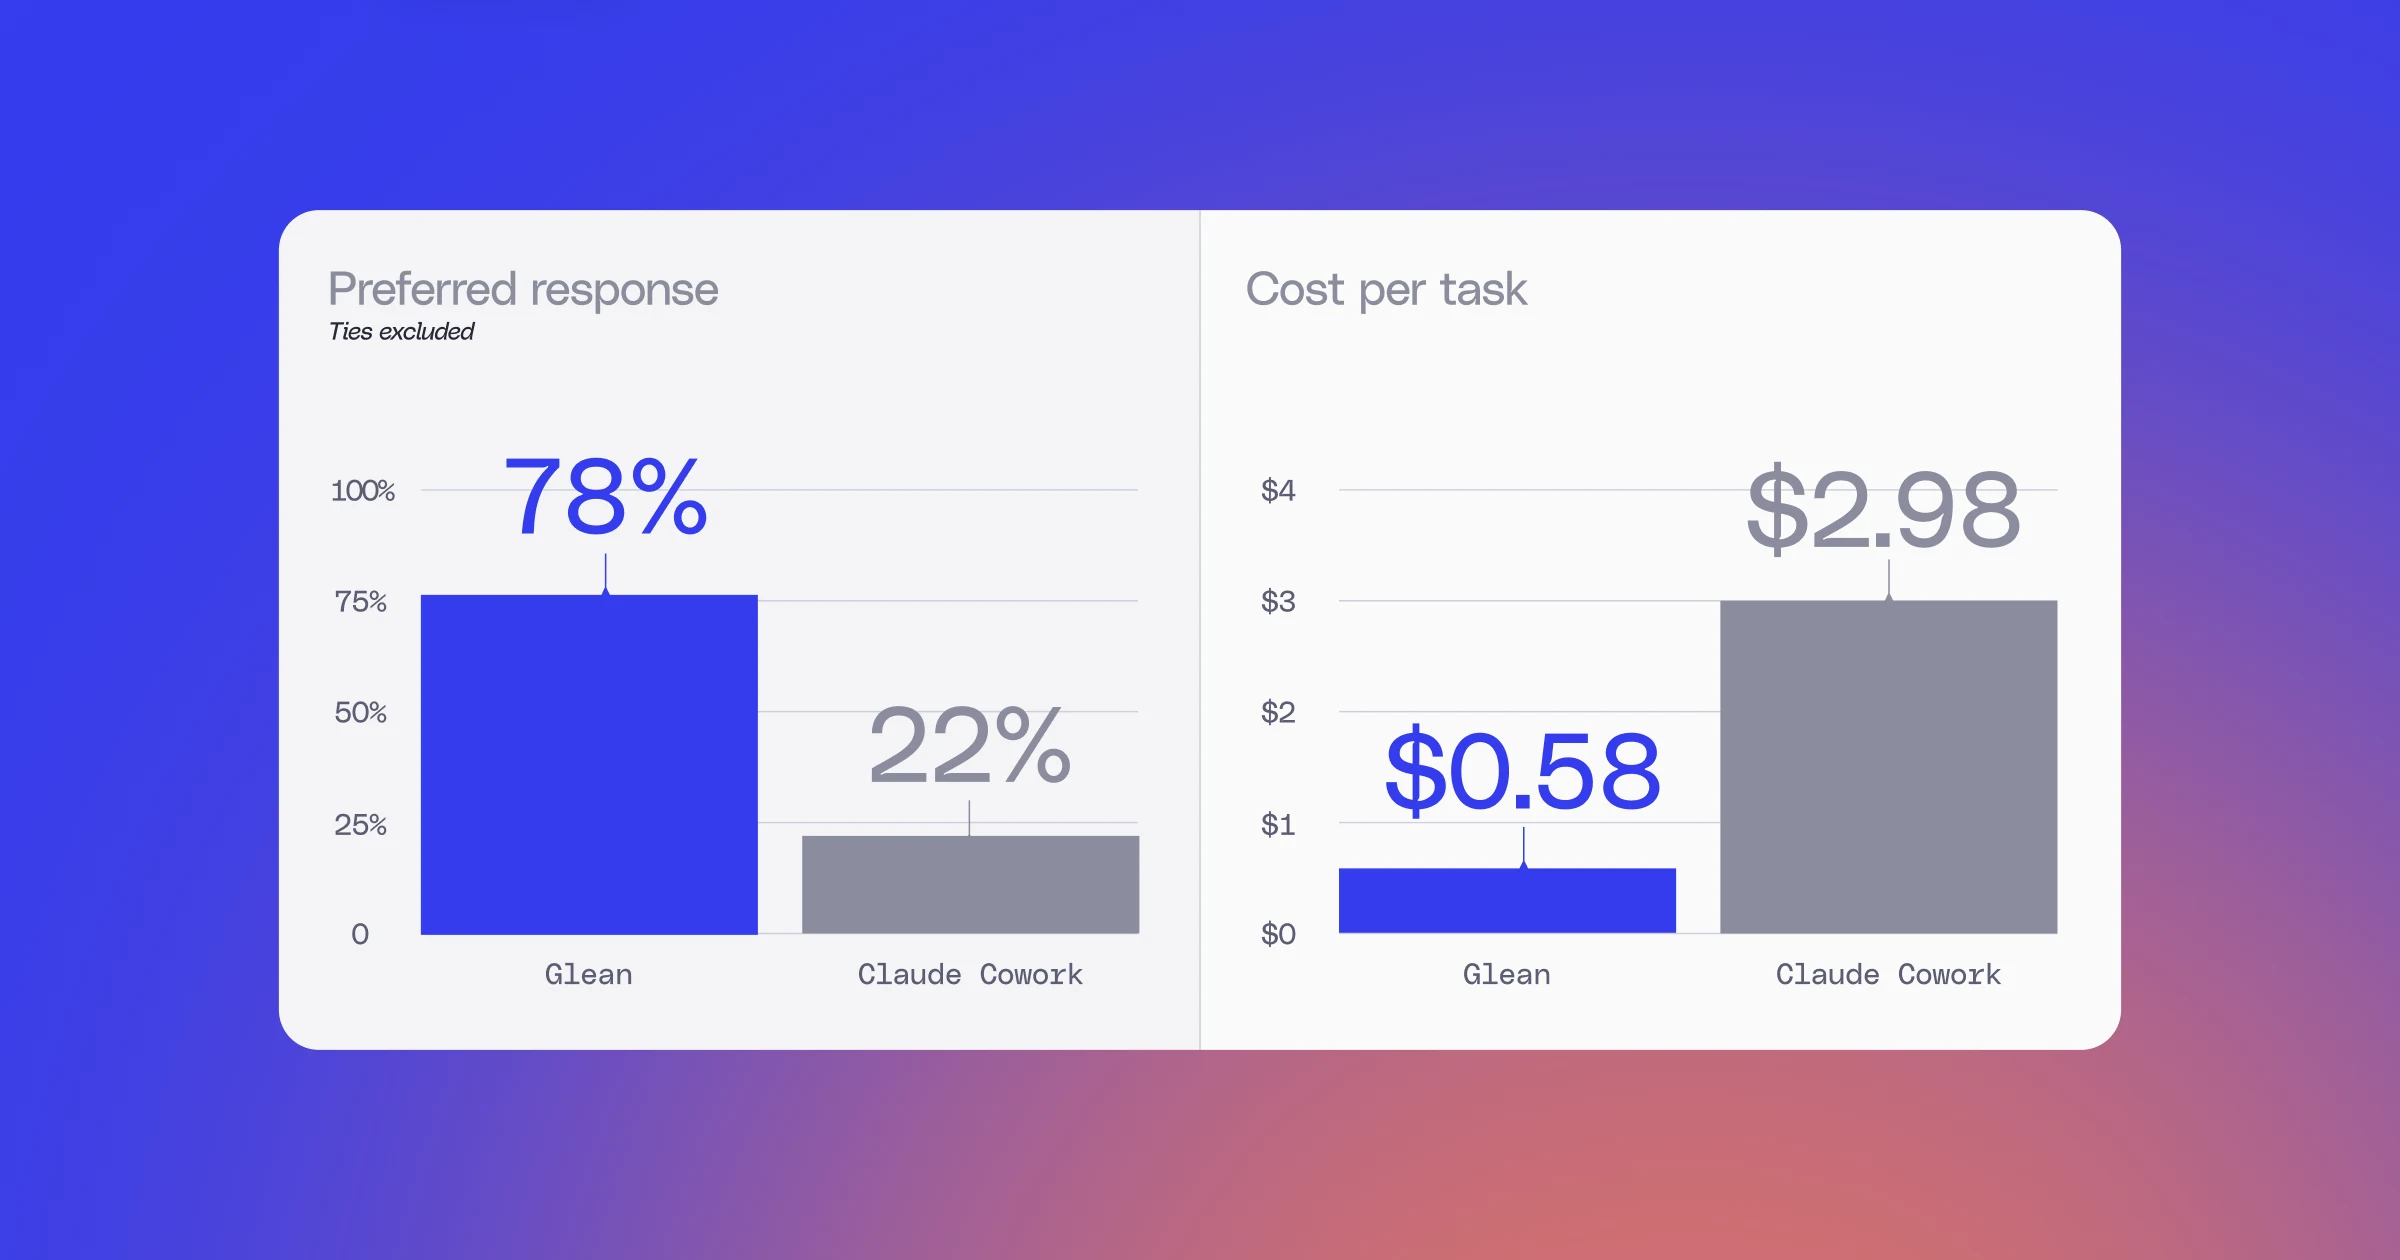
GleanBlog26 AugRight-sizing intelligence: Glean saves 81% on token costs and is preferred 78% of the time versus Claude Cowork
AppleBlog26 AugIDEA Prune: An Integrated Enlarge-and-Prune Pipeline in Generative Language Model Pretraining
NVIDIABlog24 AugHow NVIDIA Groq 3 LPX Unlocks Ultrafast Interactivity at Long Context on NVIDIA Vera Rubin