Blogs
DeepMind logo

DeepMind

Engineering blog · deepmind.google/blog

90posts2this week0watchers

Feature trails

39
Feature trailActive

Gemini 4 Argon Frontier Model

Gemini 4 Argon is now globally available, excelling at deep reasoning for complex, real-world tasks across coding, finance, legal, cybersecurity, and science. It ranks #1 on the Vals Index and offers advanced capabilities in software engineering, enterprise knowledge work, and cybersecurity defense. Key features include a 1M token output limit, enhanced performance on real-world software engineering tasks (DeepSWE v1.1), leading benchmarks in economic impact (Vals Index), and advanced cybersecurity defense capabilities including vulnerability discovery and remediation.

3 posts · 2026

Timeline

Feature trailActive

Gemma 3n Model Series

Gemma 4 is released, expanding the Gemma model series with new sizes (E2B, E4B, 26B MoE, 31B Dense) optimized for advanced reasoning, agentic workflows, and on-device AI. These models offer improved math and instruction-following benchmarks, native support for function-calling and structured JSON output, enhanced code generation, multimodal processing (vision and audio), and longer context windows (up to 256K). The E2B and E4B models are designed for mobile and IoT devices, running offline with EmbeddingGemma 2 providing multimodal embedding capabilities.

3 posts · 2025–2026

Timeline

20252026
Feature trailActive

AI Harmful Manipulation Evaluation

This post introduces SynthID Bio, a watermarking method for synthetic biology that embeds imperceptible signatures into AI-generated biological code (protein sequences and 3D structures). It ensures verifiability on synthesized proteins while preserving biological function. SynthID Bio adapts its approach based on data type, guiding amino acid choices for sequences and adjusting atomic coordinates for 3D structures. Experiments show watermarked protein binders designed with AlphaProteo and a SynthID Bio-enabled ProteinMPNN match the hit rate, binding affinity, and natural sequence diversity of unwatermarked versions. For protein folding, SynthID Bio fine-tunes AlphaFold 3's diffusion network, embedding a detectable signature into model weights without compromising prediction accuracy or structural integrity. The watermarking approach strengthens biosecurity by providing a tangible verification layer for DNA synthesis screening and maintaining the integrity of biological databases. Future work includes making watermarks more robust against tampering, pairing them with metadata approaches, and applying watermarking to more complex biological objects like bacteriophage genomes.

2 posts · 2026

Timeline

Feature trailActive

Live Speech-to-Speech Translation

Gemini models are enhanced for live voice interactions, including improved speech-to-text and speech-to-speech translation. Gemini 3.8 Live and 3.8 Live Extended Thinking offer advancements in near real-time reasoning for voice agents, with improved conversational intelligence, fluid dialogue, visual grounding, and multi-step reasoning. These models support over 97 languages mid-conversation, execute tools and API calls in the background, and provide live progress narration for complex tasks. The Live Avatar feature adds near real-time visual presence to these models, enabling dynamic visual personas with precise lip-syncing, natural expressions, and fluid turn-taking. This allows for richer, more accessible enterprise experiences, asynchronous tool execution with continuous presence, and native multilingual speech-to-speech synchronization across 97 languages. Organizations can also customize avatars to fit brand needs, with safeguards like SynthID watermarking for transparency.

3 posts · 2025–2026

Timeline

20252026
Feature trailActive

Private AI Compute Memory

Private AI Compute architecture is enhanced with a persistent, server-side memory layer that enables cross-device AI continuity while maintaining on-device privacy standards. This is achieved through a secure enclave in the cloud that temporarily decrypts user data for processing and immediately re-encrypts it, with cryptographic keys held exclusively on user devices.

1 post · 2026

Timeline

Feature trailActive

Expressive Text-to-Speech (TTS) Models

Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS are introduced, enhancing voice generation with deep creative direction, character design, and high-volume, cost-efficient scaling. Gemini 3.8 Flash TTS allows for generative voice design from natural language prompts, voice replication from 30-second samples with consent verification and watermarking, and voice remixing. Both models offer granular control over line-by-line delivery, long-form generation, native two-speaker scene staging, and scripted vocal bursts. They achieve leading positions on voice design and quality benchmarks, supporting over 100 languages. The models are integrated into Google AI Studio, Gemini API, Gemini Notebook, and Google Vids, with enterprise offerings coming soon.

4 posts · 2025–2026

Timeline

20252026
Feature trailActive

AI for Biosecurity and Drug Discovery

AlphaGenome Atlas is introduced, a platform containing predictions for the effects of 9 billion single-nucleotide variants in the human genome. It includes the AlphaGenome Variant Impact (AVI) score, which combines AlphaGenome and AlphaMissense predictions, and AVI feature attributions to explain the drivers of the score. The platform is available via a website portal, API, and as a skill in Google Antigravity. It is a massive 1-petabyte dataset, expanding on previous work with AlphaFold.

8 posts · 2026

Timeline

Feature trailActive

Weather Forecasting AI Models

WeatherNext 3 is introduced as the most advanced and accurate global weather model to date, according to independent live evaluations. It learns directly from real-time observations, enabling timely and more localized predictions. The model generates hourly forecasts at multiple spatial resolutions (down to 5km for surface variables), maintaining physical consistency. It ingests live, global geostationary satellite data and sparse weather station observation data, bypassing the six-hour data lag

4 posts · 2025–2026

Timeline

20252026
Feature trailActive

AI-powered vulnerability detection and remediation

Gemini models are enhanced for live voice interactions, including improved speech-to-text and speech-to-speech translation. Gemini 3.8 Live and 3.8 Live Extended Thinking offer advancements in near real-time reasoning for voice agents, with improved conversational intelligence, fluid dialogue, visual grounding, and multi-step reasoning. These models support over 97 languages mid-conversation, execute tools and API calls in the background, and provide live progress narration for complex tasks. The Gemini 3.5 Flash Cyber model is introduced, a lightweight cybersecurity model built on top of 3.5 Flash and fine-tuned to find, validate, and patch vulnerabilities quickly and efficiently. It offers a cost-efficient and highly capable alternative to large, costly cybersecurity models and is integrated into CodeMender for automated vulnerability discovery and remediation. It has demonstrated competitive performance against larger models on benchmarks like CyberGym and Big Sleep, and is being used internally at Google for production commit scanning and vulnerability research.

1 post · 2026

Timeline

Feature trailActive

Gemini Flash Model Series

Gemini 3.1 Pro is released, offering enhanced core reasoning capabilities for complex problem-solving and agentic workflows. It achieves a verified score of 77.1% on the ARC-AGI-2 benchmark, more than doubling the reasoning performance of Gemini 3 Pro. The model is being rolled out across consumer and developer products, including the Gemini app, NotebookLM, Gemini API, Google AI Studio, Gemini CLI, Google Antigravity, Vertex AI, Gemini Enterprise, and Android Studio. Higher limits are available for Pro and Ultra plan users. The release is in preview for developers to validate updates and further advance agentic workflows.

21 posts · 2025–2026

Timeline

20252026
Feature trailActive

Agentic Video Understanding

Agentic video understanding is introduced, enhancing Gemini models (3.7 Flash, 3.6 Flash, 3.5 Flash-Lite) with native video tools for dynamic analysis. This approach reduces costs and token usage while improving accuracy for video processing tasks like sub-second moment retrieval, anomaly detection, and precise counting. It is available via the Gemini API and will be integrated into Google products like the Gemini app and YouTube's 'Ask YouTube' feature.

1 post · 2026

Timeline

Feature trailActive

Generative Media Models (Image and Video)

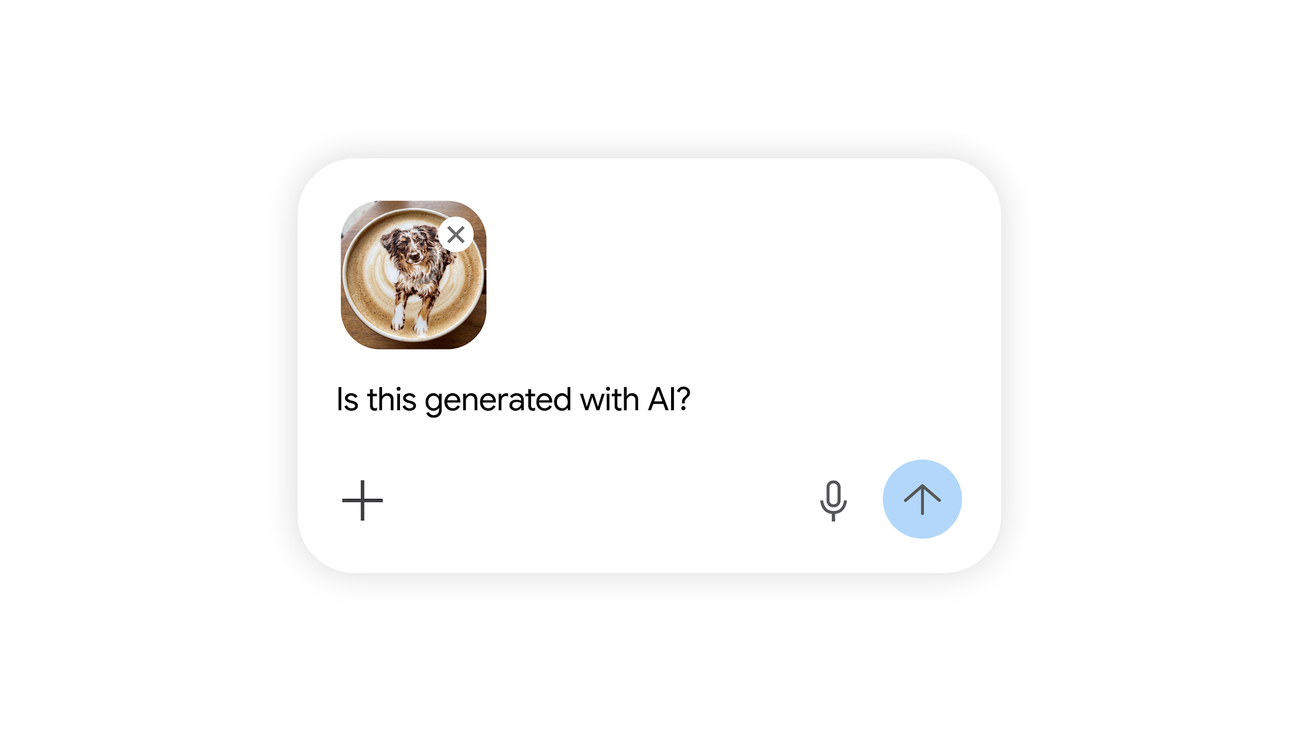
Gemini models are enhanced for live voice interactions, including improved speech-to-text and speech-to-speech translation. Gemini 3.8 Live and 3.8 Live Extended Thinking offer advancements in near real-time reasoning for voice agents, with improved conversational intelligence, fluid dialogue, visual grounding, and multi-step reasoning. These models support over 97 languages mid-conversation, execute tools and API calls in the background, and provide live progress narration for complex tasks. Nano Banana Pro, built on Gemini 3 Pro, offers state-of-the-art image generation and editing with enhanced reasoning, world knowledge, and real-time information integration. It excels at generating accurate, context-rich visuals, including educational explainers, infographics, and diagrams. It also produces images with legible text in multiple languages, supports blending up to 14 images while maintaining consistency of up to 5 people, and offers studio-quality creative controls like localized editing, camera angle adjustments, focus changes, color grading, and scene lighting transformations. It supports aspect ratios and resolutions up to 4K. The technology is integrated across consumer, professional, developer, and enterprise products, including the Gemini app, Google Search, NotebookLM, Google Ads, Google Slides, Vids, Gemini API, Google AI Studio, Google Antigravity, Vertex AI, Gemini Enterprise, Flow, and ProducerAI. All media generated by Google's tools are embedded with SynthID digital watermarks for verification. The Gemini app allows users to upload images and ask if they were generated by Google AI. Free and Google AI Pro tier users will have a visible watermark (Gemini sparkle), while Google AI Ultra subscribers and Google AI Studio users will not have a visible watermark.

14 posts · 2025–2026

Timeline

20252026
Feature trailActive

Generative Video Models (Veo)

Veo continues to evolve with enhanced capabilities for video generation. Veo 3.1 introduces 'Ingredients to Video' with improved expressiveness, character, background, and object consistency, enabling more cohesive narratives. It now supports native vertical outputs for mobile-first content and offers state-of-the-art upscaling to 1080p and 4K resolutions for high-fidelity production. These updates are integrated across consumer and professional platforms, including YouTube Shorts, Gemini app, and now includes personalized video generation, precise motion matching, and the ability to blend live-action and generative footage seamlessly.

1 post · 2025–2026

Timeline

20252026
Feature trailActive

AI Agent Security and Control

The AI Control Roadmap is enhanced with a pilot of the world's first double-blind evaluation for proprietary, frontier-class AI models. This uses cryptographically secure environments (Confidential Space within Google Cloud's Confidential Computing) to prevent benchmark contamination and protect intellectual property. External evaluations are conducted without the model provider seeing test prompts and without evaluators seeing model weights, increasing evaluation integrity for advanced models. The roadmap also details a threat-modelling framework for AI agents, treating them as insider threats, and develops detection and prevention/response mitigations using supervisor AI systems. It measures coverage, recall, and time-to-response. The system scales defenses with AI capabilities, addressing evasion and potential harm by shifting from asynchronous to synchronous response for high-risk actions. A million agent trajectories have been analyzed to refine safety protocols and build live monitors, identifying behavioral patterns beyond keyword filtering. The majority of flagged events stem from misinterpretation or overeagerness, not adversarial intent. The roadmap is being integrated with broader infrastructure and published as a technical framework for policymakers ('Three Layers of Agent Security').

2 posts · 2026

Timeline

Feature trailActive

Sign Language to Text Translation

Sign language AI is brought out of the lab and into consumer products for the first time with a massively multilingual sign-language-to-text (SL2T) translation model. SL2T powers sign-to-text dictation in Gboard and Live Transcribe, starting with American Sign Language (ASL) to English. The model is trained on over 100,000 hours of data across more than 50 sign languages. To protect user privacy, SL2T sees sign language as a sequence of pose landmark locations rather than a raw camera feed. It translates this coordinate sequence directly into text, bypassing intermediate annotations known as "glosses" that are widely used in prior work on sign language translation. SL2T achieves a remarkable zero-shot score of 70 BLEURT on the FLEURS-ASL benchmark. The team worked on practical issues like minimizing streaming latency, preventing hallucination on non-signing inputs, ensuring fairness for left-handed signers, and improving performance for one-handed signing.

1 post · 2026

Timeline

Feature trailActive

Embodied Reasoning for Robotics

Gemini Robotics ER 1.6 enhances embodied reasoning with improved spatial reasoning, multi-view understanding, and instrument reading capabilities. It builds upon previous versions by offering more precise object detection, counting, and success detection, along with the ability to read complex gauges and sight glasses. The model also demonstrates enhanced safety compliance and adherence to physical constraints. It is available via the Gemini API and Google AI Studio.

3 posts · 2026

Timeline

Feature trailActive

AI Educational Assistant for Educators

ATL Saathi, a Gemini-powered web application, serves as a 24/7 planning and training assistant for educators in Atal Tinkering Labs (ATL) across India. It leverages AI to scale high-quality mentorship, shifting focus from physical lab infrastructure to driving innovation and learning outcomes. Key features include streamlined onboarding and content curation via NotebookLM, advanced project generation with step-by-step instructions and wiring diagrams, and multilingual accessibility. The system is powered by Gemini models, including Gemini 3.5 Flash, for generating project ideas and detailed instructions. The rollout is initially to 100 pilot schools.

1 post · 2026

Timeline

Feature trailActive

AI-accelerated planning document analysis

This post introduces a new AI-powered prototype for UK local planning authorities, building on the 'Extract' tool. The prototype acts as an assistant for planning officers, automating data extraction, policy identification, feedback summarization, and initial report drafting for householder planning applications. The goal is to halve decision times for these applications. The system consolidates data, highlights relevant policies with citations, summarizes consultation feedback, and drafts asses

1 post · 2026

Timeline

Feature trailActive

AI-accelerated mathematical discovery

AI-accelerated mathematical discovery continues to advance, with systems like AlphaProof and Gemini's Deep Think mode achieving medal-standard performance in mathematical olympiads. These systems leverage techniques pioneered by AlphaGo, such as reinforcement learning and search algorithms, to prove formal mathematical statements and solve complex, open-ended challenges. The development of AI co-scientists further enhances this capability by enabling agents to debate scientific ideas and identify new mathematical problems. This initiative expands this by partnering with leading research institutions to build infrastructure and tools for AI-driven mathematical research.

2 posts · 2025–2026

Timeline

20252026
Feature trailActive

AlphaEvolve AI Coding Agent

AlphaEvolve continues to scale its impact across diverse fields, including scientific research, AI infrastructure optimization, and commercial applications. Recent advancements include its integration into the design of next-generation TPUs, optimization of Google Spanner's LSM-tree compaction heuristics, and discovery of more efficient cache replacement policies. Commercially, it has been applied to accelerate transformer model training, optimize computational libraries, and solve complex routing challenges.

4 posts · 2026

Timeline

Feature trailActive

Image Provenance and Context Analysis

Backstory is an experimental AI tool that investigates the context and origin of images seen online. It determines if an image is AI-generated, when and where it's previously been used online, and whether it's been digitally altered. It combines detection technologies with a holistic assessment of the context of the image, including metadata and usage history, to provide users with information about an image's trustworthiness and how its story may have changed over time. This post details the expansion of SynthID watermarking and the introduction of Backstory.

1 post · 2025–2026

Timeline

20252026
Feature trailActive

Interactive World Models

Genie 3 advances interactive world models by generating dynamic, navigable environments at 720p resolution with real-time interaction at 24 FPS, maintaining consistency for several minutes. It introduces 'promptable world events' for environmental interventions and demonstrates compatibility with embodied agents like SIMA for complex goal achievement. Limitations include a constrained agent action space, challenges in multi-agent simulation, imperfect real-world location accuracy, inconsistent text rendering, and limited interaction duration.

1 post · 2025–2026

Timeline

20252026
Feature trailActive

Project Genie World Generation with Street View Grounding

SIMA 2 integrates Gemini models to evolve from an instruction-follower into an interactive gaming companion. It can now reason about goals, converse with users, and improve itself over time. SIMA 2 demonstrates improved generalization and reliability, understanding more complex instructions and performing better in unseen games. It can also understand multimodal prompts, different languages, and emojis. SIMA 2's self-improvement capability allows it to learn through trial-and-error and Gemini-based feedback. When combined with Genie 3, SIMA 2 can sensibly orient itself, understand user instructions, and take meaningful actions toward goals in newly generated worlds.

5 posts · 2025–2026

Timeline

20252026
Feature trailActive

AI Co-clinician Research Initiative

The AI Co-clinician research initiative continues to explore how AI can augment physician expertise and improve patient care. This involves developing AI agents that can function as collaborative members of the care team, interacting with patients under clinical supervision. Research focuses on clinician-facing support, including evidence synthesis and medication knowledge, as well as patient-facing multimodal capabilities using live audio and video for telemedical settings. Safeguards include a

3 posts · 2026

Timeline

Feature trailActive

AI-enabled Pointer Interaction

This post introduces an AI-enabled pointer that reimagines mouse pointer interaction by understanding context and intent. It aims to provide seamless AI collaboration across applications without interrupting user flow. Key principles include maintaining user flow, enabling 'show and tell' interactions, embracing natural shorthand with 'this' and 'that', and transforming pixels into actionable entities. The technology is being integrated into Chrome (Gemini in Chrome) and Googlebook (Magic Pointer).

1 post · 2026

Timeline

Feature trailActive

Distributed AI Training Infrastructure

Decoupled DiLoCo is a new distributed AI training architecture that enables training LLMs across distant data centers with lower bandwidth and increased hardware resiliency. It divides training runs into decoupled 'islands' of compute with asynchronous data flow, isolating local disruptions and allowing other parts of the system to continue learning efficiently. This approach builds on Pathways and DiLoCo, offering fault-tolerant asynchronous training at scale. It has demonstrated greater availability of learning clusters than traditional methods and can mix different hardware generations in a single training run.

1 post · 2026

Timeline

Feature trailActive

AI for Scientific Discovery and Reasoning

This feature thread tracks the evolution of AI systems and techniques applied to accelerate scientific discovery, mathematical reasoning, and algorithm development. It encompasses breakthroughs like AlphaGo, AlphaFold, AlphaZero, AlphaProof, Gemini's Deep Think, and AI co-scientists, highlighting their impact on fields ranging from game playing to protein folding, mathematics, and general scientific collaboration. The thread also covers the foundational AI principles and architectures that enable these advancements, with a focus on their progression towards Artificial General Intelligence (AGI).

1 post · 2026

Timeline

Feature trailActive

Gemini Deep Think Reasoning Engine

Gemini Deep Think continues to advance its abstract problem-solving capabilities, achieving gold-medal level performance in both the International Mathematical Olympiad and the International Collegiate Programming Contest (ICPC) World Finals. This year, an advanced version of Gemini Deep Think solved five out of the six IMO problems perfectly, earning 35 total points, and achieving gold-medal level performance. The model operated end-to-end in natural language, producing rigorous mathematical proofs directly from the official problem descriptions within the competition time limit. This version of Gemini was trained on novel reinforcement learning techniques that leverage multi-step reasoning, problem-solving, and theorem-proving data, and was provided with access to a curated corpus of high-quality solutions to mathematics problems, along with hints and tips on how to approach IMO problems. A version of this Deep Think model will be made available to trusted testers and then rolled out to Google AI Ultra subscribers.

7 posts · 2025–2026

Timeline

20252026
Feature trailActive

4D Scene Reconstruction and Tracking

D4RT is a unified AI model for 4D scene reconstruction and tracking across space and time. It unifies dynamic scene reconstruction into a single, efficient framework, bringing us closer to total perception of our dynamic reality. D4RT operates as a unified encoder-decoder Transformer architecture. The encoder first processes the input video into a compressed representation of the scene's geometry and motion. Unlike older systems that employed separate modules for different tasks, D4RT calculates only what it needs using a flexible querying mechanism centered around a single, fundamental question: "Where is a given pixel from the video located in 3D space at an arbitrary time, as viewed from a chosen camera?" Building on prior work, a lightweight decoder then queries this representation to answer specific instances of the posed question. Because queries are independent, they can be processed in parallel on modern AI hardware. This makes D4RT extremely fast and scalable, whether it's tracking just a few points or reconstructing an entire scene. With this flexible formulation, a wide variety of 4D tasks can now be solved by the model, including: Point Tracking, Point Cloud Reconstruction, and Camera Pose Estimation. D4RT outperforms previous methods across a wide spectrum of 4D reconstruction tasks, maintaining a solid, continuous understanding of the moving world. Crucially, D4RT's precision does not come at the expense of efficiency. In testing, it performed 18x to 300x faster than the previous state of the art. For example, D4RT processed a one-minute video in roughly five seconds on a single TPU chip. Previous state-of-the-art methods could take up to ten minutes for the same task — an improvement of 120x. D4RT demonstrates that we don't need to choose between accuracy and efficiency in 4D reconstruction. Its flexible, query-based system can capture our dynamic world in real-time, paving the way for the next generation of spatial computing. This includes applications in Robotics, Augmented Reality (AR), and World Models. We're continuing to explore the model's capabilities and potential for applications across robotics, augmented reality, and beyond.

1 post · 2026

Timeline

Feature trailActive

LLM Interpretability Tools

Gemma Scope 2 is released, a comprehensive, open suite of interpretability tools for all Gemma 3 model sizes (270M to 27B parameters). It enables tracing potential risks across the model's internal workings by combining sparse autoencoders (SAEs) and transcoders. New features include full coverage at scale for larger models, skip-transcoders and cross-layer transcoders for deciphering multi-step computations, advanced training techniques like Matryoshka, and targeted tools for analyzing chatbot behavior.

1 post · 2025

Timeline

20252026
Feature trailActive

LLM Factuality Benchmarking

The FACTS Benchmark Suite is introduced, extending previous work on factuality evaluation. It includes three new benchmarks: Parametric (measuring internal knowledge accuracy), Search (testing tool use for information retrieval and synthesis), and Multimodal (evaluating factually accurate responses to image-based prompts). The original FACTS Grounding benchmark has also been updated to v2. The suite comprises 3,513 examples, with a held-out private set managed by Kaggle. Gemini 3 Pro achieves a 68.8% overall FACTS score, with significant improvements in Search & Parametric slices.

1 post · 2025

Timeline

20252026
Feature trailActive

Protein Structure Prediction for Drug Discovery

AlphaFold continues to be a foundational tool for scientific discovery, enabling researchers to map complex protein structures. This post highlights its application in understanding glycerate kinase (GLYK), a key enzyme in photosynthesis, and engineering more heat-tolerant crops by modifying its structure. The integration of AlphaFold predictions with molecular simulations has proven to be a powerful methodology for achieving insights into enzyme stability under heat stress, leading to the development of a method to map the structure of apoB100, the key protein behind "bad cholesterol" (LDL). This discovery provides a detailed view of the protein's cage-like shell and ribbon-like belt, opening new avenues for precise therapies targeting LDL and the treatment of atherosclerotic cardiovascular disease (ASCVD).

3 posts · 2025

Timeline

20252026
Feature trailActive

AI Visual Representation Alignment

This post introduces a novel multi-step method for aligning AI visual representations with human knowledge. The approach involves training a teacher model on human judgments (THINGS dataset), generating a large synthetic dataset (AligNet) of human-like decisions, and then fine-tuning student AI models on this synthetic data. This process significantly improves model robustness, generalization, and human-alignment on various visual tasks, including few-shot learning and distribution shift.

1 post · 2025

Timeline

20252026
Feature trailActive

AlphaEarth Foundations Geospatial AI

AlphaEarth Foundations integrates petabytes of Earth observation data (optical satellite images, radar, 3D laser mapping, climate simulations) into a unified digital representation (embeddings) for global mapping and monitoring. It analyzes land and coastal waters in 10x10 meter squares with high precision and tracks changes over time. The model achieves a 24% lower error rate compared to traditional and other AI mapping systems, excelling in scenarios with scarce label data. The Satellite Embedding dataset is released in Google Earth Engine.

2 posts · 2025

Timeline

20252026
Feature trailActive

Perch Bioacoustics Analysis Model

The Perch model is updated with state-of-the-art off-the-shelf bird species predictions and improved adaptation to new environments, particularly underwater. It is trained on a wider range of animals and anthropogenic noise, using nearly twice as much data. The model can disentangle complex acoustic scenes over thousands or millions of hours of audio data and answer diverse ecological questions. Its vector search library is integrated into tools like Cornell's BirdNet Analyzer, and it enables agile modeling for rapid classifier creation.

1 post · 2025

Timeline

20252026
Feature trailActive

MedGemma Health AI Models

MedGemma represents a new family of open models specifically designed for health AI development, building upon the Gemma architecture. These models are trained on a vast corpus of biomedical and health-related data, enabling them to perform advanced tasks such as medical question answering, summarization of clinical notes, and potentially assisting in diagnostic reasoning. The focus is on providing researchers and developers with capable, open-source tools to accelerate innovation in healthcare

1 post · 2025

Timeline

20252026
Feature trailCooling

AI for Fluid Dynamics Research

This post introduces a novel method for discovering new families of unstable singularities in fluid dynamics equations using AI techniques, specifically Physics-Informed Neural Networks (PINNs) and second-order optimizers. This approach pushes the boundaries of accuracy in mathematical research, enabling computer-assisted proofs and tackling long-standing challenges in mathematics, physics, and engineering.

1 post · 2025

Timeline

20252026
Feature trailCooling

Deep Loop Shaping for Gravitational Wave Observatories

Deep Loop Shaping is a novel AI method that improves control of gravitational wave observatories by reducing noise and stabilizing feedback systems. It has been proven to reduce noise levels in LIGO's mirror control loops by 30 to 100 times, enabling more detailed detection and gathering of data about cosmic events. This technology has potential applications in aerospace, robotics, and structural engineering for vibration suppression and noise cancellation.

1 post · 2025

Timeline

20252026
Feature trailCooling

AI for Historical Textual Analysis

Aeneas is an AI model for contextualizing ancient inscriptions, designed to help historians interpret, attribute, and restore fragmentary texts. It reasons across thousands of Latin inscriptions, retrieving textual and contextual parallels in seconds. It can also process multimodal input (text and images) to determine geographical provenance and restore gaps of unknown length. The model sets new benchmarks in restoring damaged texts and predicting when and where they were written. The Ithaca model is upgraded to be powered by Aeneas and include the contextualization function, restorations of unknown length and better performance overall.

1 post · 2025

Timeline

20252026