Solving MapReduce Performance Problems With Sharded Joins
Dec 1, 2014Noel Cody
Summary
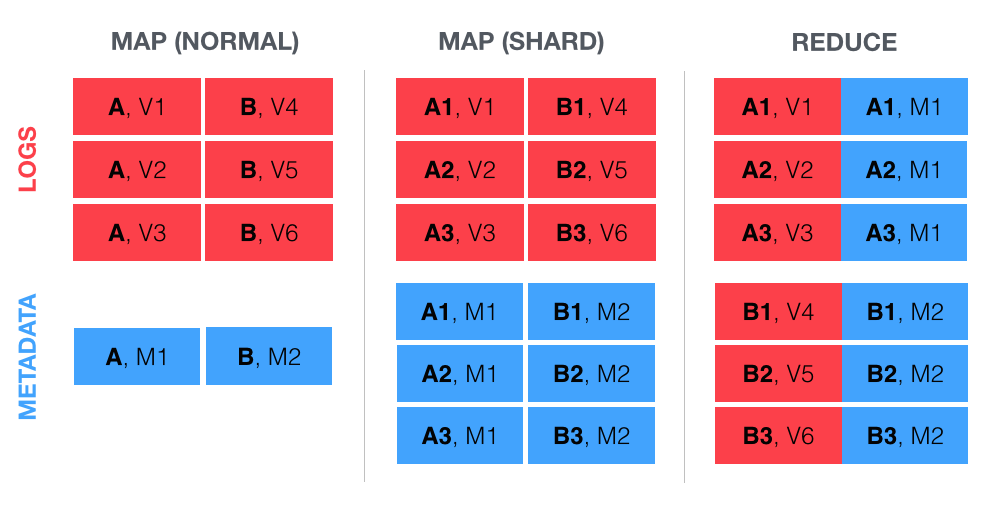
This post details the implementation of a sharded join strategy in Apache Crunch to address performance problems in a MapReduce pipeline caused by skewed data. When a standard join resulted in overloaded reducers and high memory usage, a sharded join was introduced. This involved splitting the key space of the larger dataset and replicating the smaller dataset to distribute the join load across more reducers. The post provides code examples for implementing this strategy from scratch when the built-in Crunch library had a bug. The solution successfully reduced memory usage by over 75% and revived the pipeline.
More from the Data Lake Indexing for Point Queries trail
- Indexing the Data Lake for Online Point Queries | Spotify Engineering
- Encoding Your Domain Expert: The Context Layer Behind Spotify's Data Assistant | Spotify Engineering
- How Spotify Optimized the Largest Dataflow Job Ever for Wrapped 2020
- It’s All Just Wiggly Air: Building Infrastructure to Support Audio Research
- How We Improved Data Discovery for Data Scientists at Spotify