TechPrufer
InterviewBlogEngineering
Sign inGet started
TechPrufer
Feed
CareerApplicationsTailor
ResourcesInterview QuestionsSalaries
Engineering Notes
Library
SavedHistory
Save your progress

Sign in to save posts, track applications and tailor resumes.

Sign in
Explore

GPU Optimization

Explore
GO

GPU Optimization

15 posts · 10 sources
Databricks logoDatabricksHugging Face logoHugging FaceLinkedIn logoLinkedInNVIDIA logoNVIDIAModal logoModalBaseten logoBasetenCursor logoCursorTogether AI logoTogether AI+2
Databricks logoDatabricksBlog4 Sept

Achieving Extreme Efficiency through Specialized GPU Kernel Generation

Hugging Face logoHugging FaceBlog24 Aug

Accelerating Transformers Fine-Tuning with NVIDIA NeMo AutoModel

LinkedIn logoLinkedInBlog6 Aug

The training infrastructure behind AI-Powered Job Search: 8X faster multi-teacher distillation

NVIDIA logoNVIDIABlog24 Jun

Accelerating BEV Pooling on NVIDIA GPUs for Physical AI Applications

Modal logoModalBlog24 Jun

Achieve state-of-the-art inference latencies with speculative decoding
Baseten logoBasetenBlog18 May

Sub-second image generation with Flux.2 and Qwen-Image

Cursor logoCursorBlog14 Apr

Speeding up GPU kernels by 38% with a multi-agent system
Together AI logoTogether AIBlog1 Apr

Inside the Together AI kernels team

Shopify logoShopifyBlog27 Feb

2,000 robots walk into a shop: Simulated A/B testing (2026)

Together AI logoTogether AIBlog1 Dec

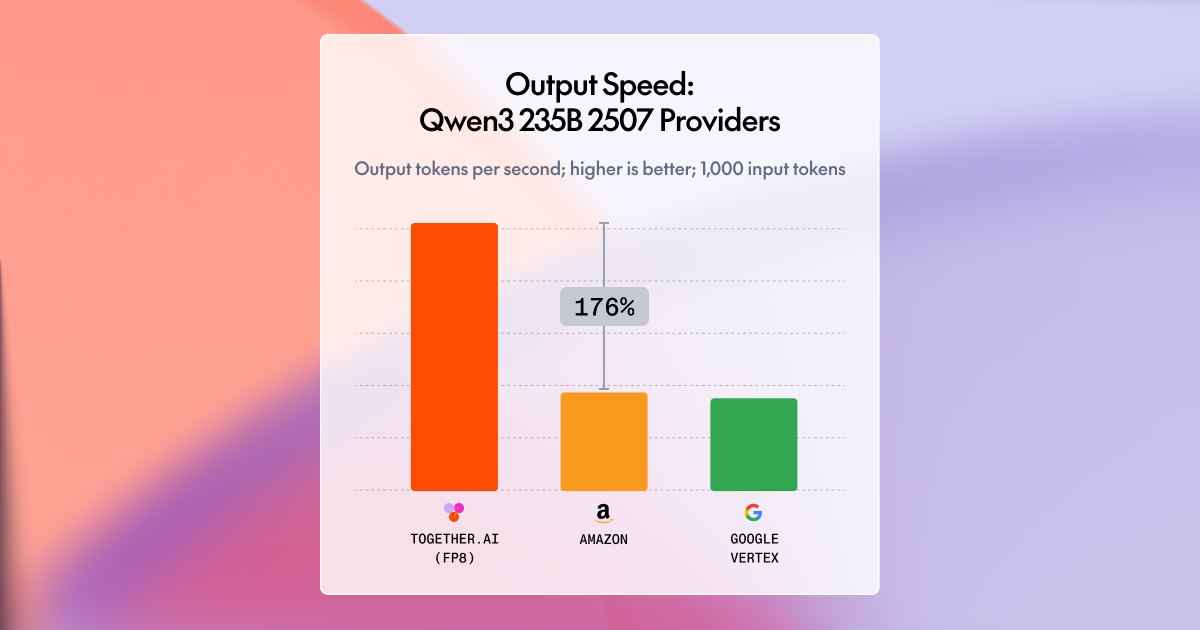
Together AI delivers fastest inference for the top open-source models

Meta logoMetaBlog10 Nov

Meta’s Generative Ads Model (GEM): The Central Brain Accelerating Ads Recommendation AI Innovation

Baseten logoBasetenBlog7 Aug

How we run GPT OSS 120B at 500+ tokens per second on NVIDIA GPUs

Baseten logoBasetenBlog7 Mar

FP8: Efficient model inference with 8-bit floating point numbers

Meta logoMetaBlog15 Jul

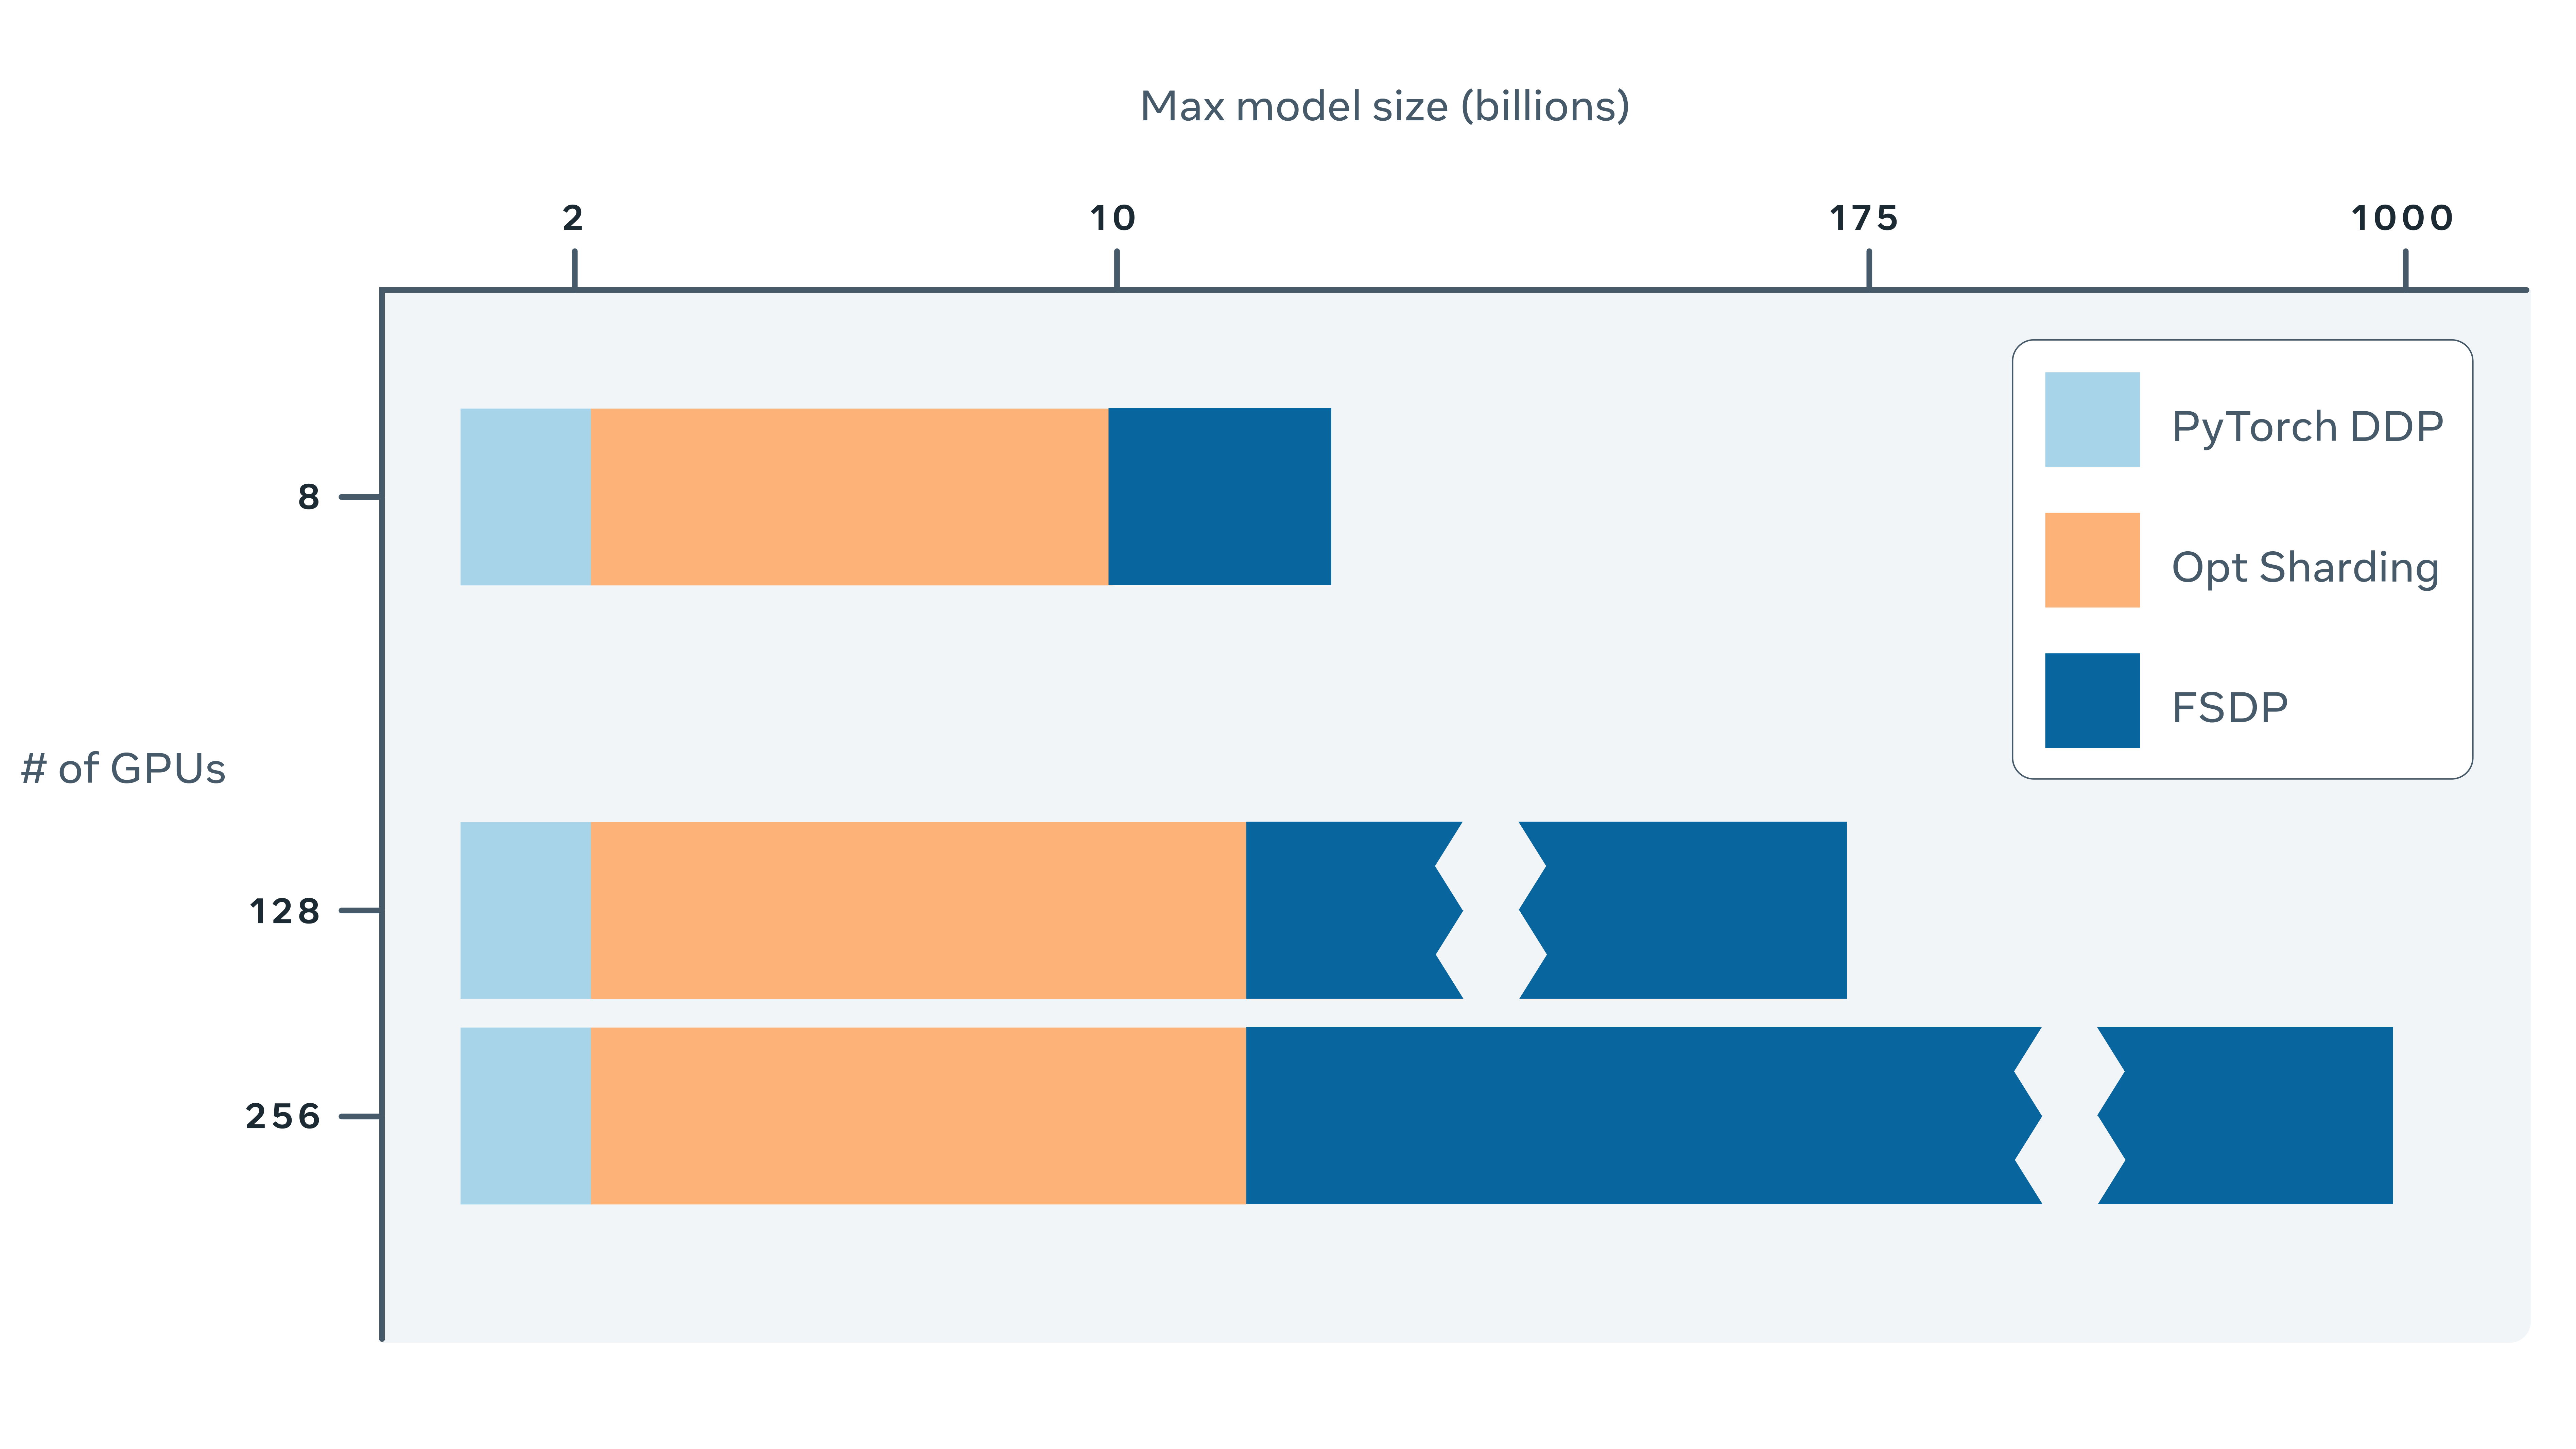
Fully Sharded Data Parallel: faster AI training with fewer GPUs

Meta logoMetaBlog25 Oct

Building an efficient neural language model over a billion words

Related topics

LLM InferenceSpeculative DecodingKernel OptimizationQuantizationLatency reductionAI PerformanceNVIDIA NeMoFine-tuning

Sources writing about it

Databricks logoDatabricksHugging Face logoHugging FaceLinkedIn logoLinkedInNVIDIA logoNVIDIAModal logoModalBaseten logoBasetenCursor logoCursorTogether AI logoTogether AI+2

In your feed

Follow GPU Optimization week by week in the Feed.

Open in Feed

Interview questions

All companies
  • M
    Meta interview questions
  • U
    Uber interview questions
  • A
    Apple interview questions
  • S
    Stripe interview questions
  • N
    Netflix interview questions
  • A
    Anthropic interview questions
  • G
    Google interview questions
  • A
    Amazon interview questions

Salaries

All salaries
  • M
    Microsoft salaries
  • A
    Amazon salaries
  • G
    Google salaries
  • S
    Salesforce salaries
  • O
    Oracle salaries
  • P
    PayPal salaries
  • G
    Goldman Sachs salaries
  • A
    Adobe salaries

Product

  • Resume Editor
  • Job Tailor
  • Application Tracker
  • LinkedIn Improver
  • Chrome Extension
© 2026 TechPrufer · techprufer.com
TermsPrivacy
FeedCareerResourcesBlogs