Explore CoreweaveBlog
 AppleBlog
 AI EngineerYouTube
 NVIDIABlog
 GoogleBlog
 MetaBlog
NVIDIABlog NVIDIABlog  LambdaBlog
NVIDIABlog CoreweaveBlog
CoreweaveBlog CoreweaveBlog CoreweaveBlog CoreweaveBlog  UberBlog
 BasetenBlog
MetaBlog  Hugging FaceBlog
 CerebrasBlog
LLM Training
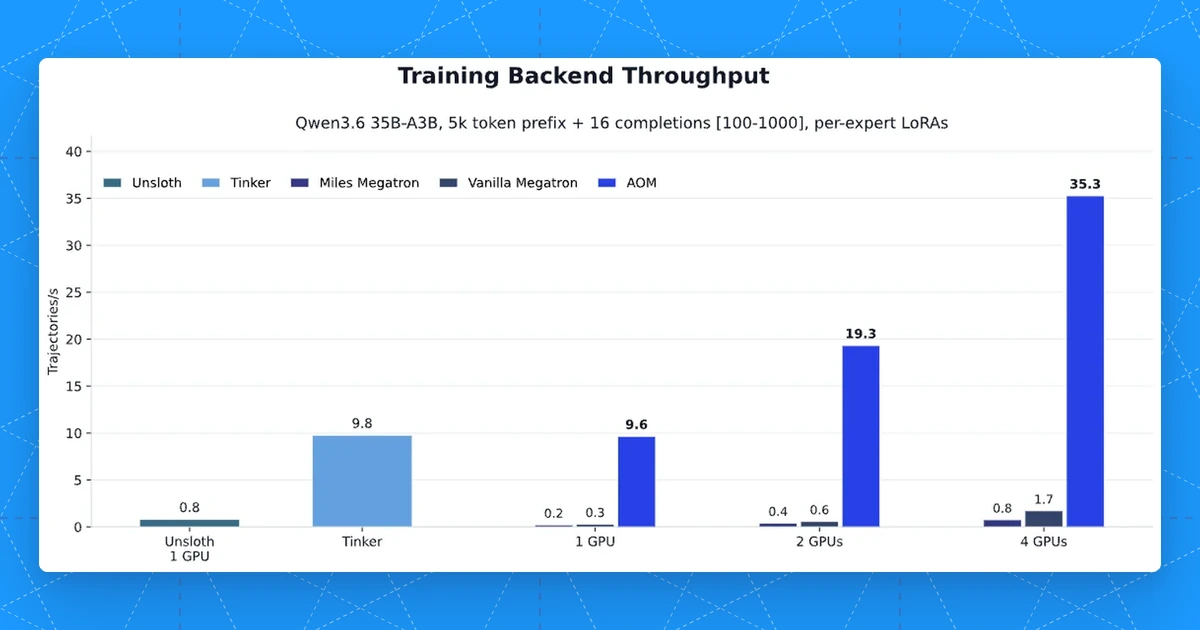
SCLATE: A Substrate for Continual-Learning Agent Training and Evaluation
 AI EngineerYouTube