AI EngineerYouTube
ExploreAI EngineerYouTube  GoogleBlog
 BasetenBlog
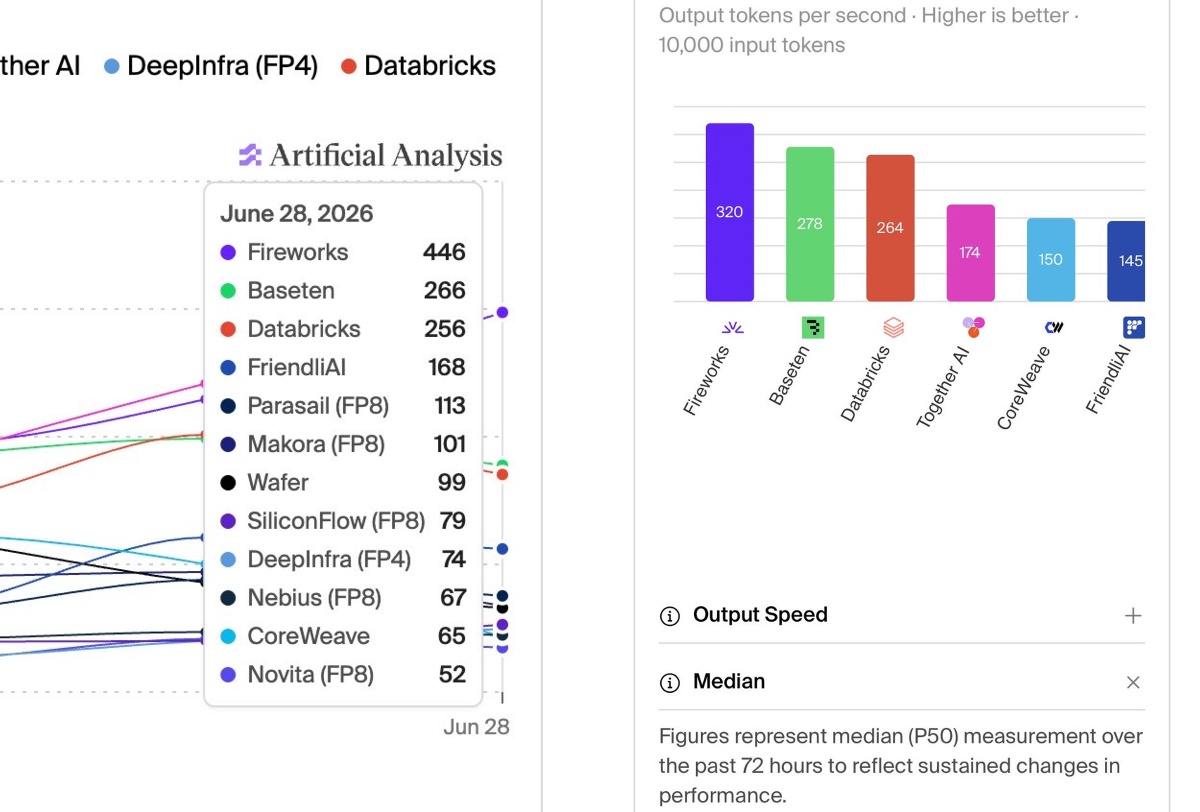
 Fireworks AIBlog
 AppleBlog
Fireworks AIBlog BasetenBlog  NVIDIABlog
Fireworks AIBlog  Together AIBlog
BasetenBlog BasetenBlog  CerebrasBlog
Sparse Attention
AI EngineerYouTubeAI EngineerYouTube