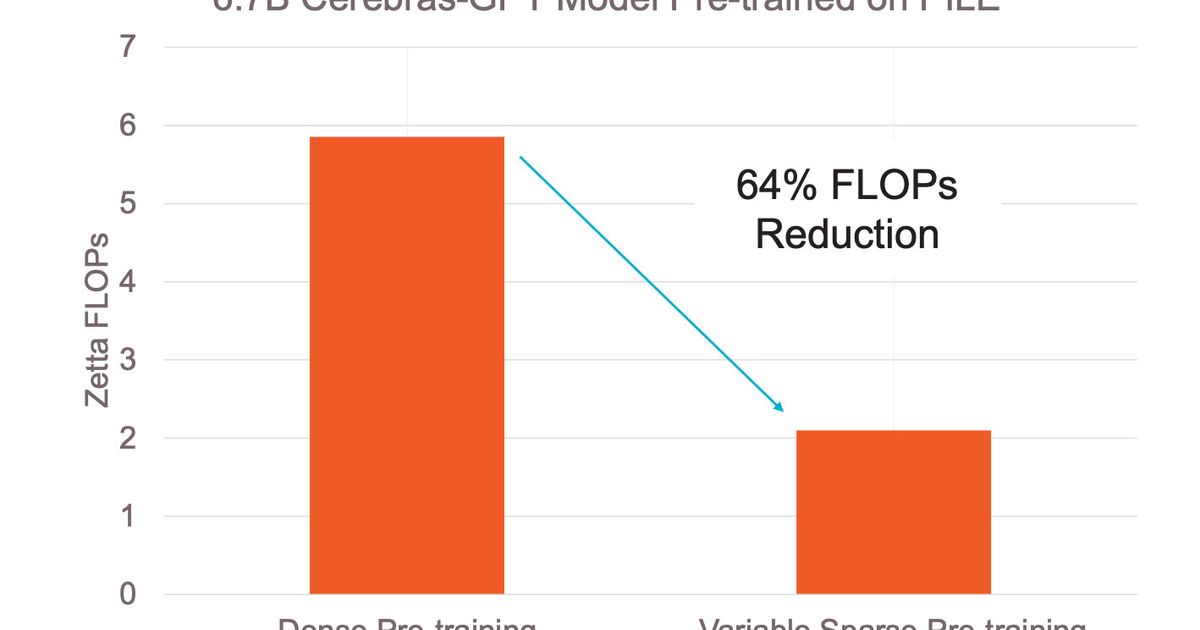
CerebrasBlog11 MarAccelerating Large GPT Training with Sparse Pre-Training and Dense Fine-Tuning [Updated]
CerebrasBlog11 MarScaling Up and Out: Training Massive Models on Cerebras Systems using Weight Streaming
CerebrasBlog4 MarAccelerating Large Language Model Training with Variable Sparse Pre-training and Dense Fine-tuning
CerebrasBlog4 MarCerebras and Qualcomm Unleash ~10X Inference Performance Boost with Hardware-Aware LLM Training
 CerebrasBlogCerebrasBlogCerebrasBlogCerebrasBlogCerebrasBlogCerebrasBlogCerebrasBlogCerebrasBlog