Helix: A Vision-Language-Action Model for Generalist Humanoid Control
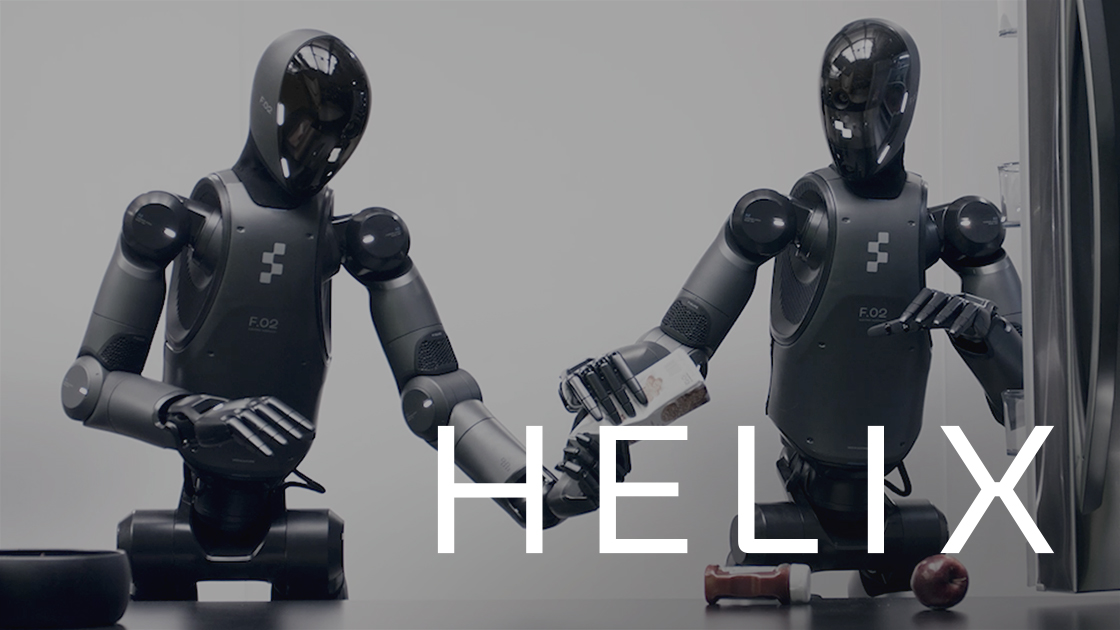
This post introduces Helix, a Vision-Language-Action (VLA) model that achieves full-upper-body control (35-DoF at 200Hz) for humanoid robots. It employs a 'System 1, System 2' architecture where System 2 (a VLM) handles high-level scene understanding and language comprehension at 7-9 Hz, and System 1 (a visuomotor transformer) translates these into precise continuous actions at 200 Hz. This decoupled approach allows for fast, reactive control while leveraging general semantic knowledge. Key contributions include zero-shot generalization to novel objects and multi-robot collaboration, enabled by end-to-end training on a multi-robot dataset and optimized inference on embedded GPUs. The architecture avoids complex action tokenization and allows for immediate commercial deployment.